Recently, someone was telling me about a book they’d read on Karl Schwarzschild. Schwarzschild is famous for discovering the equations that describe black holes, based on Einstein’s theory of gravitation. To make the story more dramatic, he did so only shortly before dying from a disease he caught fighting in the first World War. But this person had the impression that Schwarzschild had done even more. According to this person, the book said that Schwarzschild had done something to prove Einstein’s theory, or to complete it.
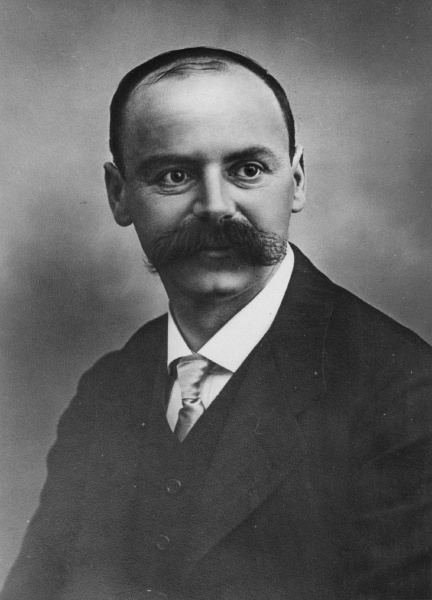
Another Schwarzschild accomplishment: that mustache
At first, I thought the book this person had read was wrong. But after some investigation, I figured out what happened.
The book said that Schwarzschild had found the first exact solution to Einstein’s equations. That’s true, and as a physicist I know precisely what it means. But I now realize that the average person does not.
In school, the first equations you solve are algebraic, x+y=z. Some equations, like x^2=4, have solutions. Others, like x^2=-4, seem not to, until you learn about new types of numbers that solve them. Either way, you get used to equations being like a kind of puzzle, a question for which you need to find an answer.
If you’re thinking of equations like that, then it probably sounds like Schwarzschild “solved the puzzle”. If Schwarzschild found the first solution to Einstein’s equation, that means that Einstein did not. That makes it sound like Einstein’s work was incomplete, that he had asked the right question but didn’t yet know the right answer.
Einstein’s equations aren’t algebraic equations, though. They’re differential equations. Instead of equations for a variable, they’re equations for a mathematical function, a formula that, in this case, describes the curvature of space and time.
Scientists in many fields use differential equations, but they use them in different ways. If you’re a chemist or a biologist, it might be that you’re most used to differential equations with simple solutions, like sines, cosines, or exponentials. You learn how to solve these equations, and they feel a bit like the algebraic ones: you have a puzzle, and then you solve the puzzle.
Other fields, though, have tougher differential equations. If you’re a physicist or an engineer, you’ve likely met differential equations that you can’t treat in this way. If you’re dealing with fluid mechanics, or general relativity, or even just Newtonian gravity in an odd situation, you can’t usually solve the problem by writing down known functions like sines and cosines.
That doesn’t mean you can’t solve the problem at all, though!
Even if you can’t write down a solution to a differential equation with sines and cosines, a solution can still exist. (In some cases, we can even prove a solution exists!) It just won’t be written in terms of sines and cosines, or other functions you’ve learned in school. Instead, the solution will involve some strange functions, functions no-one has heard of before.
If you want, you can make up names for those functions. But unless you’re going to classify them in a useful way, there’s not much point. Instead, you work with these functions by approximation. You calculate them in a way that doesn’t give you the full answer, but that does let you estimate how close you are. That’s good enough to give you numbers, which in turn is good enough to compare to experiments. With just an approximate solution, like this, Einstein could check if his equations described the orbit of Mercury.
Once you know you can find these approximate solutions, you have a different perspective on equations. An equation isn’t just a mysterious puzzle. If you can approximate the solution, then you already know how to solve that puzzle. So we wouldn’t think of Einstein’s theory as incomplete because he was only able to find approximate solutions: for a theory as complicated as Einstein’s, that’s perfectly normal. Most of the time, that’s all we need.
But it’s still pretty cool when you don’t have to do this. Sometimes, we can not just approximate, but actually “write down” the solution, either using known functions or well-classified new ones. We call a solution like that an analytic solution, or an exact solution.
That’s what Schwarzschild managed. These kinds of exact solutions often only work in special situations, and Schwarzschild’s is no exception. His Schwarzschild solution works for matter in a special situation, arranged in a perfect sphere. If matter happened to be arranged in that way, then the shape of space and time would be exactly as Schwarzschild described it.
That’s actually pretty cool! Einstein’s equations are complicated enough that no-one was sure that there were any solutions like that, even in very special situations. Einstein expected it would be a long time until they could do anything except approximate solutions.
(If Schwarzschild’s solution only describes matter arranged in a perfect sphere, why do we think it describes real black holes? This took later work, by people like Roger Penrose, who figured out that matter compressed far enough will always find a solution like Schwarzschild’s.)
Schwarzschild intended to describe stars with his solution, or at least a kind of imaginary perfect star. What he found was indeed a good approximation to real stars, but also the possibility that a star shoved into a sufficiently small space would become something weird and new, something we would come to describe as a black hole. That’s a pretty impressive accomplishment, especially for someone on the front lines of World War One. And if you know the difference between an exact solution and an approximate one, you have some idea of what kind of accomplishment that is.
Nowadays, we have telescopes that detect not just light, but gravitational waves. We’ve already learned quite a bit about astrophysics from these telescopes. They observe ripples coming from colliding black holes, giving us a better idea of what kinds of black holes exist in the universe. But the coolest thing a gravitational wave telescope could discover is something that hasn’t been seen yet: a cosmic string.
This art is from an article in Symmetry magazine which is, as far as I can tell, not actually about cosmic strings.
You might have heard of cosmic strings, but unless you’re a physicist you probably don’t know much about them. They’re a prediction, coming from cosmology, of giant string-like objects floating out in space.
That might sound like it has something to do with string theory, but it doesn’t actually have to, you can have these things without any string theory at all. Instead, you might have heard that cosmic strings are some kind of “cracks” or “wrinkles” in space-time. Some articles describe this as like what happens when ice freezes, cracks forming as water settles into a crystal.
That description, in terms of ice forming cracks between crystals, is great…if you’re a physicist who already knows how ice forms cracks between crystals. If you’re not, I’m guessing reading those kinds of explanations isn’t helpful. I’m guessing you’re still wondering why there ought to be any giant strings floating in space.
The real explanation has to do with a type of mathematical gadget physicists use, called a scalar field. You can think of a scalar field as described by a number, like a temperature, that can vary in space and time. The field carries potential energy, and that energy depends on what the scalar field’s “number” is. Left alone, the field settles into a situation with as little potential energy as it can, like a ball rolling down a hill. That situation is one of the field’s default values, something we call a “vacuum” value. Changing the field away from its vacuum value can take a lot of energy. The Higgs boson is one example of a scalar field. Its vacuum value is the value it has in day to day life. In order to make a detectable Higgs boson at the Large Hadron Collider, they needed to change the field away from its vacuum value, and that took a lot of energy.
In the very early universe, almost back at the Big Bang, the world was famously in a hot dense state. That hot dense state meant that there was a lot of energy to go around, so scalar fields could vary far from their vacuum values, pretty much randomly. As the universe expanded and cooled, there was less and less energy available for these fields, and they started to settle down.
Now, the thing about these default, “vacuum” values of a scalar field is that there doesn’t have to be just one of them. Depending on what kind of mathematical function the field’s potential energy is, there could be several different possibilities each with equal energy.
Let’s imagine a simple example, of a field with two vacuum values: +1 and -1. As the universe cooled down, some parts of the universe would end up with that scalar field number equal to +1, and some to -1. But what happens in between?
The scalar field can’t just jump from -1 to +1, that’s not allowed in physics. It has to pass through 0 in between. But, unlike -1 and +1, 0 is not a vacuum value. When the scalar field number is equal to 0, the field has more energy than it does when it’s equal to -1 or +1. Usually, a lot more energy.
That means the region of scalar field number 0 can’t spread very far: the further it spreads, the more energy it takes to keep it that way. On the other hand, the region can’t vanish altogether: something needs to happen to transition between the numbers -1 and +1.
The thing that happens is called a domain wall. A domain wall is a thin sheet, as thin as it can physically be, where the scalar field doesn’t take its vacuum value. You can roughly think of it as made up of the scalar field, a churning zone of the kind of bosons the LHC was trying to detect.
This sheet still has a lot of energy, bound up in the unusual value of the scalar field, like an LHC collision in every proton-sized chunk. As such, like any object with a lot of energy, it has a gravitational field. For a domain wall, the effect of this gravity would be very very dramatic: so dramatic, that we’re pretty sure they’re incredibly rare. If they were at all common, we would have seen evidence of them long before now!
Ok, I’ve shown you a wall, that’s weird, sure. What does that have to do with cosmic strings?
The number representing a scalar field doesn’t have to be a real number: it can be imaginary instead, or even complex. Now I’d like you to imagine a field with vacuum values on the unit circle, in the complex plane. That means that +1 and -1 are still vacuum values, but so are , and , and everything else you can write as . However, 0 is still not a vacuum value. Neither is, for example, .
With vacuum values like this, you can’t form domain walls. You can make a path between -1 and +1 that only goes through the unit circle, through for example. The field will be at its vacuum value throughout, taking no extra energy.
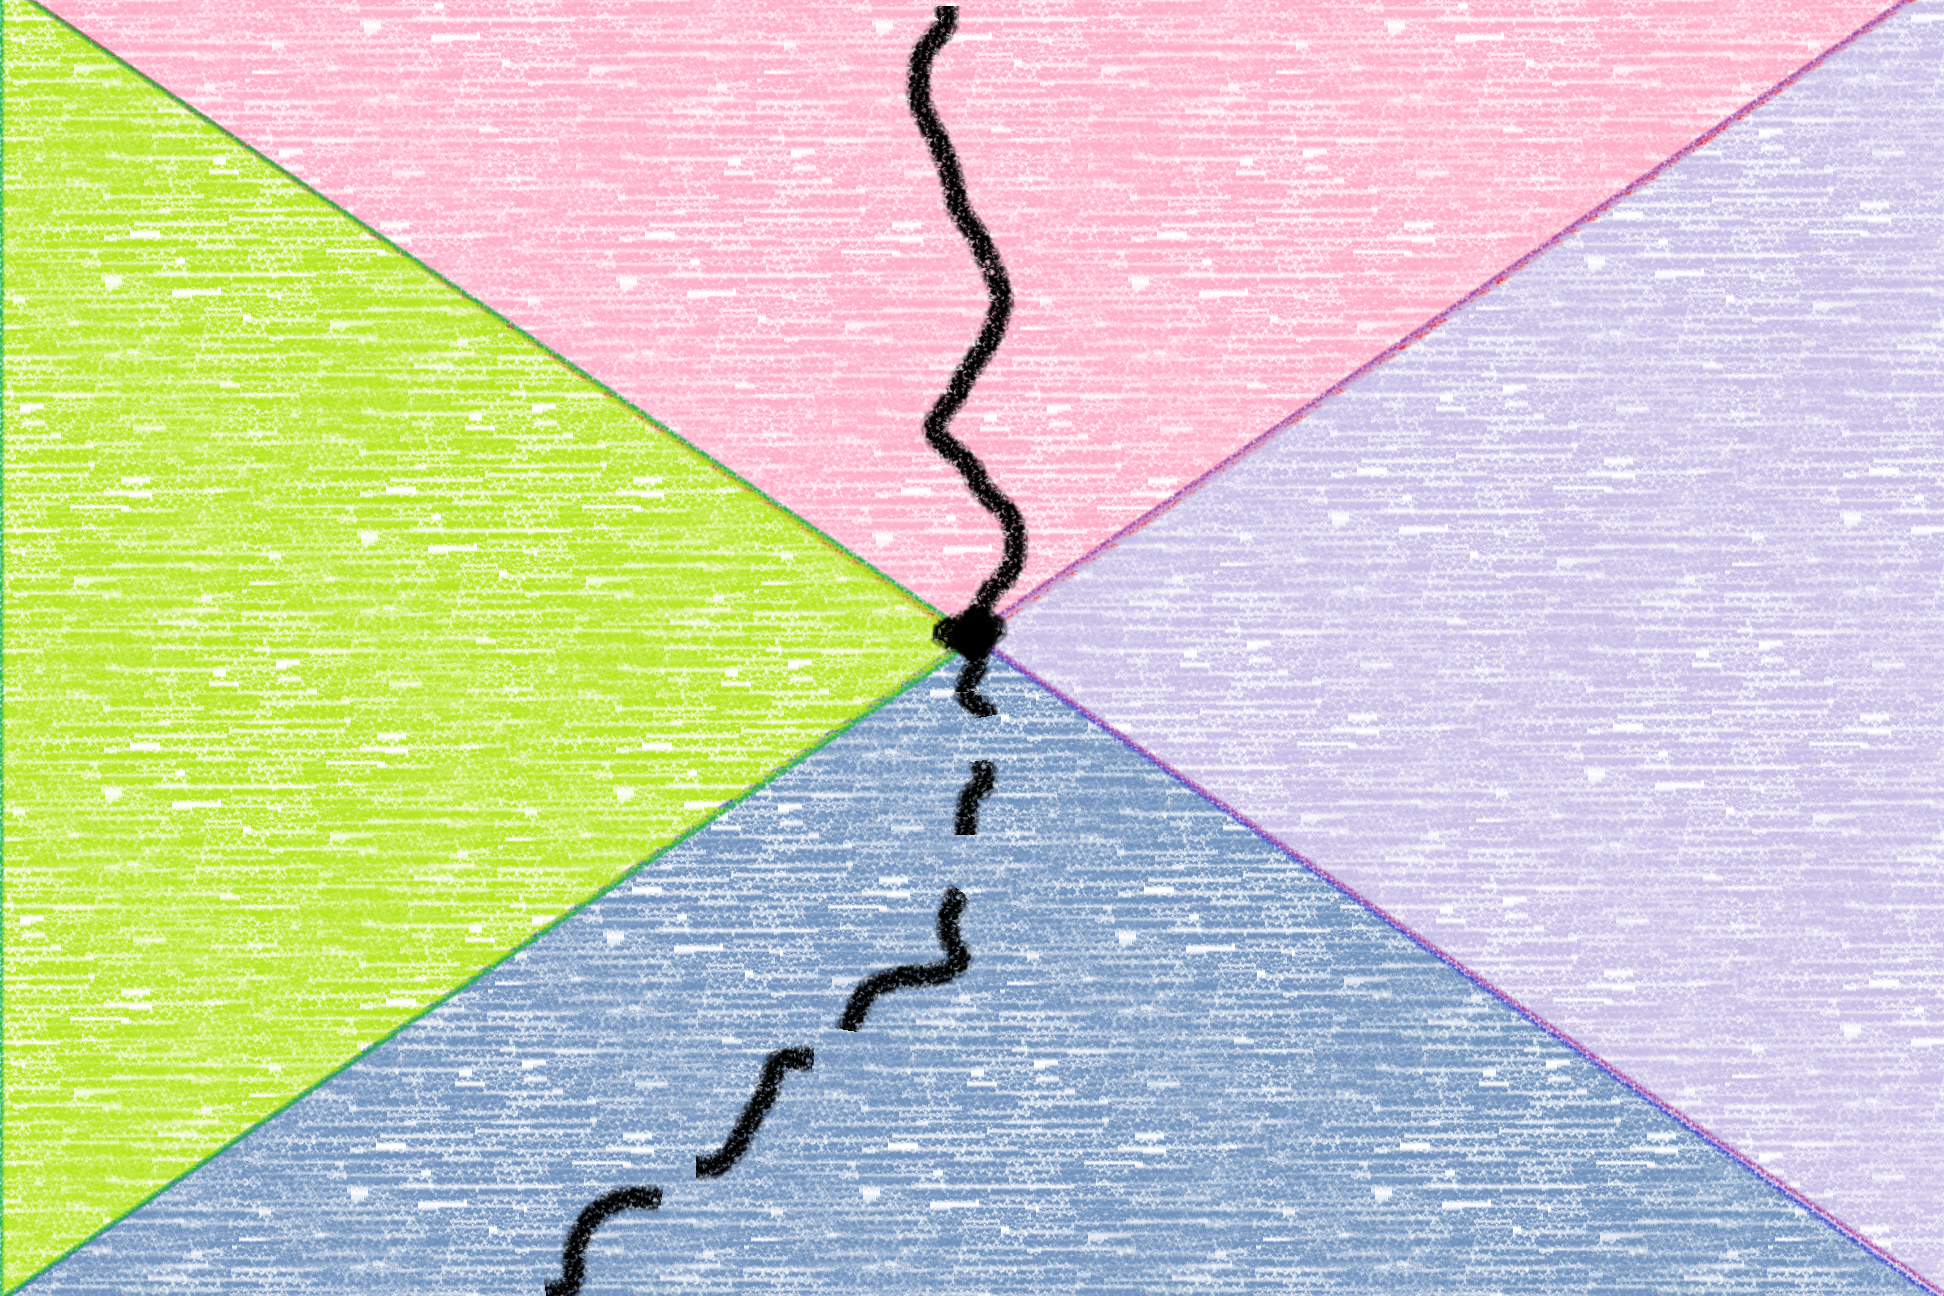
However, imagine the different regions form a circle. In the picture above, suppose that the blue area at the bottom is at vacuum value -1 and red is at +1. You might have in the green region, and in the purple region, covering the whole circle smoothly as you go around.
Now, think about what happens in the middle of the circle. On one side of the circle, you have -1. On the other, +1. (Or, on one side , on the other, ). No matter what, different sides of the circle are not allowed to be next to each other, you can’t just jump between them. So in the very middle of the circle, something else has to happen.
Once again, that something else is a field that goes away from its vacuum value, that passes through 0. Once again, that takes a lot of energy, so it occupies as little space as possible. But now, that space isn’t a giant wall. Instead, it’s a squiggly line: a cosmic string.
Cosmic strings don’t have as dramatic a gravitational effect as domain walls. That means they might not be super-rare. There might be some we haven’t seen yet. And if we do see them, it could be because they wiggle space and time, making gravitational waves.
Cosmic strings don’t require string theory, they come from a much more basic gadget, scalar fields. We know there is one quite important scalar field, the Higgs field. The Higgs vacuum values aren’t like +1 and -1, or like the unit circle, though, so the Higgs by itself won’t make domain walls or cosmic strings. But there are a lot of proposals for scalar fields, things we haven’t discovered but that physicists think might answer lingering questions in particle physics, and some of those could have the right kind of vacuum values to give us cosmic strings. Thus, if we manage to detect cosmic strings, we could learn something about one of those lingering questions.
For those who have been following these developments, things don’t feel quite so sudden. Already in 2019, AI Dungeon showed off how an early version of GPT could be used to mimic an old-school text-adventure game, and a tumblr blogger built a bot that imitates his posts as a fun side project. Still, the newer programs have shown some impressive capabilities.
Are we close to “real AI”, to artificial minds like the positronic brains in Isaac Asimov’s I, Robot? I can’t say, in part because I’m not sure what “real AI” really means. But if you want to understand where things like ChatGPT come from, how they work and why they can do what they do, then all the talk of AI won’t be helpful. Instead, you need to think of an entirely different set of Asimov novels: the Foundation series.
While Asimov’s more famous I, Robot focused on the science of artificial minds, the Foundation series is based on a different fictional science, the science of psychohistory. In the stories, psychohistory is a kind of futuristic social science. In the real world, historians and sociologists can find general principles of how people act, but don’t yet have the kind of predictive theories physicists or chemists do. Foundation imagines a future where powerful statistical methods have allowed psychohistorians to precisely predict human behavior: not yet that of individual people, but at least the average behavior of civilizations. They can not only guess when an empire is soon to fall, but calculate how long it will be before another empire rises, something few responsible social scientists would pretend to do today.
GPT and similar programs aren’t built to predict the course of history, but they do predict something: given part of a text, they try to predict the rest. They’re called Large Language Models, or LLMs for short. They’re “models” in the sense of mathematical models, formulas that let us use data to make predictions about the world, and the part of the world they model is our use of language.
Normally, a mathematical model is designed based on how we think the real world works. A mathematical model of a pandemic, for example, might use a list of people, each one labeled as infected or not. It could include an unknown number, called a parameter, for the chance that one person infects another. That parameter would then be filled in, or fixed, based on observations of the pandemic in the real world.
LLMs (as well as most of the rest of what people call “AI” these days) are a bit different. Their models aren’t based on what we expect about the real world. Instead, they’re in some sense “generic”, models that could in principle describe just about anything. In order to make this work, they have a lot more parameters, tons and tons of flexible numbers that can get fixed in different ways based on data.
The surprising thing is that this works, and works surprisingly well. Just as psychohistory from the Foundation novels can predict events with much more detail than today’s historians and sociologists, LLMs can predict what a text will look like much more precisely than today’s literature professors. That isn’t necessarily because LLMs are “intelligent”, or because they’re “copying” things people have written. It’s because they’re mathematical models, built by statistically analyzing a giant pile of texts.
Just as Asimov’s psychohistory can’t predict the behavior of individual people, LLMs can’t predict the behavior of individual texts. If you start writing something, you shouldn’t expect an LLM to predict exactly how you would finish. Instead, LLMs predict what, on average, the rest of the text would look like. They give a plausible answer, one of many, for what might come next.
They can’t do that perfectly, but doing it imperfectly is enough to do quite a lot. It’s why they can be used to make chatbots, by predicting how someone might plausibly respond in a conversation. It’s why they can write fiction, or ads, or college essays, by predicting a plausible response to a book jacket or ad copy or essay prompt.
LLMs like GPT were invented by computer scientists, not social scientists or literature professors. Because of that, they get described as part of progress towards artificial intelligence, not as progress in social science. But if you want to understand what ChatGPT is right now, and how it works, then that perspective won’t be helpful. You need to put down your copy of I, Robot and pick up Foundation. You’ll still be impressed, but you’ll have a clearer idea of what could come next.
As a kid who watched far too much educational television, I dimly remember learning about the USA’s first transcontinental railroad. Somehow, parts of the story stuck with me. Two companies built the railroad from different directions, one from California and the other from the middle of the country, aiming for a mountain in between. Despite the US Civil War happening around this time, the two companies built through, in the end racing to where the final tracks were laid with a golden spike.
I’m a theoretical physicist, so of course I don’t build railroads. Instead, I build new mathematical methods, ways to check our theories of particle physics faster and more efficiently. Still, something of that picture resonates with me.
You might think someone who develops new mathematical methods would be a mathematician, not a physicist. But while there are mathematicians who work on the problems I work on, their goals are a bit different. They care about rigor, about stating only things they can carefully prove. As such, they often need to work with simplified examples, “toy models” well-suited to the kinds of theorems they can build.
Physicists can be a bit messier. We don’t always insist on the same rigor the mathematicians do. This makes our results less reliable, but it makes our “toy models” a fair amount less “toy”. Our goal is to try to tackle questions closer to the actual real world.
What happens when physicists and mathematicians work on the same problem?
If the physicists worked alone, they might build and build, and end up with an answer that isn’t actually true. The mathematicians, keeping rigor in mind, would be safe in the truth of what they built, but might not end up anywhere near the physicists’ real-world goals.
Together, though, physicists and mathematicians can build towards each other. The physicists can keep their eyes on the mathematicians, correcting when they notice something might go wrong and building more and more rigor into their approach. The mathematicians can keep their eyes on the physicists, building more and more complex applications of their rigorous approaches to get closer and closer to the real world. Eventually, like the transcontinental railroad, the two groups meet: the mathematicians prove a rigorous version of the physicists’ approach, or the physicists adopt the mathematicians’ ideas and apply them to their own theories.
A sort of conference photo
In practice, it isn’t just two teams, physicists and mathematicians, building towards each other. Different physicists themselves work with different levels of rigor, aiming to understand different problems in different theories, and the mathematicians do the same. Each of us is building our own track, watching the other tracks build towards us on the horizon. Eventually, we’ll meet, and science will chug along over what we’ve built.
I’m at a workshop this week. It’s part of a series of “Bethe Forums”, cozy little conferences run by the Bethe Center for Theoretical Physics in Bonn.
You can tell it’s an institute for theoretical physics because they have one of these, but not a “doing room”
The workshop’s title, “Geometries and Special Functions for Physics and Mathematics”, covers a wide range of topics. There are talks on Calabi-Yau manifolds, elliptic (and hyper-elliptic) polylogarithms, and cluster algebras and cluster polylogarithms. Some of the talks are by mathematicians, others by physicists.
In addition to the talks, this conference added a fun innovative element, “my favorite problem sessions”. The idea is that a speaker spends fifteen minutes introducing their “favorite problem”, then the audience spends fifteen minutes discussing it. Some treated these sessions roughly like short talks describing their work, with the open directions at the end framed as their favorite problem. Others aimed broader, trying to describe a general problem and motivate interest in people of other sub-fields.
This was a particularly fun conference for me, because the seemingly distinct topics all connect in one way or another to my own favorite problem. In our “favorite theory” of N=4 super Yang-Mills, we can describe our calculations in terms of an “alphabet” of pieces that let us figure out predictions almost “by guesswork”. These alphabets, at least in the cases we know how to handle, turn out to correspond to mathematical structures called cluster algebras. If we look at interactions of six or seven particles, these cluster algebras are a powerful guide. For eight or nine, they still seem to matter, but are much harder to use.
We don’t know what an “alphabet” should look like for these Calabi-Yau manifolds (but I’m working on it). Because of that, we don’t know how these cluster algebras should appear.
In my view, any explanation for the role of cluster algebras in our calculations has to extend to these cases, to elliptic polylogarithms and Calabi-Yau manifolds. Without knowing how to frame an alphabet for these things, we won’t be able to solve the lingering mysteries that fill our field.
Because of that, “my favorite problem” is one of my biggest motivations, the question that drives a large chunk of what I do. It’s what’s made this conference so much fun, and so stimulating: almost every talk had something I wanted to learn.
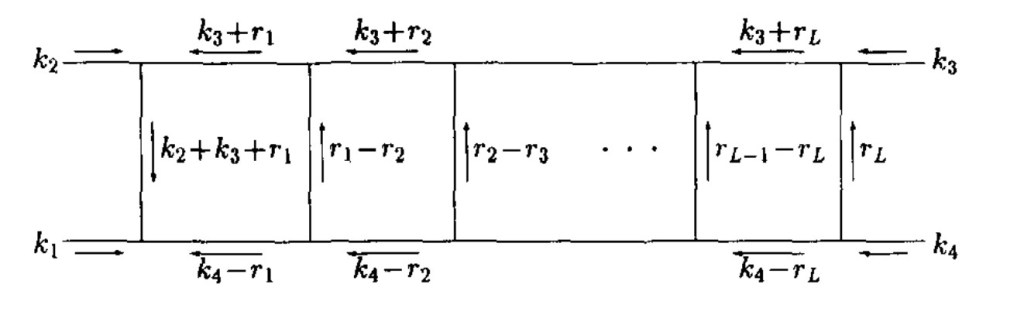
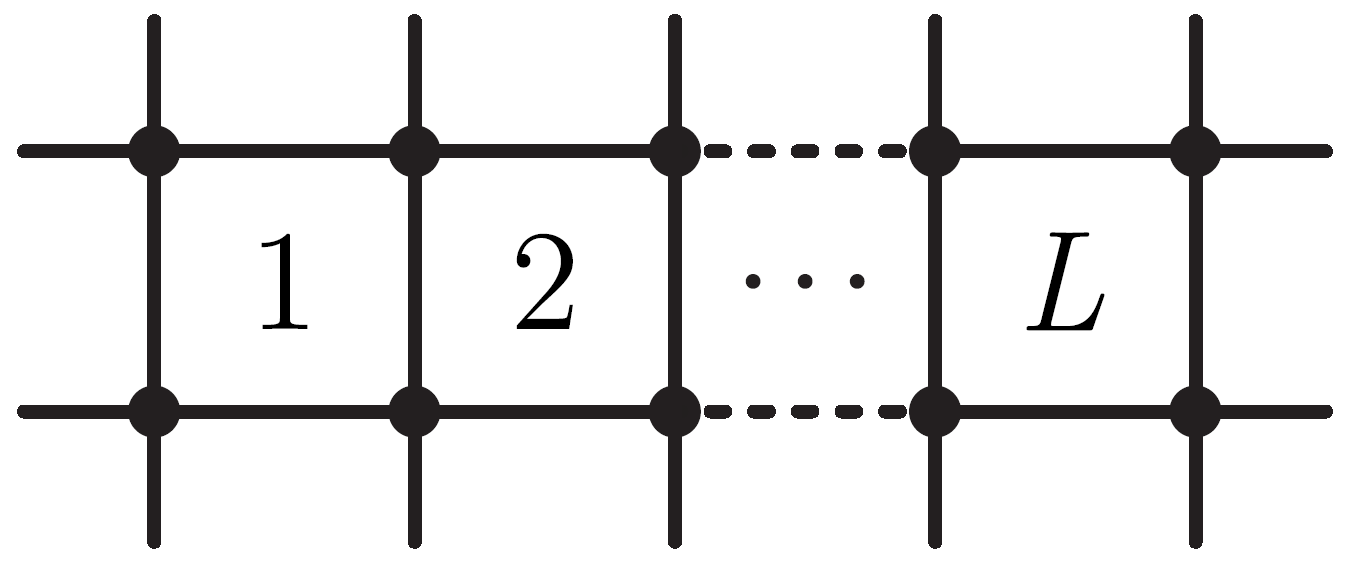
There are infinitely many of these diagrams, but they’re all beautifully simple, variations on a theme that can be written down in a precise mathematical way.
Change things a little bit, though, and the situation gets wildly more intractable. Let the rungs of the ladder peek through the sides, and you get something looking more like the tracks for a train:
These traintrack integrals are much more complicated. Describing them requires the mathematics of Calabi-Yau manifolds, involving higher and higher dimensions as the tracks get longer. I don’t think there’s any hope of understanding these things for all loops, at least not any time soon.
What if we aimed somewhere in between? A ladder that just started to turn traintrack?
Add just a single pair of rungs, and it turns out that things remain relatively simple. If we do this, it turns out we don’t need any complicated Calabi-Yau manifolds. We just need the simplest Calabi-Yau manifold, called an elliptic curve. It’s actually the same curve for every version of the diagram. And the situation is simple enough that, with some extra cleverness, it looks like we’ve found a trick to calculate these diagrams to any number of loops we’d like.
These developments are exciting, because Feynman diagrams with elliptic curves are still tough to deal with. We still have whole conferences about them. These new elliptic diagrams can be a long list of test cases, things we can experiment with with any number of loops. With time, we might truly understand them as well as the ladder diagrams!
Quanta has come up a number of times on this blog, they’re a science news outlet set up by the Simons Foundation. Their goal is to enhance the public understanding of science and mathematics. They cover topics other outlets might find too challenging, and they cover the topics others cover with more depth. Most people I know who’ve worked with them have been impressed by their thoroughness: they take fact-checking to a level I haven’t seen with other science journalists. If you’re doing a certain kind of mathematical work, then you hope that Quanta decides to cover it.
A while back, as I was chatting with one of their journalists, I had a startling realization: if I want Quanta to cover something, I can send them a tip, and if they’re interested they’ll write about it. That realization resulted in the article I talked about here. Chatting with the journalist interviewing me for that article, though, I learned something if anything even more startling: if I want Quanta to cover something, and I want to write about it, I can pitch the article to Quanta, and if they’re interested they’ll pay me to write about it.
Around the same time, I happened to talk to a few people in my field, who had a problem they thought Quanta should cover. A software, called FORM, was used in all the most serious collider physics calculations. Despite that, the software wasn’t being supported: its future was unclear. You can read the article to learn more.
One thing I didn’t mention in that article: I hadn’t used FORM before I started writing it. I don’t do those “most serious collider physics calculations”, so I’d never bothered to learn FORM. I mostly use Mathematica, a common choice among physicists who want something easy to learn, even if it’s not the strongest option for many things.
(By the way, it was surprisingly hard to find quotes about FORM that didn’t compare it specifically to Mathematica. In the end I think I included one, but believe me, there could have been a lot more.)
Now, I wonder if I should have been using FORM all along. Many times I’ve pushed to the limits of what Mathematica could comfortable handle, the limits of what my computer’s memory could hold, equations long enough that just expanding them out took complicated work-arounds. If I had learned FORM, maybe I would have breezed through those calculations, and pushed even further.
I’d love it if this article gets FORM more attention, and more support. But also, I’d love it if it gives a window on the nuts and bolts of hard-core particle physics: the things people have to do to turn those T-shirt equations into predictions for actual colliders. It’s a world in between physics and computer science and mathematics, a big part of the infrastructure of how we know what we know that, precisely because it’s infrastructure, often ends up falling through the cracks.
Edit: For researchers interested in learning more about FORM, the workshop I mentioned at the end of the article is now online, with registrations open.
There’s a saying in physics, attributed to the famous genius John von Neumann: “With four parameters I can fit an elephant, and with five I can make him wiggle his trunk.”
Say you want to model something, like some surprising data from a particle collider. You start with some free parameters: numbers in your model that aren’t decided yet. You then decide those numbers, “fixing” them based on the data you want to model. Your goal is for your model not only to match the data, but to predict something you haven’t yet measured. Then you can go out and check, and see if your model works.
The more free parameters you have in your model, the easier this can go wrong. More free parameters make it easier to fit your data, but that’s because they make it easier to fit any data. Your model ends up not just matching the physics, but matching the mistakes as well: the small errors that crop up in any experiment. A model like that may look like it’s a great fit to the data, but its predictions will almost all be wrong. It wasn’t just fit, it was overfit.
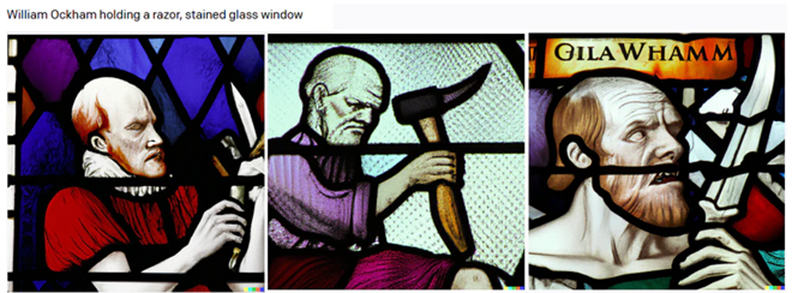
We have statistical tools that tell us when to worry about overfitting, when we should be impressed by a model and when it has too many parameters. We don’t actually use these tools correctly, but they still give us a hint of what we actually want to know, namely, whether our model will make the right predictions. In a sense, these tools form the mathematical basis for Occam’s Razor, the idea that the best explanation is often the simplest one, and Occam’s Razor is a critical part of how we do science.
So, did you know machine learning was just modeling data?
All of the much-hyped recent advances in artificial intelligence, GPT and Stable Diffusion and all those folks, at heart they’re all doing this kind of thing. They start out with a model (with a lot more than five parameters, arranged in complicated layers…), then use data to fix the free parameters. Unlike most of the models physicists use, they can’t perfectly fix these numbers: there are too many of them, so they have to approximate. They then test their model on new data, and hope it still works.
Increasingly, it does, and impressively well, so well that the average person probably doesn’t realize this is what it’s doing. When you ask one of these AIs to make an image for you, what you’re doing is asking what image the model predicts would show up captioned with your text. It’s the same sort of thing as asking an economist what their model predicts the unemployment rate will be when inflation goes up. The machine learning model is just way, way more complicated.
As a physicist, the first time I heard about this, I had von Neumann’s quote in the back of my head. Yes, these machines are dealing with a lot more data, from a much more complicated reality. They literally are trying to fit elephants, even elephants wiggling their trunks. Still, the sheer number of parameters seemed fishy here. And for a little bit things seemed even more fishy, when I learned about double descent.
Suppose you start increasing the number of parameters in your model. Initially, your model gets better and better. Your predictions have less and less error, your error descends. Eventually, though, the error increases again: you have too many parameters so you’re over-fitting, and your model is capturing accidents in your data, not reality.
In machine learning, weirdly, this is often not the end of the story. Sometimes, your prediction error rises, only to fall once more, in a double descent.
For a while, I found this deeply disturbing. The idea that you can fit your data, start overfitting, and then keep overfitting, and somehow end up safe in the end, was terrifying. The way some of the popular accounts described it, like you were just overfitting more and more and that was fine, was baffling, especially when they seemed to predict that you could keep adding parameters, keep fitting tinier and tinier fleas on the elephant’s trunk, and your predictions would never start going wrong. It would be the death of Occam’s Razor as we know it, more complicated explanations beating simpler ones off to infinity.
Luckily, that’s not what happens. And after talking to a bunch of people, I think I finally understand this enough to say something about it here.
The right way to think about double descent is as overfitting prematurely. You do still expect your error to eventually go up: your model won’t be perfect forever, at some point you will really overfit. It might take a long time, though: machine learning people are trying to model very complicated things, like human behavior, with giant piles of data, so very complicated models may often be entirely appropriate. In the meantime, due to a bad choice of model, you can accidentally overfit early. You will eventually overcome this, pushing past with more parameters into a model that works again, but for a little while you might convince yourself, wrongly, that you have nothing more to learn.
So Occam’s Razor still holds, but with a twist. The best model is simple enough, but no simpler. And if you’re not careful enough, you can convince yourself that a too-simple model is as complicated as you can get.
Image from Astral Codex Ten
I was reminded of all this recently by somearticles by Sabine Hossenfelder.
Hossenfelder is a critic of mainstream fundamental physics. The articles were her restating a point she’s made many times before, including in (at least) one of her books. She thinks the people who propose new particles and try to search for them are wasting time, and the experiments motivated by those particles are wasting money. She’s motivated by something like Occam’s Razor, the need to stick to the simplest possible model that fits the evidence. In her view, the simplest models are those in which we don’t detect any more new particles any time soon, so those are the models she thinks we should stick with.
I tend to disagree with Hossenfelder. Here, I was oddly conflicted. In some of her examples, it seemed like she had a legitimate point. Others seemed like she missed the mark entirely.
Talk to most astrophysicists, and they’ll tell you dark matter is settled science. Indeed, there is a huge amount of evidence that something exists out there in the universe that we can’t see. It distorts the way galaxies rotate, lenses light with its gravity, and wiggled the early universe in pretty much the way you’d expect matter to.
What isn’t settled is whether that “something” interacts with anything else. It has to interact with gravity, of course, but everything else is in some sense “optional”. Astroparticle physicists use satellites to search for clues that dark matter has some other interactions: perhaps it is unstable, sometimes releasing tiny signals of light. If it did, it might solve other problems as well.
Hossenfelder thinks this is bunk (in part because she thinks those other problems are bunk). I kind of do too, though perhaps for a more general reason: I don’t think nature owes us an easy explanation. Dark matter isn’t obligated to solve any of our other problems, it just has to be dark matter. That seems in some sense like the simplest explanation, the one demanded by Occam’s Razor.
At the same time, I disagree with her substantially more on collider physics. At the Large Hadron Collider so far, all of the data is reasonably compatible with the Standard Model, our roughly half-century old theory of particle physics. Collider physicists search that data for subtle deviations, one of which might point to a general discrepancy, a hint of something beyond the Standard Model.
While my intuitions say that the simplest dark matter is completely dark, they don’t say that the simplest particle physics is the Standard Model. Back when the Standard Model was proposed, people might have said it was exceptionally simple because it had a property called “renormalizability”, but these days we view that as less important. Physicists like Ken Wilson and Steven Weinberg taught us to view theories as a kind of series of corrections, like a Taylor series in calculus. Each correction encodes new, rarer ways that particles can interact. A renormalizable theory is just the first term in this series. The higher terms might be zero, but they might not. We even know that some terms cannot be zero, because gravity is not renormalizable.
The two cases on the surface don’t seem that different. Dark matter might have zero interactions besides gravity, but it might have other interactions. The Standard Model might have zero corrections, but it might have nonzero corrections. But for some reason, my intuition treats the two differently: I would find it completely reasonable for dark matter to have no extra interactions, but very strange for the Standard Model to have no corrections.
I think part of where my intuition comes from here is my experience with other theories.
One example is a toy model called sine-Gordon theory. In sine-Gordon theory, this Taylor series of corrections is a very familiar Taylor series: the sine function! If you go correction by correction, you’ll see new interactions and more new interactions. But if you actually add them all up, something surprising happens. Sine-Gordon turns out to be a special theory, one with “no particle production”: unlike in normal particle physics, in sine-Gordon particles can neither be created nor destroyed. You would never know this if you did not add up all of the corrections.
String theory itself is another example. In string theory, elementary particles are replaced by strings, but you can think of that stringy behavior as a series of corrections on top of ordinary particles. Once again, you can try adding these things up correction by correction, but once again the “magic” doesn’t happen until the end. Only in the full series does string theory “do its thing”, and fix some of the big problems of quantum gravity.
If the real world really is a theory like this, then I think we have to worry about something like double descent.
Remember, double descent happens when our models can prematurely get worse before getting better. This can happen if the real thing we’re trying to model is very different from the model we’re using, like the example in this explainer that tries to use straight lines to match a curve. If we think a model is simpler because it puts fewer corrections on top of the Standard Model, then we may end up rejecting a reality with infinite corrections, a Taylor series that happens to add up to something quite nice. Occam’s Razor stops helping us if we can’t tell which models are really the simple ones.
The problem here is that every notion of “simple” we can appeal to here is aesthetic, a choice based on what makes the math look nicer. Other sciences don’t have this problem. When a biologist or a chemist wants to look for the simplest model, they look for a model with fewer organisms, fewer reactions…in the end, fewer atoms and molecules, fewer of the building-blocks given to those fields by physics. Fundamental physics can’t do this: we build our theories up from mathematics, and mathematics only demands that we be consistent. We can call theories simpler because we can write them in a simple way (but we could write them in a different way too). Or we can call them simpler because they look more like toy models we’ve worked with before (but those toy models are just a tiny sample of all the theories that are possible). We don’t have a standard of simplicity that is actually reliable.
From the Wikipedia page for dark matter halos
There is one other way out of this pickle. A theory that is easier to write down is under no obligation to be true. But it is more likely to be useful. Even if the real world is ultimately described by some giant pile of mathematical parameters, if a simple theory is good enough for the engineers then it’s a better theory to aim for: a useful theory that makes peoples’ lives better.
I kind of get the feeling Hossenfelder would make this objection. I’ve seen her argue on twitter that scientists should always be able to say what their research is good for, and her Guardian article has this suggestive sentence: “However, we do not know that dark matter is indeed made of particles; and even if it is, to explain astrophysical observations one does not need to know details of the particles’ behaviour.”
Ok yes, to explain astrophysical observations one doesn’t need to know the details of dark matter particles’ behavior. But taking a step back, one doesn’t actually need to explain astrophysical observations at all.
Astrophysics and particle physics are not engineering problems. Nobody out there is trying to steer a spacecraft all the way across a galaxy, navigating the distribution of dark matter, or creating new universes and trying to make sure they go just right. Even if we might do these things some day, it will be so far in the future that our attempts to understand them won’t just be quaint: they will likely be actively damaging, confusing old research in dead languages that the field will be better off ignoring to start from scratch.
Because of that, usefulness is also not a meaningful guide. It cannot tell you which theories are more simple, which to favor with Occam’s Razor.
Hossenfelder’s highest-profile recent work falls afoul of one or the other of her principles. Her work on the foundations of quantum mechanics could genuinely be useful, but there’s no reason aside from claims of philosophical beauty to expect it to be true. Her work on modeling dark matter is at least directly motivated by data, but is guaranteed to not be useful.
I’m not pointing this out to call Hossenfelder a hypocrite, as some sort of ad hominem or tu quoque. I’m pointing this out because I don’t think it’s possible to do fundamental physics today without falling afoul of these principles. If you want to hold out hope that your work is useful, you don’t have a great reason besides a love of pretty math: otherwise, anything useful would have been discovered long ago. If you just try to model existing data as best you can, then you’re making a model for events far away or locked in high-energy particle colliders, a model no-one else besides other physicists will ever use.
I don’t know the way through this. I think if you need to take Occam’s Razor seriously, to build on the same foundations that work in every other scientific field…then you should stop doing fundamental physics. You won’t be able to make it work. If you still need to do it, if you can’t give up the sub-field, then you should justify it on building capabilities, on the kind of “practice” Hossenfelder also dismisses in her Guardian piece.
We don’t have a solid foundation, a reliable notion of what is simple and what isn’t. We have guesses and personal opinions. And until some experiment uncovers some blinding flash of new useful meaningful magic…I don’t think we can do any better than that.
I’ve done a lot of work with what we like to call “bootstrap” methods. Instead of doing a particle physics calculation in all its gory detail, we start with a plausible guess and impose requirements based on what we know. Eventually, we have the right answer pulled up “by its own bootstraps”: the only answer the calculation could have, without actually doing the calculation.
This method works very well, but so far it’s only been applied to certain kinds of calculations, involving mathematical functions called polylogarithms. More complicated calculations involve a mathematical object called an elliptic curve, and until very recently it wasn’t clear how to bootstrap them. To get people thinking about it, my colleagues Hjalte Frellesvig and Andrew McLeod asked the Carlsberg Foundation (yes, that Carlsberg) to fund a mini-conference. The idea was to get elliptic people and bootstrap people together (along with Hjalte’s tribe, intersection theory people) to hash things out. “Jumpstart people” are not a thing in physics, so despite the title they were not invited.
Anyone remember these games? Did you know that they still exist, have an educational MMO, and bought neopets?
Having the conference so soon after the yearly Elliptics meeting had some strange consequences. There was only one actual duplicate talk, but the first day of talks all felt like they would have been welcome additions to the earlier conference. Some might be functioning as “overflow”: Elliptics this year focused on discussion and so didn’t have many slots for talks, while this conference despite its discussion-focused goal had a more packed schedule. In other cases, people might have been persuaded by the more relaxed atmosphere and lack of recording or posted slides to give more speculative talks. Oliver Schlotterer’s talk was likely in this category, a discussion of the genus-two functions one step beyond elliptics that I think people at the previous conference would have found very exciting, but which involved work in progress that I could understand him being cautious about presenting.
The other days focused more on the bootstrap side, with progress on some surprising but not-quite-yet elliptic avenues. It was great to hear that Mark Spradlin is making new progress on his Ziggurat story, to hear James Drummond suggest a picture for cluster algebras that could generalize to other theories, and to get some idea of the mysterious ongoing story that animates my colleague Cristian Vergu.
There was one thing the organizers couldn’t have anticipated that ended up throwing the conference into a new light. The goal of the conference was to get people started bootstrapping elliptic functions, but in the meantime people have gotten started on their own. Roger Morales Espasa presented his work on this with several of my other colleagues. They can already reproduce a known result, the ten-particle elliptic double-box, and are well on-track to deriving something genuinely new, the twelve-particle version. It’s exciting, but it definitely makes the rest of us look around and take stock. Hopefully for the better!

 , and
 , and everything else you can write as
 . However, 0 is still not a vacuum value. Neither is, for example,
 .