Tag Archives: press

Everybody Who Isn’t ”Viewers Like You”

Last week, I talked about how truthseekers get paid. But truth-tellers and truth-seekers are different things.

Consider educational kids’ shows on public television.

Nobody who works on Sesame Street is out there uncovering new letters and numbers. Bill Nye’s show wasn’t bringing analysis fresh from the lab.

The purpose of these shows is to educate. The purpose of education is to change minds.

So who pays for educational kids’ shows on public television?

If you’re from the US and watched PBS growing up, you remember one answer: “viewers like you!” US public television is supported by donations, ordinary people across the country who want it to keep on educating kids.

But you also might remember the lists of names that came before “viewers like you”. Some of those were things like “the Department of Education” or “a grant from the National Science Foundation”: government programs, in other words. Others were philanthropists and private foundations. Some were tied to companies, like the Intel Foundation, or Juicy Juice.

All of these groups, from government departments to donors, are trying to change kids’ minds. They support specific shows on specific topics, where they want kids to be better-informed. The same groups have the same kind of impact on schools. For example, I remember in elementary school we all learned to play a recorder, because a wealthy donor had given the school recorders out of the idea that music education was especially important.

For a truth-seeker like a journalist, accepting that kind of funding would be a problem. Grants for journalists tend to support things like travel, letting journalists learn more about specific topics, not pre-judging the conclusion. But children’s television is about truth-telling, not truth-seeking, so our standards are different. We trust the people making children’s television to care about whether they’re telling the truth. And because the topics aren’t new, we don’t usually worry about their judgement being biased.

All this is rather obvious. But now, consider science YouTube.

Some science YouTubers seem to have a mission much like children’s television. They’re there to teach, not to make independent judgements. They don’t search for truth on their own. And some of them are funded by educational grants, much like children’s television.

Others are a bit more like journalists, or even activists. People follow them for their opinions, to hear their assessment. They’re trying to be truth-seekers.

On YouTube, it’s not always obvious which is which.

There’s a particular group of philanthropists called Effective Altruists, and many of them are concerned about AI. So in between funding things like anti-malaria bed nets, some of them are giving grants to YouTubers to make educational content about AI-related risks.

Apparently, they reached out to Sabine Hossenfelder, which was a bad idea. Sabine Hossenfelder’s followers aren’t just looking for education on known facts. They’re looking for her judgements, her literal bullshit-rating on ideas. And so while she’s paid by “viewers like you”, she’s not really the type to get paid by that type of grant.

What I want to emphasize, and what looked like it was getting lost in the discussion, was that their pitch would have been totally reasonable for other YouTubers. Educators do occasionally get grants to educate on specific topics. This is in fact a totally normal thing. Some YouTubers are educators first and foremost, they aren’t there as truth-seekers, but truth-tellers, with a real difference in how careful they need to be about bias.

Some YouTubers are different from other YouTubers. News at 11.

Paying the Truthseekers

Academics and journalists have a lot in common, at least in principle.

Whether you’re a reporter or a professor, your job is to go out into the world and figure out the truth. You’re supposed to be careful, to check and correct for how you might be wrong. And at the end of the day you’re supposed to communicate what you found.

The differences mostly come in how you’re paid.

You could imagine some sort of pure truthseeker, paid purely by how well they tell the truth. People would ask them to find out the truth about something, and pay them for the service. And the truthseekers with the best track record would get the most clients. But neither profession really works like this.

Journalism comes closest. Once upon a time, people bought newspapers in order to be the first to know when something important happened. While there’s still a little bit of that going on (I guess this is what Bloomberg Terminals are for?), it’s a lot less central because of the internet. Now, there are hundreds of ways to find out about things, from a multitude of news sites to social media. More and more, people expect to be able to get information for free.

In that environment, the news has to compete not on the facts themselves, but on how it presents them. People pay for news that’s curated well to match their interests, or news that feels more respectable. And more than either of those, they pay for news that’s entertaining. So while truthseeking skills pay, writing skills often end up mattering more. In a sense, it’s why it’s possible for me to do journalism at all. I was trained in the academic truthseeking tradition, not the journalistic one. I got into journalism by impressing editors with my writing, not my ability to suss out the truth.

That academic truthseeking tradition is quite different, in part because the rewards for it are much more indirect. Academics pay comes from two main sources: research grants, and student tuition. Students are mostly there to learn old facts, not new ones, so that source of money supports research only in so far that students believe that a successful researcher with time for research will also be a better teacher.

Research grants, in principle, pay for truthseeking. But they’re typically paid by governments, which often don’t have a clear idea of what they’d like to learn, since the more practical questions are already being researched by private companies. So the decision gets delegated out to other academics, who have a vague shared sense of what’s worth knowing and what’s not. Accuracy should have an impact: that is, it should be easier to get grants if you’re better at finding the truth. But in practice, unless someone does so badly they trigger a scandal, academics don’t usually get things all that wrong. So grants are mostly based on other factors.

Paying someone purely to deliver the truth, not to entertain or match a culture, seems tricky. You could imagine sci-fi scenarios. What if we could track the logic people used to make decisions, and demand payment if those decisions were based on facts we uncovered, like a journalist getting a percentage of every short made in response to bad news they dug up about a company? What if governments paid in proportion to how valuable academic ideas turned out to be, centuries after they were discovered, and modern-day academics sold shares in that future payout to fund themselves? What if prediction markets something something?

For the moment, academics and journalists are both in a weird middle space. They’re truthseekers, still, by culture and inclination and desire. But they’re paid for something else.

Newsworthiness Guide for Scientists

I had a recurring “elevator pitch” at Lancefest earlier this summer. After explaining that I’m a science journalist now, I’d end with “so if you run into a story, let me know!”

One person had a question that left me stumped: “What counts as a story?”

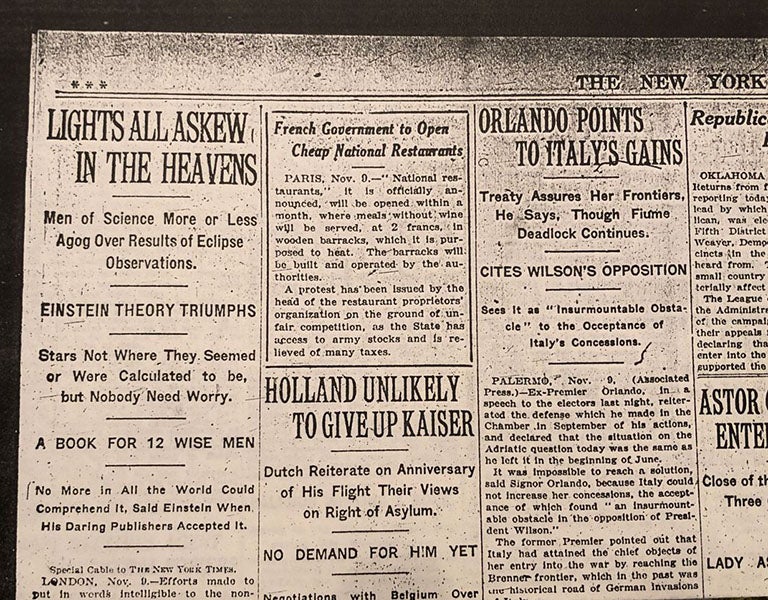
For those of us who don’t happen to be Einstein

I didn’t have a good response then. I’ve got a better one now, though I’m afraid it doesn’t fit in an elevator pitch. This is all based on my experience, so take it with a grain of salt. But here are the criteria that seem to matter:

First, a story usually needs a news hook. News is, in particular, supposed to be “new”. That doesn’t mean I can’t write about history, or established science. But editors like those stories a lot better if there is some recent development, within the past year or so, to tie it to. The new development doesn’t have to be all that important, the story can mostly focus on something else. But it needs to be somewhere in there.

Second, news stories are usually qualitative, not quantitative. I need to be able to tell a story about what happened, what actions people took and why they mattered. Quantitative developments usually only make the news if they’re so big that they shade into the qualitative: something doubling unexpectedly, for example.

Third, ideally a science news story is something that is getting the experts excited. Journalists aren’t supposed to judge the scientific merit of ideas on their own, they’re supposed to rely on experts. The most solid stories, the ones that are easiest to pitch, are ones where there’s a community of experts that largely think something is cool. That makes it easier to get good quotes, and easier to justify its relevance. If you accomplished something and you’re having trouble convincing anyone it matters, don’t start with me, start with your colleagues!

Fourth: less importantly, it helps when stories have a human angle. If you can tell a tale about how you came up with an idea, if you came from an unusual background, if something was hotly debated but now is deemed essential: these things sweeten a story, they capture readers’ interest, and editors see their value.

Finally, stories involve something changing. It can be something that just changed now, for a news piece, but it can also be something that changed over time, for a feature in a magazine. The key is change. “Old method still works” is not going to excite people, and it won’t count as news.

After writing all that out, I’m still not sure I answered the original question. But hopefully I’ve at least given some tips that can get you started. If you’re a scientist, and you see something that hits most of the boxes on this list but hasn’t been covered in the news yet, consider reaching out to me. You may have run into a story!

Bonus Info on Dark Energy and Muons

I had two pieces up this month, one in New Scientist and one in Quanta. I figured I’d give a bit of “bonus info” for both here.

The New Scientist piece covered a paper arguing that, according to the supernova evidence, there is no need for dark energy, because the universe isn’t speeding up after all. That’s a pretty dramatic claim, and it’s one the majority of cosmologists don’t agree with. But a small group has been hammering at the consensus.

Long-time followers of this blog have already heard of these folks. I criticized news coverage around a paper with one of the authors, Subir Sarkar, back in 2016, when he was only arguing that the supernova evidence was insufficient to establish dark energy, not that it was literally the wrong way around. He and his co-authors wanted an opportunity to state their case, so I posted their response a few weeks later. Later, I got to know Rameez, another author on the new paper. He ended up doing a guest post in 2019, on the next step in the story.

That story went from a statistical critique to an active proposal for something outside the consensus, in the form of inhomogeneous cosmology, the idea that the universe may be lumpier than typically assumed, with flowing currents that explain things otherwise attributed to exotic physics. That’s another topic I’ve covered before, but in this article I didn’t have the space to go into it.

Sarkar and Rameez are claiming something much more radical than most proponents of inhomogeneous cosmology, arguing against dark energy as a whole, not just more subtle effects. They told me a lot about their reasoning, most of which also didn’t make it into the piece.

It’s largely not going to make it here, either. Not due to space limitations: I’ve been pushing the blog post lengths you folks tolerate for a long time, no reason to stop now. Rather, it’s because I genuinely don’t feel qualified to judge this.

The issue is, cosmology is messy.

How do you figure out how the universe is expanding? You can look at supernovae, and use how dim they are to estimate how far away they are. The issue is, supernovae vary, even famous “standard candles”: they move in different ways, they shine differently depending on different things. Simulations aren’t nearly advanced enough to tell you all this from first principles, and so there are a wash of different corrections based largely on empirical observations, taking this or that correlation seriously and factoring them out of the measurement, while disregarding other correlations as spurious. Which of these combinations of corrections you trust determines whether the universe seems to be accelerating or decelerating.

It makes me glad I went into particle physics instead of cosmology, where you can mostly model everything from first-principles, and compare to your models.

Of course, even that can get you into trouble.

Take that Quanta piece. I wrote an update of the muon g-2 measurement. In some ways, this is an issue that many think of as already solved, by precisely that kind of first-principles modeling. Muons seemed to be violating the Standard Model, according to a calculation based in part on empirical formulas. Lattice QCD researchers figured out how to do that part of the prediction via a first-principles simulation instead, with enough accuracy that it could substitute for the empirical formulas. And lo and behold, the new prediction agreed with the experiment. Eventually, the experts accepted it, and all was well.

Except, as I commented at the time, not really. Because the empirical formulas were based on other experiments, colliding electrons and positrons. And as I now understand in much more detail, the disagreement between those electron-positron experiments is worryingly large.

So nobody is resting on their laurels. The lattice folks improved their calculation, with a result published in Nature this year that prompted Quanta to ask me to report on it. The people using the empirical method are still trying to sort out what happened. And the experimentalists are busy scrutinizing how they analyze their data, and collecting and analyzing more.

A few details that didn’t make it into the piece:

First: it goes beyond the level I was aiming for in the piece, but I really do want to emphasize the role of error estimates. Ultimately, every step in the story was not just one where experiments and predictions disagree, but one where they disagree past their reported error. The problem with disagreement between the new experiments isn’t that they disagree, it’s that they disagree so badly that they’re straining the statistical methods the people using the empirical method use to combine results together, so badly that if taken seriously, those methods would have to throw away ten years of progress of increasing precision. I don’t expect it, but I really hope for a postmortem in which we learn how to better estimate the kinds of experimental errors that can cause this. I haven’t seen that kind of postmortem for other results, so I don’t expect one here. But I have to believe that in the background someone is learning something, and getting better at this.

Second: one interesting question my editors raised was whether it was possible to do a first-principles calculation to compare with the electron-positron experiments. The answer is yes, but with some caveats. One will be recognizable to physicists: lattice QCD can only compute energy-integrated cross-sections, not measurements at particular energies like experiments find. But they can compute integrals with a modulating function…such as one strongly peaked at a particular energy. It’s a familiar type of trick for a quantum field theorist, though in this case it’s trickier than it sounds. I actually misunderstood, and thought that the same people I was talking to about the muon g-2 calculation had done that, and found it agreed with one of the electron-positron experiments over another. That’s not true: their comparisons were more indirect, while other groups attempting more direct comparisons haven’t quite gotten something good enough to do more than gesture at an agreement. So while the direction was correct, there are indeed lattice-based suggestions that favor one experiment over the others, the piece phrased things much too definitely. There’ll be a correction fixing this.

Bonus Info for “100-year-old assumption about the universe may soon be overturned”

I had a piece up in New Scientist last week (paywalled, sorry!), about a new analysis that suggests the universe is less homogeneous (more “lumpy”) that most cosmologists believe.

The piece was a bit different than my usual. Normally I do what people in the biz call “features”: longer articles about general trends. This was a much more classic “news piece”. The people I interviewed had several papers up in early April, the editors at New Scientist thought they were interesting enough to write about, so I was asked for a short, timely piece with the key takeaways.

That means I didn’t have a ton of space for background info. So if you’d like to know more, this post is for you!

The 100-year old assumption in the title refers to the Friedmann–Lemaître–Robertson–Walker (or FLRW) universe, an idea that first came together in the 1920’s, where cosmologists model the universe as homogeneous and isotropic: the same no matter where, or in which direction, you look. That sounds like a crazy assumption, but on the largest scales we can measure it’s actually mostly fine. Once you’re trying to calculate ripples in the cosmic microwave background or find out how fast distant galaxies are accelerating away, it works surprisingly well to act like the universe is an evenly-mixed soup of matter, radiation, dark matter, and dark energy.

But every assumption in physics has its doubters. The doubters of homogeneity are known as inhomogeneous cosmologists, and I’ve been sympathetic to their complaints for a while now.

I even let an inhomogeneous cosmologist do a guest post on my blog, back in 2019. That post argued something dramatic: that dark energy may not even exist, but that measurements of accelerating expansion may be a consequence of a dramatic lopsidedness in the universe around us.

The people I covered in New Scientist, Asta Heinesen, Tim Clifton, and Sofie Marie Koksbang, are arguing something much less dramatic…but that’s part of what makes it more compelling. Instead of arguing that the universe is dramatically uneven or lopsided, they’re arguing that the universe can still be on average smooth and homogeneous, the soup of galaxies people seem to expect…but still, can’t be fully modeled that way.

This is a tricky distinction to explain, and certainly something I didn’t have space to cover well enough in New Scientist. But let me take a stab at it here:

Any cosmologist will agree that FLRW can’t be the whole story. We know the universe isn’t a perfectly mixed soup: there are galaxies, and stars, and black holes, and they all wiggle the fabric of the universe in different places. When they study the universe as a whole, they’re averaging out all of that, to get the overall behavior, a bit like you could average the number of children in each family to get the average children per family in a country.

But FLRW isn’t just an average, it’s a model of spacetime. Because of that, it has to obey certain equations, called Einstein’s equations. It has to make sense by itself, as the correct answer for how spacetime would behave if it were filled with a uniform soup.

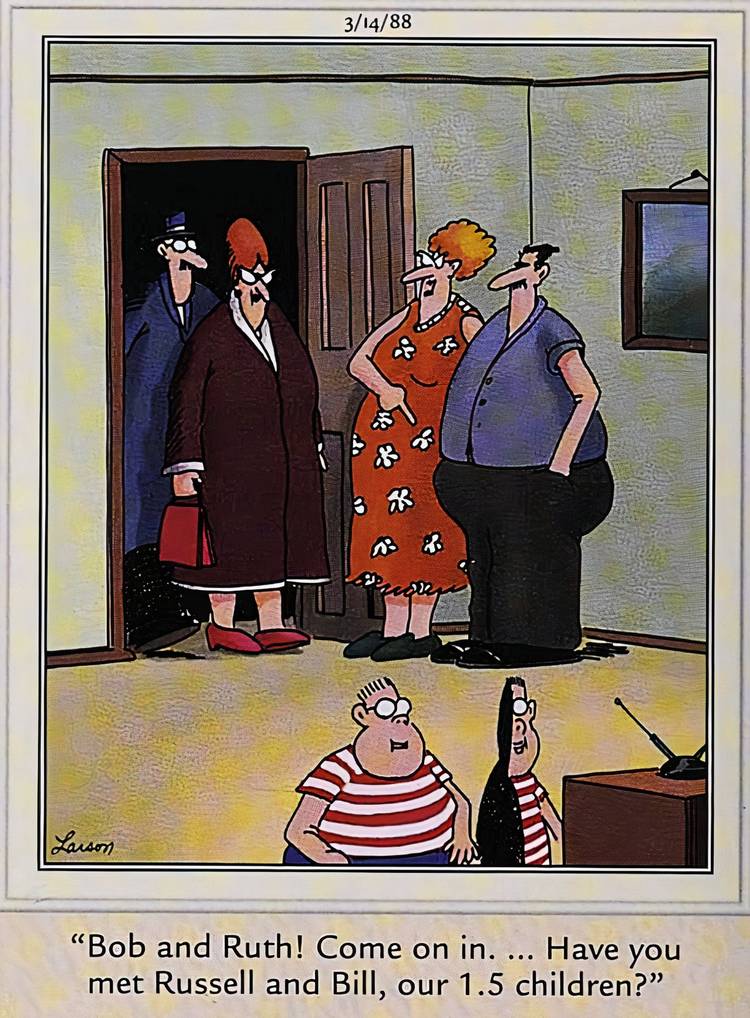
That’s an extra restriction, and that extra restriction can get you in trouble. To continue with the analogy, any real family has a whole number of children. But the average family doesn’t have a whole number of children. When I was born, the average family in the US had around 2.5 children. A lot of cartoons imagined what the half-child looked like.

From the perspective of Heinesen, Clifton, and Koksbang, assuming FLRW is a bit like assuming that the average family must have two children, or three, and can’t possibly have 2.5. Averages don’t have to look like sensible spacetimes, they don’t have to obey the Einstein equations.

In practice, the assumption of FLRW has worked a lot better than assuming that the average family can’t have 2.5 children, and that’s why Heinesen, Clifton, and Koksbang are cautious. They’re not claiming that inhomogeneity can explain everything, all the way to major components of the universe like dark energy. But they do think it can be a good explanation for smaller effects. And as cosmologists worry about smaller and smaller effects, wondering if dark energy changes over time and why the expansion rate of the universe doesn’t match up between different measurements, it can be important to remember that averages aren’t all-powerful. Eventually, they can break down. It’s a more subtle issue than a fractional child. But, as I covered in New Scientist, it may already be happening.

Breakthrough Prize 2026

Because of last week’s “bonus info” post, I’m only now getting around to commenting on this year’s Breakthrough Prizes in Fundamental Physics. While I don’t comment on them every year, I know enough about several of this year’s winners that I figured a post would be helpful.

For those who haven’t heard of it, the Breakthrough Prizes are a bit like the Nobel, if it was created by a 21st century rich person instead of a 19th century one. They give out more money, and instead of an organization like the Swedish Academy of Sciences they pick winners via a committee of past winners. They’re more flexible in structure than the Nobel, with extra prizes for early-career researchers and a tendency to reward accomplishments that are either entirely theoretical or solid experimental work that doesn’t show a new discovery, both of which are things the Nobel Prize is structured to avoid. They’ve also shown willingness to reward large collaborations, rather than following the Nobel’s informal rule to only give the award to three people at a time.

This last was on display this year in their main award in physics this year, for the muon g-2 collaborations. The award is going to collaborations of scientists and engineers at three different particle colliders, for work done over a span of over fifty years to measure the magnetic properties of the muon. These measurements have shown a tantalizing discrepancy with predictions that inspired many to conjecture new physics. However, in the last few years it’s looked more and more like the discrepancy was due to an imprecise prediction, and better methods seem to be converging to the experimental value. At this point, smart money is that there is no disagreement with the Standard Model here, but as always in science there’s a chance some mystery remains.

The Breakthrough Prize also offered a special, out-of-schedule prize to David Gross. Already a Nobel laureate, Gross had a crucial role in our understanding of the force of quantum chromodynamics that binds protons and neutrons together. He was also a major founding figure in string theory, and since the Breakthrough Prize is more comfortable recognizing theoretical contributions they get to mention this as well. Gross is also known in the community for his personality, which tends to fill up any room he’s in. I can only imagine the conversations that led to Breakthrough’s decision to add a special prize for him this year.

Breakthrough is also adding a new recurring prize, the Vera Rubin New Frontiers Prize, honoring women who make important contributions to physics within two years of their PhD. The prize is a bit smaller than the exiting early-career New Horizons in Physics Prizes, presumably because it goes to even younger researchers. This year’s winner is from my old field, scattering amplitudes. Carolina Figueiredo is part of the latest evolution of the research program behind the amplituhedron. The new framework of “surfaceology” seems like a promising geometry-flavored way to understand particle physics calculations in more realistic theories, and unlike its predecessors may have some practical value eventually as well. Congrats Carolina!

Finally, the New Horizons in Physics Prizes are for impressive early-career researchers. I don’t know much about the first recipient, Benjamin Safdi, who works on searches for axions and axion-like particles, today’s most trendy dark matter candidate. I know a bit more about the work done by Clay Córdova, Thomas Dumitrescu, Shu-Heng Shao, and Yifan Wang, having met several of them in my physics career. They work on what are called generalized symmetries, concepts which go beyond the usual idea of how symmetry is supposed to work by involving more complicated tensors. I saw these crop up a fair bit in talks, but they were distant enough from my area that I never had a particularly clear grasp of what people were doing with them. I know even less about the work of the last three, Dillon Brout, J. Colin Hill, Mathew Madhavacheril, Maria Vincenzi, Daniel Scolnic, and W. L. Kimmy Wu, on cosmological measurements, but I was friends with Mathew in grad school and am impressed that he’s now working on cosmology given how little cosmology research there was at Stony Brook at the time.

Bonus Info for “Quantum ‘Jamming’ Explores the Truly Fundamental Principles of Nature”

I had a new piece in Quanta Magazine last week, about a hypothetical trick in theories beyond quantum mechanics called jamming.

Sometimes, I get science news stories from contacts. Sometimes I see an academic post something cool on X or Bluesky. But when the stories aren’t coming easy, I open up arXiv.org, click on “new”, and start browsing. And occasionally, I spot something cool.

That happened with jamming. I saw the concept mentioned in an abstract, the idea that someone could “jam” quantum entanglement from afar, like you would jam a radio signal. I hadn’t heard of it before. I wanted to know more. And after I talked to Quanta’s editors, they wanted to know more too.

Jamming is not possible under the rules of quantum mechanics we know. Instead, it’s something that could be possible in a kind of super-quantum mechanics, a theory even weirder than the famously weird theory we use today. In my piece for Quanta, I talked about where the idea of jamming comes from, and why it’s spurring discussion in recent years. In this post, I wanted to give some “bonus info” that didn’t fit into the piece.

One theme I didn’t have as much space to explore is causality.

Quantum mechanics famously seems to do weird things with cause and effect. In a double-slit experiment, photons pass one by one through one of two slits in a wall, headed to a photographic screen. No matter how slowly and carefully you send the photons, their distribution on the other end will show interference between the two possible paths, one through each slit, even though each photon only goes through one. It’s as if before hitting the screen, the photons are simultaneously traveling on every possible path, only to pick one in the moment the photon is detected.

Einstein was bothered by this. He imagined a photographic screen so large it would take light years to cross. How could detecting a photon on one side change the possibility of detecting a photon on the other side? That seemed, to him, to require signals traveling faster than light, which in turn would screw up cause and effect, as any way to send a signal faster than light can also, from another perspective, send a signal back in time.

The answer most physicists accept is that no signal can be sent in this way…at least, in the modern sense. Quantum outcomes are random, so while you could imagine that a measurement in one place changes the outcome in another place, your choice to measure has no effect on that distant outcome. You can’t intentionally send a message faster than light. We call that “no-signaling”, and it prevents the paradoxes of time travel.

Jamming obeys similar rules. A jammer (in the story in my article, a magician named Jim) can modify the entanglement between two distant particles, seemingly faster than light. But he can only do this in a way that involves randomness, so that the probabilities for measurement results for each individual particle stay the same. Instead, he can only modify how measurements between the two particles are related, their correlation. And he can only do this if the two particles can only be compared in a region that he can reach without traveling faster than light.

That’s enough to allow Jim to break the security of many quantum cryptography procedures. He can do this for example by mimicking entanglement: quantum cryptography often uses entanglement to verify that a message hasn’t been tampered with. If you can modify correlations from afar, you can make two particles appear to be entangled when actually they’re related by some other rules, which give you access to the secret that others are trying to hide.

Part of what’s still under discussion, is whether that kind of trick is compatible with causality. This depends a lot on how you think causality is supposed to work, and while the people I talked to are trying to get the story straight, they weren’t in agreement yet. In particular, Vilasini and Colbeck seemed to think that there was an important difference between the way that jamming bends causality and the way that ordinary quantum mechanics does, while Eckstein and Ramanathan weren’t so sure.

More broadly, Vilasini and Colbeck have a broader way of thinking about causality that I only barely touched on. Part of that is ways you can think of one event causing another even if no signal can be sent between them. Part of that is time loops, but of a limited kind: loops that can’t cause paradoxes, because they’re loops of causes, but not intentional signals. Vilasini and Colbeck have argued that jamming, if it existed, could be used to set up these kind of limited time loops, in a piece that was covered by New Scientist. It should be emphasized that these are really very limited time loops, for more reasons than one. They’re also limited to being in only one spatial dimension: that is, everyone in the loop has to be lined up in exactly a straight line. And I got the impression they also require everyone to activate their measurement or jamming devices instantly: with any small delay, the loop breaks.

I said even less about Mirjam Weilenmann’s critique, because there were bigger aspects that the researchers still disagreed on when I spoke with them. Weilenmann’s argument looks at what happens when there are multiple jammers, jamming different pairs of entangled particles. I got the impression from her that she felt she had found a contradiction in these examples, where jamming could only work if it broke its essential no-signaling rules. But Eckstein and Ramanathan seemed to think she was describing a scenario where one jammer could cause noise that would disrupt another jammer, “jamming the jammers” in a sense that didn’t cause any fundamental problems, just introduced jammer vs. jammer combat to make the story more interesting. I opted to not say much about this, since it was clear that things weren’t resolved yet. The researchers are still talking, and I look forward to hearing what they conclude when they reach agreement.

I also didn’t say much about tests in the real world. But that is something Eckstein and collaborators are actively exploring. They’re investigating experiments that could show deviations from quantum mechanics in a variety of contexts, from tabletops in university labs to particle colliders. The hope is that some of these strange ideas could actually be tested.

In general, the impression I got was that despite the seeds of this topic being laid thirty years ago, and reintroduced to the field ten years ago…the topic is heating up right now, in a way it hadn’t before. I’m expecting more jamming papers. If they’re cool enough, I may even cover some of them.

Trust Is a Tree

Scientists trust what they think they can verify.

In principle, you can work your way through the proof of every mathematical theorem. With enough money and time, you could replicate every experiment. For every expert opinion, you could dig through the literature and find how it was justified.

And while a scientist can’t actually do that for every field, they might be able to for the ones they care about most. In your specialty, you probably can check the logic behind every claim. And you know that enough people try, that you can trust your colleagues’ work.

As a science journalist, most of the time, you can’t do those checks. You don’t even pretend you can. Instead, you build trust, like a tree.

You start with a grounding. A former scientist might trust their former colleagues, people they trusted, as a scientist, to do (and know) good work. A non-scientist has to start somewhere else. They might use prestige, looking up those tenured folks at Harvard or Princeton or Stanford. They might look to who other journalists trusted, scientists who’ve already been in the news. They might track journals or roles, assuming that a publication in Nature, or a position on a national grant committee, has a special meaning.

And if things stopped there, it would be a pretty elitist system. It still can be, and often is. But there is another step, which softens it.

The trust builds.

When I want to know if a paper in an unfamiliar field makes sense, if it’s worth covering, I try to ask someone I trust. Sometimes, they don’t know, and shrug. Other, more useful, times, they don’t know, but they have a suggestion: someone they trust, who can give me the answer.

And so I ask the new person, and now I trust someone more.

And suppose the new person says the new paper is good, and worth covering, good science and all that jazz.

Well, now I can trust its authors too, right?

So when the next paper comes, I now don’t just have that first someone. I have the person they recommended, and the authors of the previous paper.

The trust builds out, and up, like branches on a tree.

The Twitter of Physics

The paper I talked about last week was frustratingly short. That’s not because the authors were trying to hide anything, or because they were lazy. It’s just that these days, that’s how the game is played.

Twitter started out with a fun gimmick: all posts had to be under 140 characters. The restriction inspired some great comedy, trying to pack as much humor as possible into a bite-sized format. Then, Twitter somehow became the place for journalists to discuss the news, tech people to discuss the industry, and politicians to discuss politics. Now, the length limit fuels conflict, an endless scroll of strong opinions without space for nuance.

Physics has something like this too.

In the 1950’s, it was hard for scientists to get the word out quickly about important results. The journal Physical Review had a trick: instead of normal papers, they’d accept breaking news in the form of letters to the editor, which they could publish more quickly than the average paper. In 1958, editor Samuel Goudsmit founded a new journal, Physical Review Letters (or PRL for short), that would publish those letters all in one place, enforcing a length limit to make them faster to process.

The new journal was a hit, and soon played host to a series of breakthrough results, as scientists chose it as a way to get their work out fast. That popularity created a problem, though. As PRL’s reputation grew, physicists started trying to publish there not because their results needed to get out fast, but because just by publishing in PRL, their papers would be associated with all of the famous breakthroughs the journal had covered. Goudsmit wrote editorials trying to slow this trend, but to no avail.

Now, PRL is arguably the most prestigious journal in physics, hosting over a quarter of Nobel prize-winning work. Its original motivation is no longer particularly relevant: the journal is not all that much faster than other journals in its area, if at all, and is substantially slower than the preprint server arXiv, which is where physicists actually read papers in practice.

The length limit has changed over the years, but not dramatically. It now sits at 3,750 words, typically allowing a five-or-six page article in tight two-column text.

If you see a physics paper on arXiv.org that fits the format, it’s almost certainly aimed at PRL, or one of the journals with similar policies that it inspired. It means the authors think their work is cool enough to hang out with a quarter of all Nobel-winning results, or at least would like it to be.

And that, in turn, means that anyone who wants to claim that prestige has to be concise. They have to leave out details (often, saving them for a later publication in a less-renowned journal). The results have to lean, by the journal’s nature, more to physicist-clickbait and a cleaned-up story than to anything their colleagues can actually replicate.

Is it fun? Yeah, I had some PRLs in my day. It’s a rush, shining up your work as far as it can go, trimming down complexities into six pages of essentials.

But I’m not sure it’s good for the field.

About the OpenAI Amplitudes Paper, but Not as Much as You’d Like

I’ve had a bit more time to dig in to the paper I mentioned last week, where OpenAI collaborated with amplitudes researchers, using one of their internal models to find and prove a simplified version of a particle physics formula. I figured I’d say a bit about my own impressions from reading the paper and OpenAI’s press release.

This won’t be a real “deep dive”, though it will be long nonetheless. As it turns out, most of the questions I’d like answers to aren’t answered in the paper or the press release. Getting them will involve actual journalistic work, i.e. blocking off time to interview people, and I haven’t done that yet. What I can do is talk about what I know so far, and what I’m still wondering.

Context:

Scattering amplitudes are formulas used by particle physicists to make predictions. For a while, people would just calculate these when they needed them, writing down pages of mess that you could plug in numbers to to get answers. However, forty years ago two physicists decided they wanted more, writing “we hope to obtain a simplified form for the answer, making our result not only an experimentalist’s, but a theorist’s delight.”

In their next paper, they managed to find that “theorist’s delight”: a simplified, intuitive-looking answer that worked for calculations involving any number of particles, summarizing many different calculations. Ten years later, a few people had started building on it, and ten years after that, the big shots started paying attention. A whole subfield, “amplitudeology”, grew from that seed, finding new forms of “theorists’s delight” in scattering amplitudes.

Each subfield has its own kind of “theory of victory”, its own concept for what kind of research is most likely to yield progress. In amplitudes, it’s these kinds of simplifications. When they work out well, they yield new, more efficient calculation techniques, yielding new messy results which can be simplified once more. To one extent or another, most of the field is chasing after those situations when simplification works out well.

That motivation shapes both the most ambitious projects of senior researchers, and the smallest student projects. Students often spend enormous amounts of time looking for a nice formula for something and figuring out how to generalize it, often on a question suggested by a senior researcher. These projects mostly serve as training, but occasionally manage to uncover something more impressive and useful, an idea others can build around.

I’m mentioning all of this, because as far as I can tell, what ChatGPT and the OpenAI internal model contributed here roughly lines up with the roles students have on amplitudes papers. In fact, it’s not that different from the role one of the authors, Alfredo Guevara, had when I helped mentor him during his Master’s.

Senior researchers noticed something unusual, suggested by prior literature. They decided to work out the implications, did some calculations, and got some messy results. It wasn’t immediately clear how to clean up the results, or generalize them. So they waited, and eventually were contacted by someone eager for a research project, who did the work to get the results into a nice, general form. Then everyone publishes together on a shared paper.

How impressed should you be?

I said, “as far as I can tell” above. What’s annoying is that this paper makes it hard to tell.

If you read through the paper, they mention AI briefly in the introduction, saying they used GPT-5.2 Pro to conjecture formula (39) in the paper, and an OpenAI internal model to prove it. The press release actually goes into more detail, saying that the humans found formulas (29)-(32), and GPT-5.2 Pro found a special case where it could simplify them to formulas (35)-(38), before conjecturing (39). You can get even more detail from an X thread by one of the authors, OpenAI Research Scientist Alex Lupsasca. Alex had done his PhD with another one of the authors, Andrew Strominger, and was excited to apply the tools he was developing at OpenAI to his old research field. So they looked for a problem, and tried out the one that ended up in the paper.

What is missing, from the paper, press release, and X thread, is any real detail about how the AI tools were used. We don’t have the prompts, or the output, or any real way to assess how much input came from humans and how much from the AI.

(We have more for their follow-up paper, where Lupsasca posted a transcript of the chat.)

Contra some commentators, I don’t think the authors are being intentionally vague here. They’re following business as usual. In a theoretical physics paper, you don’t list who did what, or take detailed account of how you came to the results. You clean things up, and create a nice narrative. This goes double if you’re aiming for one of the most prestigious journals, which tend to have length limits.

This business-as-usual approach is ok, if frustrating, for the average physics paper. It is, however, entirely inappropriate for a paper showcasing emerging technologies. For a paper that was going to be highlighted this highly by OpenAI, the question of how they reached their conclusion is much more interesting than the results themselves. And while I wouldn’t ask them to go to the standards of an actual AI paper, with ablation analysis and all that jazz, they could at least have aimed for the level of detail of my final research paper, which gave samples of the AI input and output used in its genetic algorithm.

For the moment, then, I have to guess what input the AI had, and what it actually accomplished.

Let’s focus on the work done by the internal OpenAI model. The descriptions I’ve seen suggest that it started where GPT-5.2 Pro did, with formulas (29)-(32), but with a more specific prompt that guided what it was looking for. It then ran for 12 hours with no additional input, and both conjectured (39) and proved it was correct, providing essentially the proof that follows formula (39) in the paper.

Given that, how impressed should we be?

First, the model needs to decide to go to a specialized region, instead of trying to simplify the formula in full generality. I don’t know whether they prompted their internal model explicitly to do this. It’s not something I’d expect a student to do, because students don’t know what types of results are interesting enough to get published, so they wouldn’t be confident in computing only a limited version of a result without an advisor telling them it was ok. On the other hand, it is actually something I’d expect an LLM to be unusually likely to do, as a result of not managing to consistently stick to the original request! What I don’t know is whether the LLM proposed this for the right reason: that if you have the formula for one region, you can usually find it for other regions.

Second, the model needs to take formulas (29)-(32), write them in the specialized region, and simplify them to formulas (35)-(38). I’ve seen a few people saying you can do this pretty easily with Mathematica. That’s true, though not every senior researcher is comfortable doing that kind of thing, as you need to be a bit smarter than just using the Simplify[] command. Most of the people on this paper strike me as pen-and-paper types who wouldn’t necessarily know how to do that. It’s definitely the kind of thing I’d expect most students to figure out, perhaps after a couple of weeks of flailing around if it’s their first crack at it. The LLM likely would not have used Mathematica, but would have used SymPy, since these “AI scientist” setups usually can write and execute Python code. You shouldn’t think of this as the AI reasoning through the calculation itself, but it at least sounds like it was reasonably quick at coding it up.

Then, the model needs to conjecture formula (39). This gets highlighted in the intro, but as many have pointed out, it’s pretty easy to do. If any non-physicists are still reading at this point, take a look:

Could you guess (39) from (35)-(38)?

After that, the paper goes over the proof that formula (39) is correct. Most of this proof isn’t terribly difficult, but the way it begins is actually unusual in an interesting way. The proof uses ideas from time-ordered perturbation theory, an old-fashioned way to do particle physics calculations. Time-ordered perturbation theory isn’t something any of the authors are known for using with regularity, but it has recently seen a resurgence in another area of amplitudes research, showing up for example in papers by Matthew Schwartz, a colleague of Strominger at Harvard.

If a student of Strominger came up with an idea drawn from time-ordered perturbation theory, that would actually be pretty impressive. It would mean that, rather than just learning from their official mentor, this student was talking to other people in the department and broadening their horizons, showing a kind of initiative that theoretical physicists value a lot.

From an LLM, though, this is not impressive in the same way. The LLM was not trained by Strominger, it did not learn specifically from Strominger’s papers. Its context suggested it was working on an amplitudes paper, and it produced an idea which would be at home in an amplitudes paper, just a different one than the one it was working on.

While not impressive, that capability may be quite useful. Academic subfields can often get very specialized and siloed. A tool that suggests ideas from elsewhere in the field could help some people broaden their horizons.

Overall, it appears that that twelve-hour OpenAI internal model run reproduced roughly what an unusually bright student would be able to contribute over the course of a several-month project. Like most student projects, you could find a senior researcher who could do the project much faster, maybe even faster than the LLM. But it’s unclear whether any of the authors could have: different senior researchers have different skillsets.

A stab at implications:

If we take all this at face-value, it looks like OpenAI’s internal model was able to do a reasonably competent student project with no serious mistakes in twelve hours. If they started selling that capability, what would happen?

If it’s cheap enough, you might wonder if professors would choose to use the OpenAI model instead of hiring students. I don’t think this would happen, though: I think it misunderstands why these kinds of student projects exist in a theoretical field. Professors sometimes use students to get results they care about, but more often, the student’s interest is itself the motivation, with the professor wanting to educate someone, to empire-build, or just to take on their share of the department’s responsibilities. AI is only useful for this insofar as AI companies continue reaching out to these people to generate press releases: once this is routinely possible, the motivation goes away.

More dangerously, if it’s even cheaper, you could imagine students being tempted to use it. The whole point of a student project is to train and acculturate the student, to get them to the point where they have affection for the field and the capability to do more impressive things. You can’t skip that, but people are going to be tempted to.

And of course, there is the broader question of how much farther this technology can go. That’s the hardest to estimate here, since we don’t know the prompts used. So I don’t know if seeing this result tells us anything more about the bigger picture than we knew going in.

Remaining questions:

At the end of the day, there are a lot of things I still want to know. And if I do end up covering this professionally, they’re things I’ll ask.

  1. What was the prompt given to the internal model, and how much did it do based on that prompt?
  2. Was it really done in one shot, no retries or feedback?
  3. How much did running the internal model cost?
  4. Is this result likely to be useful? Are there things people want to calculate that this could make easier? Recursion relations it could seed? Is it useful for SCET somehow?
  5. How easy would it have been for the authors to do what the LLM did? What about other experts in the community?