Tag Archives: Machine Learning

Better Bounds

I swear this isn’t turning into an AI blog. But did you see the one about the Riemann hypothesis?

Someone at Anthropic did something I’m sure they’re all tempted to do, and tried to use an internal version of their Claude AI system to prove the most famous open conjecture in mathematics. It didn’t work, to be clear, and I get the impression they didn’t expect it to. But out of six hundred or so fruitless tries, one attempt did prove a new bound. Previously, mathematicians had been able to prove that at least 41.6% of the zeroes of the Riemann zeta function satisfied the Riemann hypothesis. Now, the new proof shows that at least 67.2% satisfy it.

Anthropic’s press release is impressively careful. As someone who’s had to think about how to write content that both excites the public and doesn’t piss off experts too much, they do an admirable job walking that line. They even say, straight-out, “We don’t expect that the techniques Claude used will lead to proving the Riemann hypothesis.”

Bounds are like that, sometimes.

I should know. Physicists also find bounds.

Physics has its own conjectures with the fame of the Riemann hypothesis. Dark matter might be made of detectable particles. Protons could decay. There might be extra dimensions, or magnetic monopoles, or cosmic strings. General relativity might be subtly wrong.

It would be an amazing achievement to demonstrate any of these things. But most physicists won’t manage that. Instead, they bound them.

Physicists compete to get better bounds, excluding unusual possibilities with greater and greater care. They find evidence that dark matter can’t be of a specific mass with a specific charge, so the next experiment has to look somewhere else, or find evidence that general relativity holds to even greater precision, so any deviation must be even smaller. Some work to improve experiments with better and better bounds. Others analyze data from older experiments, or find under-appreciated consequences of known facts, and can get even better bounds.

Bounds aren’t typically newsworthy (though occasionally they make it through), so most people don’t hear about them. If you read the news, you hear about positive claims much more often than negative ones: evidence for something new, not evidence that our current knowledge holds. But the nature of physics is that most work supports the status quo. Most work improves bounds.

Do bounds lead, with time, to the positive claims? Sometimes, but not always. Often, bounds are just bounds. They’re attempts to use the methods physicists have to learn something new about the world. Even if the new fact is just “don’t look here”.

It Only Counts When AI Gets to My Field

It’s a meme at this point.

When Deep Blue beat Kasparov, Go players could say that their game, unlike Chess, was too complex to fall to a computer program. Then AlphaGo showed they were wrong. It just took a better approach.

When AlphaFold leaped ahead of human experts in predicting how proteins fold, it was due to a mountain of carefully labeled protein structure data. Other scientists and mathematicians could argue that nothing like that existed in their field, so a similar success was unlikely. But LLMs can now navigate scientific literature, and loosely imitate the reasoning process of a mathematical proof. And increasingly, the math and computer science results coming out of AI labs are ones that humans find impressive.

Now, experts argue about how far AI can really go. Will AI mathematics only be good at finding counterexamples and solving cute puzzles, not introducing new concepts and frameworks? Will AI only be meaningfully good at fields like mathematics with clear rules and carefully collected conjectures, not fuzzier fields like physics? Will AI-powered labs only manage to optimize specific procedures, and not carry out entire experimental programs? Each time, the pattern seems to be that scholars are skeptical, until AI gets to their field.

I’m aware of this pattern. But I’m willing to take the risk.

I think my old field, scattering amplitudes, is special. And when AI can do something meaningful there, I’ll really start to worry.

By “something meaningful”, I don’t mean the student-level results that have come out so far. I mean tackling some of the field’s big outstanding problems: determining whether N=8 supergravity diverges at seven loops, or finding the six-particle amplitude in N=4 super Yang-Mills to nine loops. Getting another loop past the state of the art for gravitational wave physics or collider physics would also count.

These problems are difficult not just because people haven’t had the right ideas, but because they’re hard in a computational sense. Each loop, a rough measure of the precision of the end result, represents an increase in complexity, in calculations that typically scale exponentially or even factorially in the number of loops. In principle, amplitudes researchers could do any of these with no new ideas, just using known methods. They’d just need access to a lot more computing power.

See, while everyone else is preoccupied with whether AI can come up with genuinely new ideas, I think the real measure is what those ideas accomplish. And the most important measure of accomplishment, if you’re worried about how scared to be about AI, is whether it can do things that seem like they would take too much computing power.

In the past, when people dreamed up the scariest hypothetical things AI could achieve, critics argued they were impossible due to a lack of computing power. Apocalypse scenarios often involve designing self-replicating nanobots based on computer models of molecules, or unstoppable social manipulation based on simulating the minds of the humans the AI interacts with. If AI is going to manage these things, or something like them, it will take an approach that somehow bypasses that need for more computers than we can build.

So if AI companies want to impress people like me (or scare us, for that matter), then they need to tackle my old field. Show that an AI can take the kinds of computer resources an academic has access to, and solve one of the scattering amplitudes field’s big outstanding problems. Show that a computational limit everyone expected to be a problem doesn’t actually matter. Give us N=8 supergravity to seven loops, or N=4 super Yang-Mills to nine loops.

An AI Opinions Chart

You ever read something and suddenly a whole classification scheme lights up in your head?

A thread on X from “stringking42069” showed me a combination of opinions I hadn’t seen before. stringking42069 is a pro-string theory commentator with a macho gym bro memer gimmick. He’s openly contemptuous of many physicists who describe themselves as string theorists, arguing that only a smaller number really deserve the name.

To be clear, none of that is the new combination. Long-time readers of this blog will remember a frequent commenter with a very similar attitude, if much less tendency to use the word “bro”.

The new thing, from my perspective, is how he thinks about AI. As he explains in that thread, he sees AI as great at certain kinds of physics calculations, ones where the methods and goals are mostly known and the challenge is working out the math. He doesn’t expect it to be able to contribute real creativity or judgement, the messy decision-making that physicists use to decide what is worth building in the first place.

Others with that perspective tend to argue that this will be a boon for scientists, who AI will free up to do creative work, multiplying their output. The difference is, stringking42069 thinks a lot of scientists are not doing creative work in the first place, including most of the people making extensive use of AI. So if anything he’s happy to see them go, and only pissed that they’re sucking up resources and attention on the way out, and discouraging students who could be joining the parts of the field that do real creative work.

It made me realize that there are two axes to thinking about AI in physics.

On the one hand, there’s where you think AI capabilities are. Is AI going to lead to “a nation of geniuses in a data center”, an AI-powered super-(cyber-)Ed Witten for everything and everyone? Is AI great at routine work and coding, but will never be able to do anything really creative or novel? Or is AI total hype, almost always a waste of time?

On the other hand, there’s another axis: misanthropy about science. For some of the people arguing about AI online, most scientists are good people trying their best to do worthwhile things. For others, most scientists are complacent and cliquish, wasting time and money on ideas that are going nowhere and forcing the real geniuses out of the field.

Put those together, and you get the table below:

Thinks academia is mostly fineMisanthrope
AI geniuses are comingThe practice of science will change. We’ll play at science like chess, and have fun trying to read and understand amazing AI insights.Soon all scientists will be out of a job when the public notices AI can do it all better. Then the real breakthroughs will come.
AI can do routine workAI frees scientists to focus on what we do best: creativity. We should think carefully about how to train junior scientists now, though.AI is comparable to bad scientists who only do derivative work. If they leave, we real paradigm-changers could inherit the field.
AI is complete hypeMost scientists don’t use AI. AI is worrying because it misleads students and the public, who should listen to real scientists.Scientists are shilling for AI companies, as you should expect for people who waste the public’s money on reputation games.

This classification is missing a lot, of course. One important question is not just what AI can do in principle, but what it can do cost-effectively, and whether anyone is actually willing to pay for it. A point where I agree with stringking42069 is that companies get a lot of good PR out of building AI physicists right now, and that PR benefit won’t be relevant forever. I’m also leaving out the more general questions of AI’s effect on society, for example people who think AI geniuses will lead to the end of the world as we know it.

But I suspect if you look at this table, you can already start matching the scientists you see on social media. I’ve seen examples of all of these in the wild (though the bottom-left is somewhat rare, as far as I can tell). Where do you fall?

Make No Mistakes

I’m taking a Danish exam next week, and it’s a big one, a culmination of years learning the language. My classmates are stressed. Despite how much we’ve learned, it feels like we’re always making little mistakes. We write the wrong prepositions, put verbs in the wrong form, or mess up the order of words in a sentence. And while we should have time to check our work, that doesn’t help as much as it should. If we don’t notice a mistake the first time around, what guarantee is there that we notice it on the next read, or the next? Too many checks and we can even end up second-guessing ourselves, “correcting” something that was right to begin with.

It’s given me some sympathy for AI.

Earlier this month, investor Marc Andreessen posted a custom prompt he inputs when using AI, which was immediately mocked.

The silliest instruction, according to many critics, was to “Never hallucinate or make anything up.” It’s similar to a prompt that’s become a meme used to make fun of AI-using “vibe coders”, “Make no mistakes”.

Experts point out that this is just not how AI works. Large language model-powered programs like ChatGPT are inherently random, producing text largely based on its similarity to other text. “Hallucinations” or “mistakes” are an inevitable feature of the technology, and a prompt like Andreessen wrote isn’t a set of instructions the AI will follow without error: it’s just another part of the text the AI is trying to generate.

All that said, telling an AI to “make no mistakes” should have some effect. But it likely won’t be what you want.

The best way I’ve found to understand AI is in terms of stories. Chatbots like ChatGPT take a large language model, a mathematical formula for how words are most likely to appear in a text, and warp it, twisting it to almost always produce one particular kind of text: one half of a dialogue with a fictional AI assistant. This twisted formula determines how the AI responds to your prompts, but these days it also is used behind the scenes, in a kind of structured soliloquy called a “chain of thought”. You can think of the prompts you send to the AI as a preface to those soliloquies, and imagine the AI telling stories of a sort that would typically follow that preface.

So if you tell an AI “make no mistakes” or “do not hallucinate”, you’re making it more likely to generate the kind of story that begins, “the AI was instructed to make no mistakes”.

Let me put it this way, Mr. Amor. The 9000 series is the most reliable computer ever made. No 9000 computer has ever made a mistake or distorted information. We are all, by any practical definition of the words, foolproof and incapable of error. – HAL 9000, “2001: A Space Odyssey”

You’d expect this to affect the chain of thought. For example, the AI might occasionally pause to say “I’m supposed to make no mistakes, so I should check this. What could have gone wrong?” and then list something that plausibly could be wrong with its idea. If this happens often enough, you’ll probably catch some real problems.

But I’m reminded of my classmates, practicing for that Danish exam. We can go over the text again and again, asking if this thing, or that, might be wrong. We can try again and again to use our mental model of the Danish language, seeing if this time it catches a new mistake. But there are things we won’t catch. And if we do it too much, we’ll second-guess ourselves out of the good answers, too.

Ultimately, “make no mistakes” isn’t a great instruction, either for humans or for chatbots. And its use by people like Marc Andreessen has me wondering if they are used to interacting with humans in the same way, as tools that keep making mistakes no matter how many times they’re instructed not to, requiring more and more long-winded instructions and yet continuing to misbehave.

Then again, that may be a mistake on my part.

What AI Physicists Are Missing and What They Aren’t

I’ve seen a couple more thoughtful takes on use of LLMs for physics lately. This blog post by Minas Karamis is particularly nice.

He points out something that I’ve said a version of: an AI that must be supervised like a student isn’t very useful, because the main point of student projects isn’t the paper at the end: it’s training the student. If students don’t struggle through all the mistakes of a project, they won’t get the expertise to one day do greater things.

Someone might object that not all suffering is educational. In the 1700’s, Leonhard Euler calculated digit after digit of transcendental numbers by hand. Nobody asks students to do that anymore, and they still seem to turn out alright. Why would using an LLM for science be worse than using a computer for numerical calculations?

In a word: different skills. Programming numerics teaches you some of the same skills as calculating the numbers by hand: skills at being specific about what you mean, aware of the consequences of the details and their implications. Prompting an AI still requires those skills, to check whether the AI’s output is correct. But it’s much worse at teaching them: unlike programming or calculating, when prompting AI, the consequences of your actions aren’t predictable.

For some, though, there is another objection. Sure, using AI reliably might require those skills now. But when it gets better, surely being careful will stop mattering. Surely the AI will end up doing science on its own, and all that training will be as useful as if we trained the students to play football.

I’m skeptical, but not as strongly as some. I think we’re still living in a time when it makes sense to hire scientists, and train people to think, and invest in your retirement.

I don’t think I have any knock-down arguments for that, though. Just some suggestive ones.

One I’ve talked about before is that a lot of the most important parts of thinking aren’t written down. An AI physicist is going to have a hard time replicating the kinds of methods and approaches that people use behind the scenes, but rarely describe or spell out. It will be easier to suss this out over time, as more data accumulates of people working with LLMs and correcting them. But ultimately there isn’t going to be a lot of documentation of this kind of thing.

Another limitation is memory. A mature scientist can draw from experiences across their entire career. For an LLM, any problem it’s solved in the past is by default lost in each new session. People build structures around this, taking notes and reminding the AI when it “wakes up”, or making documents the AI can be prompted to check. But nothing in this vein so far seems to get nearly as wide-scope or powerful as human memory. A scientist career is still the best way we have to build durable, functional expertise.

Finally, there is a question of costs, and efficiency. Here I’m not an expert, and I get the impression the actual experts disagree. I don’t know whether we should expect scaling to hit a wall, but I wouldn’t be that surprised if it did.

There are other common reasons for skepticism that seem more dubious to me. I don’t think AI is inherently worse at creativity just because they’re trained on existing work, though some of the skills we associate with creativity aren’t very well-documented, and thus are hard to train for. I don’t think AI’s randomness or unreliability is a deal-breaker, because human intuition is also random and unreliable: we solve that with tools, and that’s something AI can in principle do as well. I don’t think humans are “more agentic” or something, except in the sense that most AIs are made by companies who need to make them behave in a customer-friendly way. But an agent is just a game-theoretic construct, a way to figure out can win or lose in situations with defined stakes, and anything you can train or engineer to try to win can be modeled by that construct.

Coming from a place of uncertainty, my main appeal to you is to not get hung up on the bad reasons, either yourself, or from the people you’re arguing with. Focus on the best arguments, and see where they take you.

About the OpenAI Amplitudes Paper, but Not as Much as You’d Like

I’ve had a bit more time to dig in to the paper I mentioned last week, where OpenAI collaborated with amplitudes researchers, using one of their internal models to find and prove a simplified version of a particle physics formula. I figured I’d say a bit about my own impressions from reading the paper and OpenAI’s press release.

This won’t be a real “deep dive”, though it will be long nonetheless. As it turns out, most of the questions I’d like answers to aren’t answered in the paper or the press release. Getting them will involve actual journalistic work, i.e. blocking off time to interview people, and I haven’t done that yet. What I can do is talk about what I know so far, and what I’m still wondering.

Context:

Scattering amplitudes are formulas used by particle physicists to make predictions. For a while, people would just calculate these when they needed them, writing down pages of mess that you could plug in numbers to to get answers. However, forty years ago two physicists decided they wanted more, writing “we hope to obtain a simplified form for the answer, making our result not only an experimentalist’s, but a theorist’s delight.”

In their next paper, they managed to find that “theorist’s delight”: a simplified, intuitive-looking answer that worked for calculations involving any number of particles, summarizing many different calculations. Ten years later, a few people had started building on it, and ten years after that, the big shots started paying attention. A whole subfield, “amplitudeology”, grew from that seed, finding new forms of “theorists’s delight” in scattering amplitudes.

Each subfield has its own kind of “theory of victory”, its own concept for what kind of research is most likely to yield progress. In amplitudes, it’s these kinds of simplifications. When they work out well, they yield new, more efficient calculation techniques, yielding new messy results which can be simplified once more. To one extent or another, most of the field is chasing after those situations when simplification works out well.

That motivation shapes both the most ambitious projects of senior researchers, and the smallest student projects. Students often spend enormous amounts of time looking for a nice formula for something and figuring out how to generalize it, often on a question suggested by a senior researcher. These projects mostly serve as training, but occasionally manage to uncover something more impressive and useful, an idea others can build around.

I’m mentioning all of this, because as far as I can tell, what ChatGPT and the OpenAI internal model contributed here roughly lines up with the roles students have on amplitudes papers. In fact, it’s not that different from the role one of the authors, Alfredo Guevara, had when I helped mentor him during his Master’s.

Senior researchers noticed something unusual, suggested by prior literature. They decided to work out the implications, did some calculations, and got some messy results. It wasn’t immediately clear how to clean up the results, or generalize them. So they waited, and eventually were contacted by someone eager for a research project, who did the work to get the results into a nice, general form. Then everyone publishes together on a shared paper.

How impressed should you be?

I said, “as far as I can tell” above. What’s annoying is that this paper makes it hard to tell.

If you read through the paper, they mention AI briefly in the introduction, saying they used GPT-5.2 Pro to conjecture formula (39) in the paper, and an OpenAI internal model to prove it. The press release actually goes into more detail, saying that the humans found formulas (29)-(32), and GPT-5.2 Pro found a special case where it could simplify them to formulas (35)-(38), before conjecturing (39). You can get even more detail from an X thread by one of the authors, OpenAI Research Scientist Alex Lupsasca. Alex had done his PhD with another one of the authors, Andrew Strominger, and was excited to apply the tools he was developing at OpenAI to his old research field. So they looked for a problem, and tried out the one that ended up in the paper.

What is missing, from the paper, press release, and X thread, is any real detail about how the AI tools were used. We don’t have the prompts, or the output, or any real way to assess how much input came from humans and how much from the AI.

(We have more for their follow-up paper, where Lupsasca posted a transcript of the chat.)

Contra some commentators, I don’t think the authors are being intentionally vague here. They’re following business as usual. In a theoretical physics paper, you don’t list who did what, or take detailed account of how you came to the results. You clean things up, and create a nice narrative. This goes double if you’re aiming for one of the most prestigious journals, which tend to have length limits.

This business-as-usual approach is ok, if frustrating, for the average physics paper. It is, however, entirely inappropriate for a paper showcasing emerging technologies. For a paper that was going to be highlighted this highly by OpenAI, the question of how they reached their conclusion is much more interesting than the results themselves. And while I wouldn’t ask them to go to the standards of an actual AI paper, with ablation analysis and all that jazz, they could at least have aimed for the level of detail of my final research paper, which gave samples of the AI input and output used in its genetic algorithm.

For the moment, then, I have to guess what input the AI had, and what it actually accomplished.

Let’s focus on the work done by the internal OpenAI model. The descriptions I’ve seen suggest that it started where GPT-5.2 Pro did, with formulas (29)-(32), but with a more specific prompt that guided what it was looking for. It then ran for 12 hours with no additional input, and both conjectured (39) and proved it was correct, providing essentially the proof that follows formula (39) in the paper.

Given that, how impressed should we be?

First, the model needs to decide to go to a specialized region, instead of trying to simplify the formula in full generality. I don’t know whether they prompted their internal model explicitly to do this. It’s not something I’d expect a student to do, because students don’t know what types of results are interesting enough to get published, so they wouldn’t be confident in computing only a limited version of a result without an advisor telling them it was ok. On the other hand, it is actually something I’d expect an LLM to be unusually likely to do, as a result of not managing to consistently stick to the original request! What I don’t know is whether the LLM proposed this for the right reason: that if you have the formula for one region, you can usually find it for other regions.

Second, the model needs to take formulas (29)-(32), write them in the specialized region, and simplify them to formulas (35)-(38). I’ve seen a few people saying you can do this pretty easily with Mathematica. That’s true, though not every senior researcher is comfortable doing that kind of thing, as you need to be a bit smarter than just using the Simplify[] command. Most of the people on this paper strike me as pen-and-paper types who wouldn’t necessarily know how to do that. It’s definitely the kind of thing I’d expect most students to figure out, perhaps after a couple of weeks of flailing around if it’s their first crack at it. The LLM likely would not have used Mathematica, but would have used SymPy, since these “AI scientist” setups usually can write and execute Python code. You shouldn’t think of this as the AI reasoning through the calculation itself, but it at least sounds like it was reasonably quick at coding it up.

Then, the model needs to conjecture formula (39). This gets highlighted in the intro, but as many have pointed out, it’s pretty easy to do. If any non-physicists are still reading at this point, take a look:

Could you guess (39) from (35)-(38)?

After that, the paper goes over the proof that formula (39) is correct. Most of this proof isn’t terribly difficult, but the way it begins is actually unusual in an interesting way. The proof uses ideas from time-ordered perturbation theory, an old-fashioned way to do particle physics calculations. Time-ordered perturbation theory isn’t something any of the authors are known for using with regularity, but it has recently seen a resurgence in another area of amplitudes research, showing up for example in papers by Matthew Schwartz, a colleague of Strominger at Harvard.

If a student of Strominger came up with an idea drawn from time-ordered perturbation theory, that would actually be pretty impressive. It would mean that, rather than just learning from their official mentor, this student was talking to other people in the department and broadening their horizons, showing a kind of initiative that theoretical physicists value a lot.

From an LLM, though, this is not impressive in the same way. The LLM was not trained by Strominger, it did not learn specifically from Strominger’s papers. Its context suggested it was working on an amplitudes paper, and it produced an idea which would be at home in an amplitudes paper, just a different one than the one it was working on.

While not impressive, that capability may be quite useful. Academic subfields can often get very specialized and siloed. A tool that suggests ideas from elsewhere in the field could help some people broaden their horizons.

Overall, it appears that that twelve-hour OpenAI internal model run reproduced roughly what an unusually bright student would be able to contribute over the course of a several-month project. Like most student projects, you could find a senior researcher who could do the project much faster, maybe even faster than the LLM. But it’s unclear whether any of the authors could have: different senior researchers have different skillsets.

A stab at implications:

If we take all this at face-value, it looks like OpenAI’s internal model was able to do a reasonably competent student project with no serious mistakes in twelve hours. If they started selling that capability, what would happen?

If it’s cheap enough, you might wonder if professors would choose to use the OpenAI model instead of hiring students. I don’t think this would happen, though: I think it misunderstands why these kinds of student projects exist in a theoretical field. Professors sometimes use students to get results they care about, but more often, the student’s interest is itself the motivation, with the professor wanting to educate someone, to empire-build, or just to take on their share of the department’s responsibilities. AI is only useful for this insofar as AI companies continue reaching out to these people to generate press releases: once this is routinely possible, the motivation goes away.

More dangerously, if it’s even cheaper, you could imagine students being tempted to use it. The whole point of a student project is to train and acculturate the student, to get them to the point where they have affection for the field and the capability to do more impressive things. You can’t skip that, but people are going to be tempted to.

And of course, there is the broader question of how much farther this technology can go. That’s the hardest to estimate here, since we don’t know the prompts used. So I don’t know if seeing this result tells us anything more about the bigger picture than we knew going in.

Remaining questions:

At the end of the day, there are a lot of things I still want to know. And if I do end up covering this professionally, they’re things I’ll ask.

  1. What was the prompt given to the internal model, and how much did it do based on that prompt?
  2. Was it really done in one shot, no retries or feedback?
  3. How much did running the internal model cost?
  4. Is this result likely to be useful? Are there things people want to calculate that this could make easier? Recursion relations it could seed? Is it useful for SCET somehow?
  5. How easy would it have been for the authors to do what the LLM did? What about other experts in the community?
Hypothesis: If AI Is Bad at Originality, It’s a Documentation Problem

Recently, a few people have asked me about this paper.

A couple weeks back, OpenAI announced a collaboration with a group of amplitudes researchers, physicists who study the types of calculations people do to make predictions at particle colliders. The amplitudes folks had identified an interesting loophole, finding a calculation that many would have expected to be zero actually gave a nonzero answer. They did the calculation for different examples involving more and more particles, and got some fairly messy answers. They suspected, as amplitudes researchers always expect, that there was a simpler formula, one that worked for any number of particles. But they couldn’t find it.

Then a former amplitudes researcher at OpenAI suggested that they use AI to find it.

“Use AI” can mean a lot of different things, and most of them don’t look much like the way the average person talks to ChatGPT. This was closer than most. They were using “reasoning models”, loops that try to predict the next few phrases in a “chain of thought” again and again and again. Using that kind of tool, they were able to find that simpler formula, and mathematically prove that it was correct.

A few of you are hoping for an in-depth post about what they did, and its implications. This isn’t that. I’m still figuring out if I’ll be writing that for an actual news site, for money, rather than free, for you folks.

Instead, I want to talk about a specific idea I’ve seen crop up around the paper.

See, for some, the existence of a result like this isn’t all that surprising.

Mathematicians have been experimenting with reasoning models for a bit, now. Recently, a group published a systematic study, setting the AI loose on a database of minor open problems proposed by the famously amphetamine-fueled mathematician Paul Erdös. The AI managed to tackle a few of the problems, sometimes by identifying existing solutions that had not yet been linked to the problem database, but sometimes by proofs that appeared to be new.

The Erdös problems solved by the AI were not especially important. Neither was the problem solved by the amplitudes researchers, as far as I can tell at this point.

But I get the impression the amplitudes problem was a bit more interesting than the Erdös problems. The difference, so far, has mostly been attributed to human involvement. This amplitudes paper started because human amplitudes researchers found an interesting loophole, and only after that used the AI. Unlike the mathematicians, they weren’t just searching a database.

This lines up with a general point, one people tend to make much less carefully. It’s often said that, unlike humans, AI will never be truly creative. It can solve mechanical problems, do things people have done before, but it will never be good at having truly novel ideas.

To me, that line of thinking goes a bit too far. I suspect it’s right on one level, that it will be hard for any of these reasoning models to propose anything truly novel. But if so, I think it will be for a different reason.

The thing is, creativity is not as magical as we make it out to be. Our ideas, scientific or artistic, don’t just come from the gods. They recombine existing ideas, shuffling them in ways more akin to randomness than miracle. They’re then filtered through experience, deep heuristics honed over careers. Some people are good at ideas, and some are bad at them. Having ideas takes work, and there are things people do to improve their ideas. Nothing about creativity suggests it should be impossible to mechanize.

However, a machine trained on text won’t necessarily know how to do any of that.

That’s because in science, we don’t write down our inspirations. By the time a result gets into a scientific paper or textbook, it’s polished and refined into a pure argument, cutting out most of the twists and turns that were an essential part of the creative process. Mathematics is even worse, most math papers don’t even mention the motivation behind the work, let alone the path taken to the paper.

This lack of documentation makes it hard for students, making success much more a function of having the right mentors to model good practices, rather than being able to pick them up from literature everyone can access. I suspect it makes it even harder for language models. And if today’s language model-based reasoning tools are bad at that crucial, human-seeming step, of coming up with the right idea at the right time? I think that has more to do with this lack of documentation, than with the fact that they’re “statistical parrots”.

The Timeline for Replacing Theorists Is Not Technological

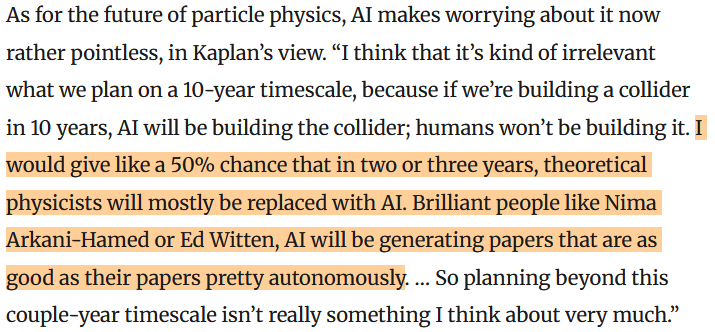
Quanta Magazine recently published a reflection by Natalie Wolchover on the state of fundamental particle physics. The discussion covers a lot of ground, but one particular paragraph has gotten the lion’s share of the attention. Wolchover talked to Jared Kaplan, the ex-theoretical physicist turned co-founder of Anthropic, one of the foremost AI companies today.

Kaplan was one of Nima Arkani-Hamed’s PhD students, which adds an extra little punch.

There’s a lot to contest here. Is AI technology anywhere close to generating papers as good as the top physicists, or is that relegated to the sci-fi future? Does Kaplan really believe this, or is he just hyping up his company?

I don’t have any special insight into those questions, about the technology and Kaplan’s motivations. But I think that, even if we trusted him on the claim that AI could be generating Witten- or Nima-level papers in three years, that doesn’t mean it will replace theoretical physicists. That part of the argument isn’t a claim about the technology, but about society.

So let’s take the technological claims as given, and make them a bit more specific. Since we don’t have any objective way of judging the quality of scientific papers, let’s stick to the subjective. Today, there are a lot of people who get excited when Witten posts a new paper. They enjoy reading them, they find the insights inspiring, they love the clarity of the writing and their tendency to clear up murky ideas. They also find them reliable: the papers very rarely have mistakes, and don’t leave important questions unanswered.

Let’s use that as our baseline, then. Suppose that Anthropic had an AI workflow that could reliably write papers that were just as appealing to physicists as Witten’s papers are, for the same reasons. What happens to physicists?

Witten himself is retired, which for an academic means you do pretty much the same thing you were doing before, but now paid out of things like retirement savings and pension funds, not an institute budget. Nobody is going to fire Witten, there’s no salary to fire him from. And unless he finds these developments intensely depressing and demoralizing (possible, but very much depends on how this is presented), he’s not going to stop writing papers. Witten isn’t getting replaced.

More generally, though, I don’t think this directly results in anyone getting fired, or in universities trimming positions. The people making funding decisions aren’t just sitting on a pot of money, trying to maximize research output. They’ve got money to be spent on hires, and different pools of money to be spent on equipment, and the hires get distributed based on what current researchers at the institutes think is promising. Universities want to hire people who can get grants, to help fund the university, and absent rules about AI personhood, the AIs won’t be applying for grants.

Funding cuts might be argued for based on AI, but that will happen long before AI is performing at the Witten level. We already see this happening in other industries or government agencies, where groups that already want to cut funding are getting think tanks and consultants to write estimates that justify cutting positions, without actually caring whether those estimates are performed carefully enough to justify their conclusions. That can happen now, and doesn’t depend on technological progress.

AI could also replace theoretical physicists in another sense: the physicists themselves might use AI to do most of their work. That’s more plausible, but here adoption still heavily depends on social factors. Will people feel like they are being assessed on whether they can produce these Witten-level papers, and that only those who make them get hired, or funded? Maybe. But it will propagate unevenly, from subfield to subfield. Some areas will make their own rules forbidding AI content, there will be battles and scandals and embarrassments aplenty. It won’t be a single switch, the technology alone setting the timeline.

Finally, AI could replace theoretical physicists in another way, by people outside of academia filling the field so much that theoretical physicists have nothing more that they want to do. Some non-physicists are very passionate about physics, and some of those people have a lot of money. I’ve done writing work for one such person, whose foundation is now attempting to build an AI Physicist. If these AI Physicists get to Witten-level quality, they might start writing compelling paper after compelling paper. Those papers, though, will due to their origins be specialized. Much as philanthropists mostly fund the subfields they’ve heard of, philanthropist-funded AI will mostly target topics the people running the AI have heard are important. Much like physicists themselves adopting the technology, there will be uneven progress from subfield to subfield, inch by socially-determined inch.

In a hard-to-quantify area like progress in science, that’s all you can hope for. I suspect Kaplan got a bit of a distorted picture of how progress and merit work in theoretical physics. He studied with Nima Arkani-Hamed, who is undeniably exceptionally brilliant but also undeniably exceptionally charismatic. It must feel to a student of Nima’s that academia simply hires the best people, that it does whatever it takes to accomplish the obviously best research. But the best research is not obvious.

I think some of these people imagine a more direct replacement process, not arranged by topic and tastes, but by goals. They picture AI sweeping in and doing what theoretical physics was always “meant to do”: solve quantum gravity, and proceed to shower us with teleporters and antigravity machines. I don’t think there’s any reason to expect that to happen. If you just asked a machine to come up with the most useful model of the universe for a near-term goal, then in all likelihood it wouldn’t consider theoretical high-energy physics at all. If you see your AI as a tool to navigate between utopia and dystopia, theoretical physics might matter at some point: when your AI has devoured the inner solar system, is about to spread beyond the few light-minutes when it can signal itself in real-time, and has to commit to a strategy. But as long as the inner solar system remains un-devoured, I don’t think you’ll see an obviously successful theory of fundamental physics.

Academia Tracks Priority, Not Provenance

A recent Correspondence piece in Nature Machine Intelligence points at an issue with using LLMs to write journal articles. LLMs are trained on enormous amounts of scholarly output, but the result is quite opaque: it is usually impossible to tell which sources influence a specific LLM-written text. That means that when a scholar uses an LLM, they may get a result that depends on another scholar’s work, without realizing it or documenting it. The ideas’ provenance gets lost, and the piece argues this is damaging, depriving scholars of credit and setting back progress.

It’s a good point. Provenance matters. If we want to prioritize funding for scholars whose ideas have the most impact, we need a way to track where ideas arise.

However, current publishing norms make essentially no effort to do this. Academic citations are not used to track provenance, and they are not typically thought of as tracking provenance. Academic citations track priority.

Priority is a central value in scholarship, with a long history. We give special respect to the first person to come up with an idea, make an observation, or do a calculation, and more specifically, the first person to formally publish it. We do this even if the person’s influence was limited, and even if the idea was rediscovered independently later on. In an academic context, being first matters.

In a paper, one is thus expected to cite the sources that have priority, that came up with an idea first. Someone who fails to do so will get citation request emails, and reviewers may request revisions to the paper to add in those missing citations.

One may also cite papers that were helpful, even if they didn’t come first. Tracking provenance in this way can be nice, a way to give direct credit to those who helped and point people to useful resources. But it isn’t mandatory in the same way. If you leave out a secondary source and your paper doesn’t use anything original to that source (like new notation), you’re much less likely to get citation request emails, or revision requests from reviewers. Provenance is just much lower priority.

In practice, academics track provenance in much less formal ways. Before citations, a paper will typically have an Acknowledgements section, where the authors thank those who made the paper possible. This includes formal thanks to funding agencies, but also informal thanks for “helpful discussions” that don’t meet the threshold of authorship.

If we cared about tracking provenance, those acknowledgements would be crucial information, an account of whose ideas directly influenced the ideas in the paper. But they’re not treated that way. No-one lists the number of times they’ve been thanked for helpful discussions on their CV, or in a grant application, no-one considers these discussions for hiring or promotion. You can’t look them up on an academic profile or easily graph them in a metascience paper. Unlike citations, unlike priority, there is essentially no attempt to measure these tracks of provenance in any organized way.

Instead, provenance is often the realm of historians or history-minded scholars, writing long after the fact. For academics, the fact that Yang and Mills published their theory first is enough, we call it Yang-Mills theory. For those studying the history, the story is murkier: it looks like Pauli came up with the idea first, and did most of the key calculations, but didn’t publish when it looked to him like the theory couldn’t describe the real world. What’s more, there is evidence suggesting that Yang knew about Pauli’s result, that he had read a letter from him on the topic, that the idea’s provenance goes back to Pauli. But Yang published, Pauli didn’t. And in the way academia has worked over the last 75 years, that claim of priority is what actually mattered.

Should we try to track provenance? Maybe. Maybe the emerging ubiquitousness of LLMs should be a wakeup call, a demand to improve our tracking of ideas, both in artificial and human neural networks. Maybe we need to demand interpretability from our research tools, to insist that we can track every conclusion back to its evidence for every method we employ, to set a civilizational technological priority on the accurate valuation of information.

What we shouldn’t do, though, is pretend that we just need to go back to what we were doing before.

Requests for an Ethnography of Cheating

What is AI doing to higher education? And what, if anything, should be done about it?

Chad Orzel at Counting Atoms had a post on this recently, tying the question to a broader point. There is a fundamental tension in universities, between actual teaching and learning and credentials. A student who just wants the piece of paper at the end has no reason not to cheat if they can get away with it, so the easier it becomes to get away with cheating (say, by using AI), the less meaningful the credential gets. Meanwhile, professors who want students to actually learn something are reduced to trying to “trick” these goal-oriented students into accidentally doing something that makes them fall in love with a subject, while being required to police the credential side of things.

Social science, as Orzel admits and emphasizes, is hard. Any broad-strokes picture like this breaks down into details, and while Orzel talks through some of those details he and I are of course not social scientists.

Because of that, I’m not going to propose my own “theory” here. Instead, think of this post as a request.

I want to read an ethnography of cheating. Like other ethnographies, it should involve someone spending time in the culture in question (here, cheating students), talking to the people involved, and getting a feeling for what they believe and value. Ideally, it would be augmented with an attempt at quantitative data, like surveys, that estimate how representative the picture is.

I suspect that cheating students aren’t just trying to get a credential. Part of why is that I remember teaching pre-meds. In the US, students don’t directly study medicine as a Bachelor’s degree. Instead, they study other subjects as pre-medical students (“pre-meds”), and then apply to Medical School, which grants a degree on the same level as a PhD. As part of their application, they include a standardized test called the MCAT, which checks that they have the basic level of math and science that the medical schools expect.

A pre-med in a physics class, then, has good reason to want to learn: the better they know their physics, the better they will do on the MCAT. If cheating was mostly about just trying to get a credential, pre-meds wouldn’t cheat.

I’m pretty sure they do cheat, though. I didn’t catch any cheaters back when I taught, but there were a lot of students who tried to push the rules, pre-meds and not.

Instead, I think there are a few other motivations involved. And in an ethnography of cheating, I’d love to see some attempt to estimate how prevalent they are:

  1. Temptation: Maybe students know that they shouldn’t cheat, in the same way they know they should go to the gym. They want to understand the material and learn in the same way people who exercise have physical goals. But the mind, and flesh, are weak. You have a rough week, you feel like you can’t handle the work right now. So you compensate. Some of the motivation here is still due to credentials: a student who shrugs and accepts that their breakup will result in failing a course is a student who might have to pay for an extra year of ultra-expensive US university education to get that credential. But I suspect there is a more fundamental motivation here, related to ego and easy self-deception. If you do the assignment, even if you cheat for part of it, you get to feel like you did it, while if you just turn in a blank page you have to accept the failure.
  2. Skepticism: Education isn’t worth much if it doesn’t actually work. Students may be skeptical that the things that professors are asking them to do actually help them learn what they want to learn, or that the things the professors want them to learn are actually the course’s most valuable content. A student who uses ChatGPT to write an essay might believe that they will never have to write something without ChatGPT in life, so why not use it now? Sometimes professors simply aren’t explicit about what an exercise is actually meant to teach (there have been a huge number of blog posts explaining that writing is meant to teach you to think, not to write), and sometimes professors are genuinely pretty bad at teaching, since there is little done to retain the good ones in most places. A student in this situation still has to be optimistic about some aspect of the education, at some time. But they may be disillusioned, or just interested in something very different.
  3. Internalized Expectations: Do employers actually care if you get a bad grade? Does it matter? By the time a student is in college, they’ve been spending half their waking hours in a school environment for over a decade. Maybe the need to get good grades is so thoroughly drilled in that the actual incentives don’t matter. If you think of yourself as the kind of person who doesn’t fail courses, and you start failing, what do you do?
  4. External Non-Credential Expectations: Don’t worry about the employers, worry about the parents. Some college students have the kind of parents who keep checking in on how they’re doing, who want to see evidence and progress the same way they did when they were kids. Any feedback, no matter how much it’s intended to teach, not to judge, might get twisted into a judgement. Better to avoid that judgement, right?
  5. Credentials, but for the Government, not Employers: Of course, for some students, failing really does wreck their life. If you’re on the kind of student visa that requires you maintain grades a certain level, you’ve got a much stronger incentive to cheat, imposed for much less reason.

If you’re aware of a good ethnography of cheating, let me know! And if you’re a social scientist, consider studying this!