Tag Archives: amplitudes

Amplitudes 2022 Retrospective

I’m back from Amplitudes 2022 with more time to write, and (besides the several papers I’m working on) that means writing about the conference! Casual readers be warned, there’s no way around this being a technical post, I don’t have the space to explain everything!

I mostly said all I wanted about the way the conference was set up in last week’s post, but one thing I didn’t say much about was the conference dinner. Most conference dinners are the same aside from the occasional cool location or haggis speech. This one did have a cool location, and a cool performance by a blind pianist, but the thing I really wanted to comment on was the setup. Typically, the conference dinner at Amplitudes is a sit-down affair: people sit at tables in one big room, maybe getting up occasionally to pick up food, and eventually someone gives an after-dinner speech. This time the tables were standing tables, spread across several rooms. This was a bit tiring on a hot day, but it did have the advantage that it naturally mixed people around. Rather than mostly talking to “your table”, you’d wander, ending up at a new table every time you picked up new food or drinks. It was a good way to meet new people, a surprising number of which in my case apparently read this blog. It did make it harder to do an after-dinner speech, so instead Lance gave an after-conference speech, complete with the now-well-established running joke where Greta Thunberg tries to get us to fly less.

(In another semi-running joke, the organizers tried to figure out who had attended the most of the yearly Amplitudes conferences over the years. Weirdly, no-one has attended all twelve.)

In terms of the content, and things that stood out:

Nima is getting close to publishing his newest ‘hedron, the surfacehedron, and correspondingly was able to give a lot more technical detail about it. (For his first and most famous amplituhedron, see here.) He still didn’t have enough time to explain why he has to use category theory to do it, but at least he was concrete enough that it was reasonably clear where the category theory was showing up. (I wasn’t there for his eight-hour lecture at the school the week before, maybe the students who stuck around until 2am learned some category theory there.) Just from listening in on side discussions, I got the impression that some of the ideas here actually may have near-term applications to computing Feynman diagrams: this hasn’t been a feature of previous ‘hedra and it’s an encouraging development.

Alex Edison talked about progress towards this blog’s namesake problem, the question of whether N=8 supergravity diverges at seven loops. Currently they’re working at six loops on the N=4 super Yang-Mills side, not yet in a form it can be “double-copied” to supergravity. The tools they’re using are increasingly sophisticated, including various slick tricks from algebraic geometry. They are looking to the future: if they’re hoping their methods will reach seven loops, the same methods have to make six loops a breeze.

Xi Yin approached a puzzle with methods from String Field Theory, prompting the heretical-for-us title “on-shell bad, off-shell good”. A colleague reminded me of a local tradition for dealing with heretics.

While Nima was talking about a new ‘hedron, other talks focused on the original amplituhedron. Paul Heslop found that the amplituhedron is not literally a positive geometry, despite slogans to the contrary, but what it is is nonetheless an interesting generalization of the concept. Livia Ferro has made more progress on her group’s momentum amplituhedron: previously only valid at tree level, they now have a picture that can accomodate loops. I wasn’t sure this would be possible, there are a lot of things that work at tree level and not for loops, so I’m quite encouraged that this one made the leap successfully.

Sebastian Mizera, Andrew McLeod, and Hofie Hannesdottir all had talks that could be roughly summarized as “deep principles made surprisingly useful”. Each took topics that were explored in the 60’s and translated them into concrete techniques that could be applied to modern problems. There were surprisingly few talks on the completely concrete end, on direct applications to collider physics. I think Simone Zoia’s was the only one to actually feature collider data with error bars, which might explain why I singled him out to ask about those error bars later.

Likewise, Matthias Wilhelm’s talk was the only one on functions beyond polylogarithms, the elliptic functions I’ve also worked on recently. I wonder if the under-representation of some of these topics is due to the existence of independent conferences: in a year when in-person conferences are packed in after being postponed across the pandemic, when there are already dedicated conferences for elliptics and practical collider calculations, maybe people are just a bit too tired to go to Amplitudes as well.

Talks on gravitational waves seem to have stabilized at roughly a day’s worth, which seems reasonable. While the subfield’s capabilities continue to be impressive, it’s also interesting how often new conceptual challenges appear. It seems like every time a challenge to their results or methods is resolved, a new one shows up. I don’t know whether the field will ever get to a stage of “business as usual”, or whether it will be novel qualitative questions “all the way up”.

I haven’t said much about the variety of talks bounding EFTs and investigating their structure, though this continues to be an important topic. And I haven’t mentioned Lance Dixon’s talk on antipodal duality, largely because I’m planning a post on it later: Quanta Magazine had a good article on it, but there are some aspects even Quanta struggled to cover, and I think I might have a good way to do it.
At Amplitudes 2022 in Prague

It’s that time of year again! I’m at the big yearly conference of my subfield, Amplitudes, this year in Prague.

The conference poster included a picture of Prague’s famous clock, which is admittedly cool. But I think this computer-generated anachronism from Matt Schwartz’s machine learning talk is much more fun.

Amplitudes has grown, and keeps growing. The last time we met in person, there were 175 of us. This year, many people are skipping: some avoiding travel due to COVID, others just exhausted from a summer filled with long-postponed conferences. Nonetheless, we have more people here than then: 222 registered participants!

The large number of people means a large number of talks. Almost all were quite short, 25+5 minutes. Some speakers took advantage of the short length to deliver very accessible talks. Others seemed to think of the time limit as an excuse to cut short the introduction and dive right into technical details. We had just a few 40+5 minute talks, each a review from an adjacent field.

It’s been fun seeing people in person again. I think half of my conversations started with “It’s been a long time!” It’s easy for motivation to wane when you don’t have regular contact with the wider field, getting enthusiastic about shared goals and brainstorming big questions.

I’ll probably give a longer retrospective later: the packed schedule means I don’t have much time to write! But I can say that I’ve largely enjoyed this, the organizers were organized and the presenters presented and things felt a bit more like they ought to in the world.

The Conference Dilemma: Freshness vs. Breadth

Back in 2017, I noticed something that should have struck me as a little odd. My sub-field has a big yearly conference, called Amplitudes, that brings in everyone who works on our kind of research. Amplitudes 2017 was fun, but not “fresh”: most people talked about work they had already published. A smaller conference I went to that year, called QCD Meets Gravity, was much “fresher”: a lot of discussion of work in progress and work “hot off the presses”.

At the time, I chalked the difference up to timing: it was a few months later, and people happened to have projects that matured around then. But I realized recently there’s another reason, one why you would expect bigger conferences to have less fresh content.

See, I’ve recently been on the other “side of the curtain”: I was an organizer for Amplitudes last year. And I noticed one big obstacle to having fresh content: the timeframe.

The bigger a conference is, the longer in advance you need to invite speakers. It’s a bigger task to organize everyone, to make sure travel and hotels and raw availability works, that everyone has time to prepare their talks and you have a nice full (but not too full) schedule. So when we started asking people, we didn’t know what the “freshest” work was going to be. We had recommendations from our scientific committee (a group of experts in the subfield whose job is to suggest speakers), but in practice the goal is more one of breadth than freshness: we needed to make sure that everybody in our community was represented.

A smaller conference can get around this. It can be organized a bit later, so the organizers have more information about new developments. It covers a smaller area, so the organizers have more information about new hot topics and unpublished results. And it typically invites most of the sub-community anyway, so you’re guaranteed to cover the hot new stuff just by raw completeness.

This doesn’t mean small conferences are “just better” or anything like that. Breadth is genuinely useful: a big conference covering a whole subfield is great for bringing a community together, getting everyone on a shared page and expanding their horizons. There’s a real tradeoff between those goals and getting a conference with the latest progress. It’s not a fixed tradeoff, we can improve both goals at once (I think at Amplitudes we as organizers could have been better at highlighting unpublished work), but we still have to make choices of what to emphasize.

Carving Out the Possible

If you imagine a particle physicist, you probably picture someone spending their whole day dreaming up new particles. They figure out how to test those particles in some big particle collider, and for a lucky few their particle gets discovered and they get a Nobel prize.

Occasionally, a wiseguy asks if we can’t just cut out the middleman. Instead of dreaming up particles to test, why don’t we just write down every possible particle and test for all of them? It would save the Nobel committee a lot of money at least!

It turns out, you can sort of do this, through something called Effective Field Theory. An Effective Field Theory is a type of particle physics theory that isn’t quite true: instead, it’s “effectively” true, meaning true as long as you don’t push it too far. If you test it at low energies and don’t “zoom in” too much then it’s fine. Crank up your collider energy high enough, though, and you expect the theory to “break down”, revealing new particles. An Effective Field Theory lets you “hide” unknown particles inside new interactions between the particles we already know.

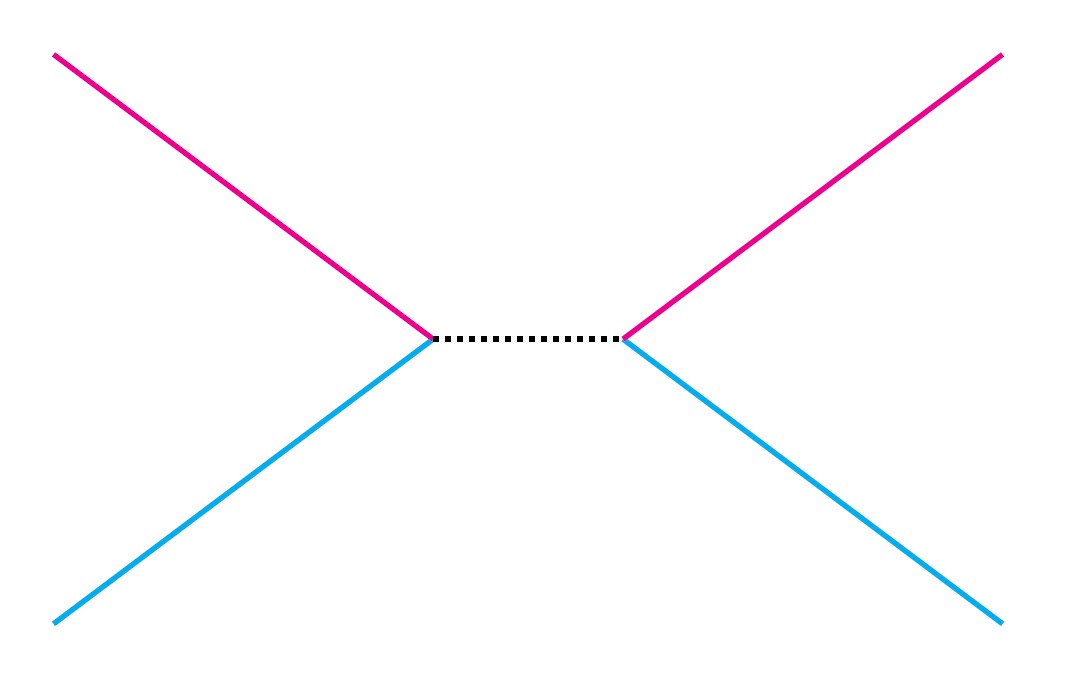
To help you picture how this works, imagine that the pink and blue lines here represent familiar particles like electrons and quarks, while the dotted line is a new particle somebody dreamed up. (The picture is called a Feynman diagram, if you don’t know what that is check out this post.)

In an Effective Field Theory, we “zoom out”, until the diagram looks like this:

Now we’ve “hidden” the new particle. Instead, we have a new type of interaction between the particles we already know.

So instead of writing down every possible new particle we can imagine, we only have to write down every possible interaction between the particles we already know.

That’s not as hard as it sounds. In part, that’s because not every interaction actually makes sense. Some of the things you could write down break some important rules. They might screw up cause and effect, letting something happen before its cause instead of after. They might screw up probability, giving you a formula for the chance something happens that gives a number greater than 100%.

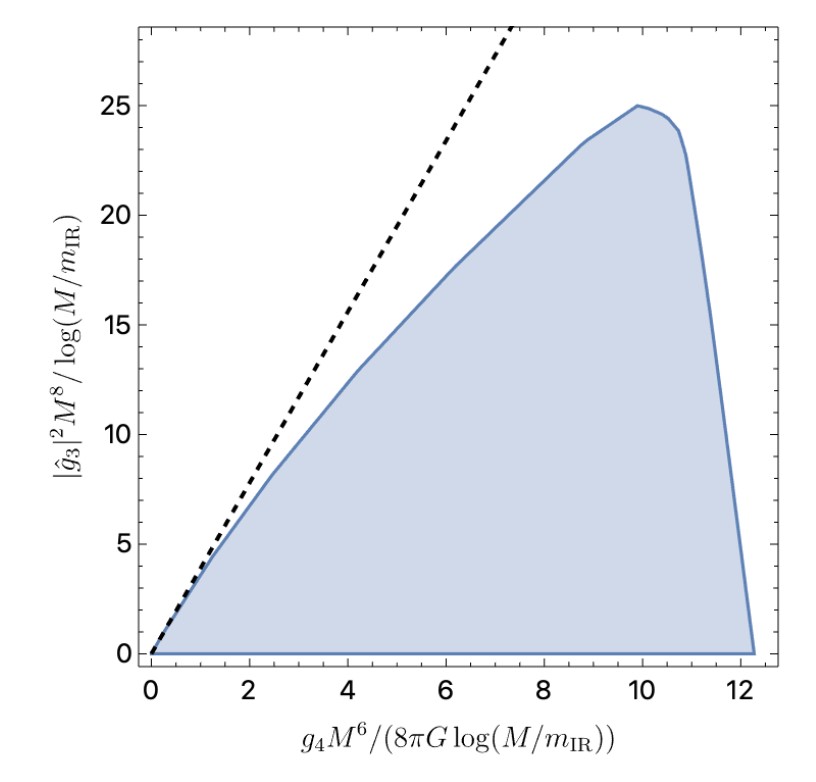
Using these rules you can play a kind of game. You start out with a space representing all of the interactions you can imagine. You begin chipping at it, carving away parts that don’t obey the rules, and you see what shape is left over. You end up with plots that look a bit like carving a ham.

People in my subfield are getting good at this kind of game. It isn’t quite our standard fare: usually, we come up with tricks to make calculations with specific theories easier. Instead, many groups are starting to look at these general, effective theories. We’ve made friends with groups in related fields, building new collaborations. There still isn’t one clear best way to do this carving, so each group manages to find a way to chip a little farther. Out of the block of every theory we could imagine, we’re carving out a space of theories that make sense, theories that could conceivably be right. Theories that are worth testing.

Of Snowmass and SAGEX

arXiv-watchers might have noticed an avalanche of papers with the word Snowmass in the title. (I contributed to one of them.)

Snowmass is a place, an area in Colorado known for its skiing. It’s also an event in that place, the Snowmass Community Planning Exercise for the American Physical Society’s Division of Particles and Fields. In plain terms, it’s what happens when particle physicists from across the US get together in a ski resort to plan their future.

Usually someone like me wouldn’t be involved in that. (And not because it’s a ski resort.) In the past, these meetings focused on plans for new colliders and detectors. They got contributions from experimentalists, and a few theorists heavily focused on their work, but not the more “formal” theorists beyond.

This Snowmass is different. It’s different because of Corona, which changed it from a big meeting in a resort to a spread-out series of meetings and online activities. It’s also different because they invited theorists to contribute, and not just those interested in particle colliders. The theorists involved study everything from black holes and quantum gravity to supersymmetry and the mathematics of quantum field theory. Groups focused on each topic submit “white papers” summarizing the state of their area. These white papers in turn get organized and summarized into a few subfields, which in turn contribute to the planning exercise. No-one I’ve talked to is entirely clear on how this works, how much the white papers will actually be taken into account or by whom. But it seems like a good chance to influence US funding agencies, like the Department of Energy, and see if we can get them to prioritize our type of research.

Europe has something similar to Snowmass, called the European Strategy for Particle Physics. It also has smaller-scale groups, with their own purposes, goals, and funding sources. One such group is called SAGEX: Scattering Amplitudes: from Geometry to EXperiment. SAGEX is an Innovative Training Network, an organization funded by the EU to train young researchers, in this case in scattering amplitudes. Its fifteen students are finishing their PhDs and ready to take the field by storm. Along the way, they spent a little time in industry internships (mostly at Maple and Mathematica), and quite a bit of time working on outreach.

They have now summed up that outreach work in an online exhibition. I’ve had fun exploring it over the last couple days. They’ve got a lot of good content there, from basic explanations of relativity and quantum mechanics, to detailed games involving Feynman diagrams and associahedra, to a section that uses solitons as a gentle introduction to integrability. If you’re in the target audience, you should check it out!

Geometry and Geometry

Last week, I gave the opening lectures for a course on scattering amplitudes, the things we compute to find probabilities in particle physics. After the first class, one of the students asked me if two different descriptions of these amplitudes, one called CHY and the other called the amplituhedron, were related. There does happen to be a connection, but it’s a bit subtle and indirect, not the sort of thing the student would have been thinking of. Why then, did he think they might be related? Well, he explained, both descriptions are geometric.

If you’ve been following this blog for a while, you’ve seen me talk about misunderstandings. There are a lot of subtle ways a smart student can misunderstand something, ways that can be hard for a teacher to recognize. The right question, or the right explanation, can reveal what’s going on. Here, I think the problem was that there are multiple meanings of geometry.

One of the descriptions the student asked about, CHY, is related to string theory. It describes scattering particles in terms of the path of a length of string through space and time. That path draws out a surface called a world-sheet, showing all the places the string touches on its journey. And that picture, of a wiggly surface drawn in space and time, looks like what most people think of as geometry: a “shape” in a pretty normal sense, which here describes the physics of scattering particles.

The other description, the amplituhedron, also uses geometric objects to describe scattering particles. But the “geometric objects” here are much more abstract. A few of them are familiar: straight lines, the area between them forming shapes on a plane. Most of them, though are generalizations of this: instead of lines on a plane, they have higher dimensional planes in higher dimensional spaces. These too get described as geometry, even though they aren’t the “everyday” geometry you might be familiar with. Instead, they’re a “natural generalization”, something that, once you know the math, is close enough to that “everyday” geometry that it deserves the same name.

This week, two papers presented a totally different kind of geometric description of particle physics. In those papers, “geometric” has to do with differential geometry, the mathematics behind Einstein’s theory of general relativity. The descriptions are geometric because they use the same kinds of building-blocks of that theory, a metric that bends space and time. Once again, this kind of geometry is a natural generalization of the everyday notion, but now in once again a different way.

All of these notions of geometry do have some things in common, of course. Maybe you could even write down a definition of “geometry” that includes all of them. But they’re different enough that if I tell you that two descriptions are “geometric”, it doesn’t tell you all that much. It definitely doesn’t tell you the two descriptions are related.

It’s a reasonable misunderstanding, though. It comes from a place where, used to “everyday” geometry, you expect two “geometric descriptions” of something to be similar: shapes moving in everyday space, things you can directly compare. Instead, a geometric description can be many sorts of shape, in many sorts of spaces, emphasizing many sorts of properties. “Geometry” is just a really broad term.

Classicality Has Consequences

Last week, I mentioned some interesting new results in my corner of physics. I’ve now finally read the two papers and watched the recorded talk, so I can satisfy my frustrated commenters.

Quantum mechanics is a very cool topic and I am much less qualified than you would expect to talk about it. I use quantum field theory, which is based on quantum mechanics, so in some sense I use quantum mechanics every day. However, most of the “cool” implications of quantum mechanics don’t come up in my work. All the debates about whether measurement “collapses the wavefunction” are irrelevant when the particles you measure get absorbed in a particle detector, never to be seen again. And while there are deep questions about how a classical world emerges from quantum probabilities, they don’t matter so much when all you do is calculate those probabilities.

They’ve started to matter, though. That’s because quantum field theorists like me have recently started working on a very different kind of problem: trying to predict the output of gravitational wave telescopes like LIGO. It turns out you can do almost the same kind of calculation we’re used to: pretend two black holes or neutron stars are sub-atomic particles, and see what happens when they collide. This trick has grown into a sub-field in its own right, one I’ve dabbled in a bit myself. And it’s gotten my kind of physicists to pay more attention to the boundary between classical and quantum physics.

The thing is, the waves that LIGO sees really are classical. Any quantum gravity effects there are tiny, undetectably tiny. And while this doesn’t have the implications an expert might expect (we still need loop diagrams), it does mean that we need to take our calculations to a classical limit.

Figuring out how to do this has been surprisingly delicate, and full of unexpected insight. A recent example involves two papers, one by Andrea Cristofoli, Riccardo Gonzo, Nathan Moynihan, Donal O’Connell, Alasdair Ross, Matteo Sergola, and Chris White, and one by Ruth Britto, Riccardo Gonzo, and Guy Jehu. At first I thought these were two groups happening on the same idea, but then I noticed Riccardo Gonzo on both lists, and realized the papers were covering different aspects of a shared story. There is another group who happened upon the same story: Paolo Di Vecchia, Carlo Heissenberg, Rodolfo Russo and Gabriele Veneziano. They haven’t published yet, so I’m basing this on the Gonzo et al papers.

The key question each group asked was, what does it take for gravitational waves to be classical? One way to ask the question is to pick something you can observe, like the strength of the field, and calculate its uncertainty. Classical physics is deterministic: if you know the initial conditions exactly, you know the final conditions exactly. Quantum physics is not. What should happen is that if you calculate a quantum uncertainty and then take the classical limit, that uncertainty should vanish: the observation should become certain.

Another way to ask is to think about the wave as made up of gravitons, particles of gravity. Then you can ask how many gravitons are in the wave, and how they are distributed. It turns out that you expect them to be in a coherent state, like a laser, one with a very specific distribution called a Poisson distribution: a distribution in some sense right at the border between classical and quantum physics.

The results of both types of questions were as expected: the gravitational waves are indeed classical. To make this work, though, the quantum field theory calculation needs to have some surprising properties.

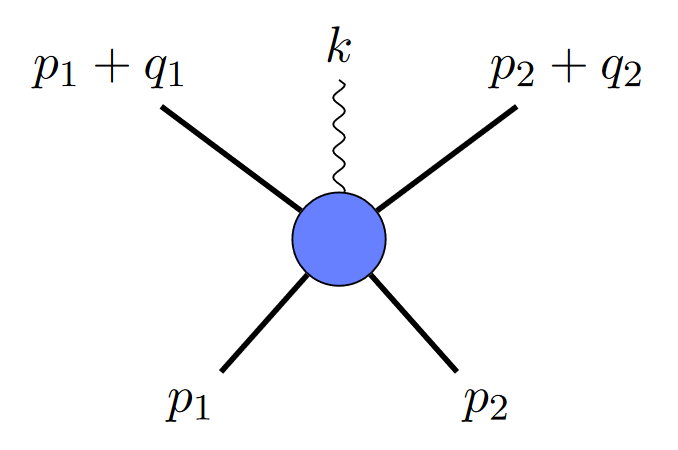
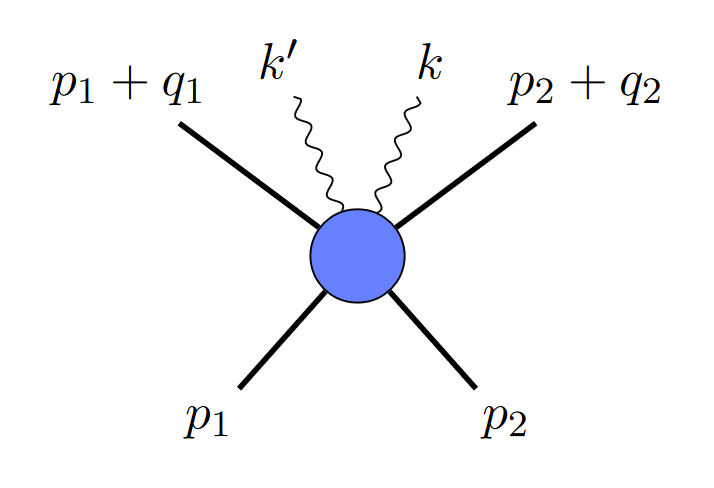
If two black holes collide and emit a gravitational wave, you could depict it like this:

All pictures from arXiv:2112.07556

where the straight lines are black holes, and the squiggly line is a graviton. But since gravitational waves are made up of multiple gravitons, you might ask, why not depict it with two gravitons, like this?

It turns out that diagrams like that are a problem: they mean your two gravitons are correlated, which is not allowed in a Poisson distribution. In the uncertainty picture, they also would give you non-zero uncertainty. Somehow, in the classical limit, diagrams like that need to go away.

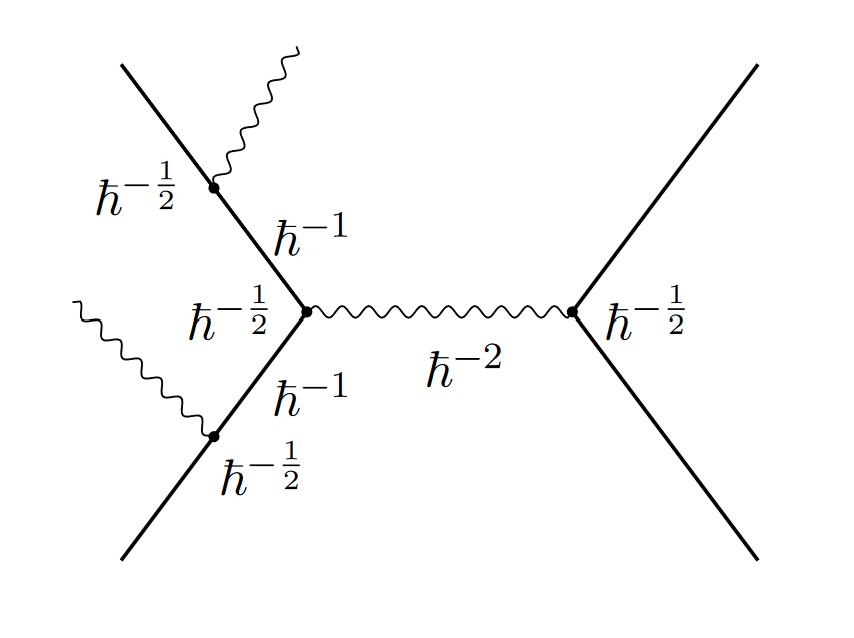
And at first, it didn’t look like they do. You can try to count how many powers of Planck’s constant show up in each diagram. The authors do that, and it certainly doesn’t look like it goes away:

An example from the paper with Planck’s constants sprinkled around

Luckily, these quantum field theory calculations have a knack for surprising us. Calculate each individual diagram, and things look hopeless. But add them all together, and they miraculously cancel. In the classical limit, everything combines to give a classical result.

You can do this same trick for diagrams with more graviton particles, as many as you like, and each time it ought to keep working. You get an infinite set of relationships between different diagrams, relationships that have to hold to get sensible classical physics. From thinking about how the quantum and classical are related, you’ve learned something about calculations in quantum field theory.

That’s why these papers caught my eye. A chunk of my sub-field is needing to learn more and more about the relationship between quantum and classical physics, and it may have implications for the rest of us too. In the future, I might get a bit more qualified to talk about some of the very cool implications of quantum mechanics.

Science, Gifts Enough for Lifetimes

Merry Newtonmas, Everyone!

In past years, I’ve compared science to a gift: the ideal gift for the puzzle-fan, one that keeps giving new puzzles. I think people might not appreciate the scale of that gift, though.

Bigger than all the creative commons Wikipedia images

Maybe you’ve heard the old joke that studying for a PhD means learning more and more about less and less until you know absolutely everything about nothing at all. This joke is overstating things: even when you’ve specialized down to nothing at all, you still won’t know everything.

If you read the history of science, it might feel like there are only a few important things going on at a time. You notice the simultaneous discoveries, like calculus from Newton and Liebniz and natural selection from Darwin and Wallace. You can get the impression that everyone was working on a few things, the things that would make it into the textbooks. In fact, though, there was always a lot to research, always many interesting things going on at once. As a scientist, you can’t escape this. Even if you focus on your own little area, on a few topics you care about, even in a small field, there will always be more going on than you can keep up with.

This is especially clear around the holiday season. As everyone tries to get results out before leaving on vacation, there is a tidal wave of new content. I have five papers open on my laptop right now (after closing four or so), and some recorded talks I keep meaning to watch. Two of the papers are the kind of simultaneous discovery I mentioned: two different groups noticing that what might seem like an obvious fact – that in classical physics, unlike in quantum, one can have zero uncertainty – has unexpected implications for our kind of calculations. (A third group got there too, but hasn’t published yet.) It’s a link I would never have expected, and with three groups coming at it independently you’d think it would be the only thing to pay attention to: but even in the same sub-sub-sub-field, there are other things going on that are just as cool! It’s wild, and it’s not some special quirk of my area: that’s science, for all us scientists. No matter how much you expect it to give you, you’ll get more, lifetimes and lifetimes worth. That’s a Newtonmas gift to satisfy anyone.

Calculations of the Past

Last week was a birthday conference for one of the pioneers of my sub-field, Ettore Remiddi. I wasn’t there, but someone who was pointed me to some of the slides, including a talk by Stefano Laporta. For those of you who didn’t see my post a few weeks back, Laporta was one of Remiddi’s students, who developed one of the most important methods in our field and then vanished, spending ten years on an amazingly detailed calculation. Laporta’s talk covers more of the story, about what it was like to do precision calculations in that era.

“That era”, the 90’s through 2000’s, witnessed an enormous speedup in computers, and a corresponding speedup in what was possible. Laporta worked with Remiddi on the three-loop electron anomalous magnetic moment, something Remiddi had been working on since 1969. When Laporta joined in 1989, twenty-one of the seventy-two diagrams needed had still not been computed. They would polish them off over the next seven years, before Laporta dove in to four loops. Twenty years later, he had that four-loop result to over a thousand digits.

One fascinating part of the talk is seeing how the computational techniques change over time, as language replaces language and computer clusters get involved. As a student, Laporta learns a lesson we all often need: that to avoid mistakes, we need to do as little by hand as possible, even for something as simple as copying a one-line formula. Looking at his review of others’ calculations, it’s remarkable how many theoretical results had to be dramatically corrected a few years down the line, and how much still might depend on theoretical precision.

Another theme was one of Remiddi suggesting something and Laporta doing something entirely different, and often much more productive. Whether it was using the arithmetic-geometric mean for an elliptic integral instead of Gaussian quadrature, or coming up with his namesake method, Laporta spent a lot of time going his own way, and Remiddi quickly learned to trust him.

There’s a lot more in the slides that’s worth reading, including a mention of one of this year’s Physics Nobelists. The whole thing is an interesting look at what it takes to press precision to the utmost, and dedicate years to getting something right.

In Uppsala for Elliptics 2021

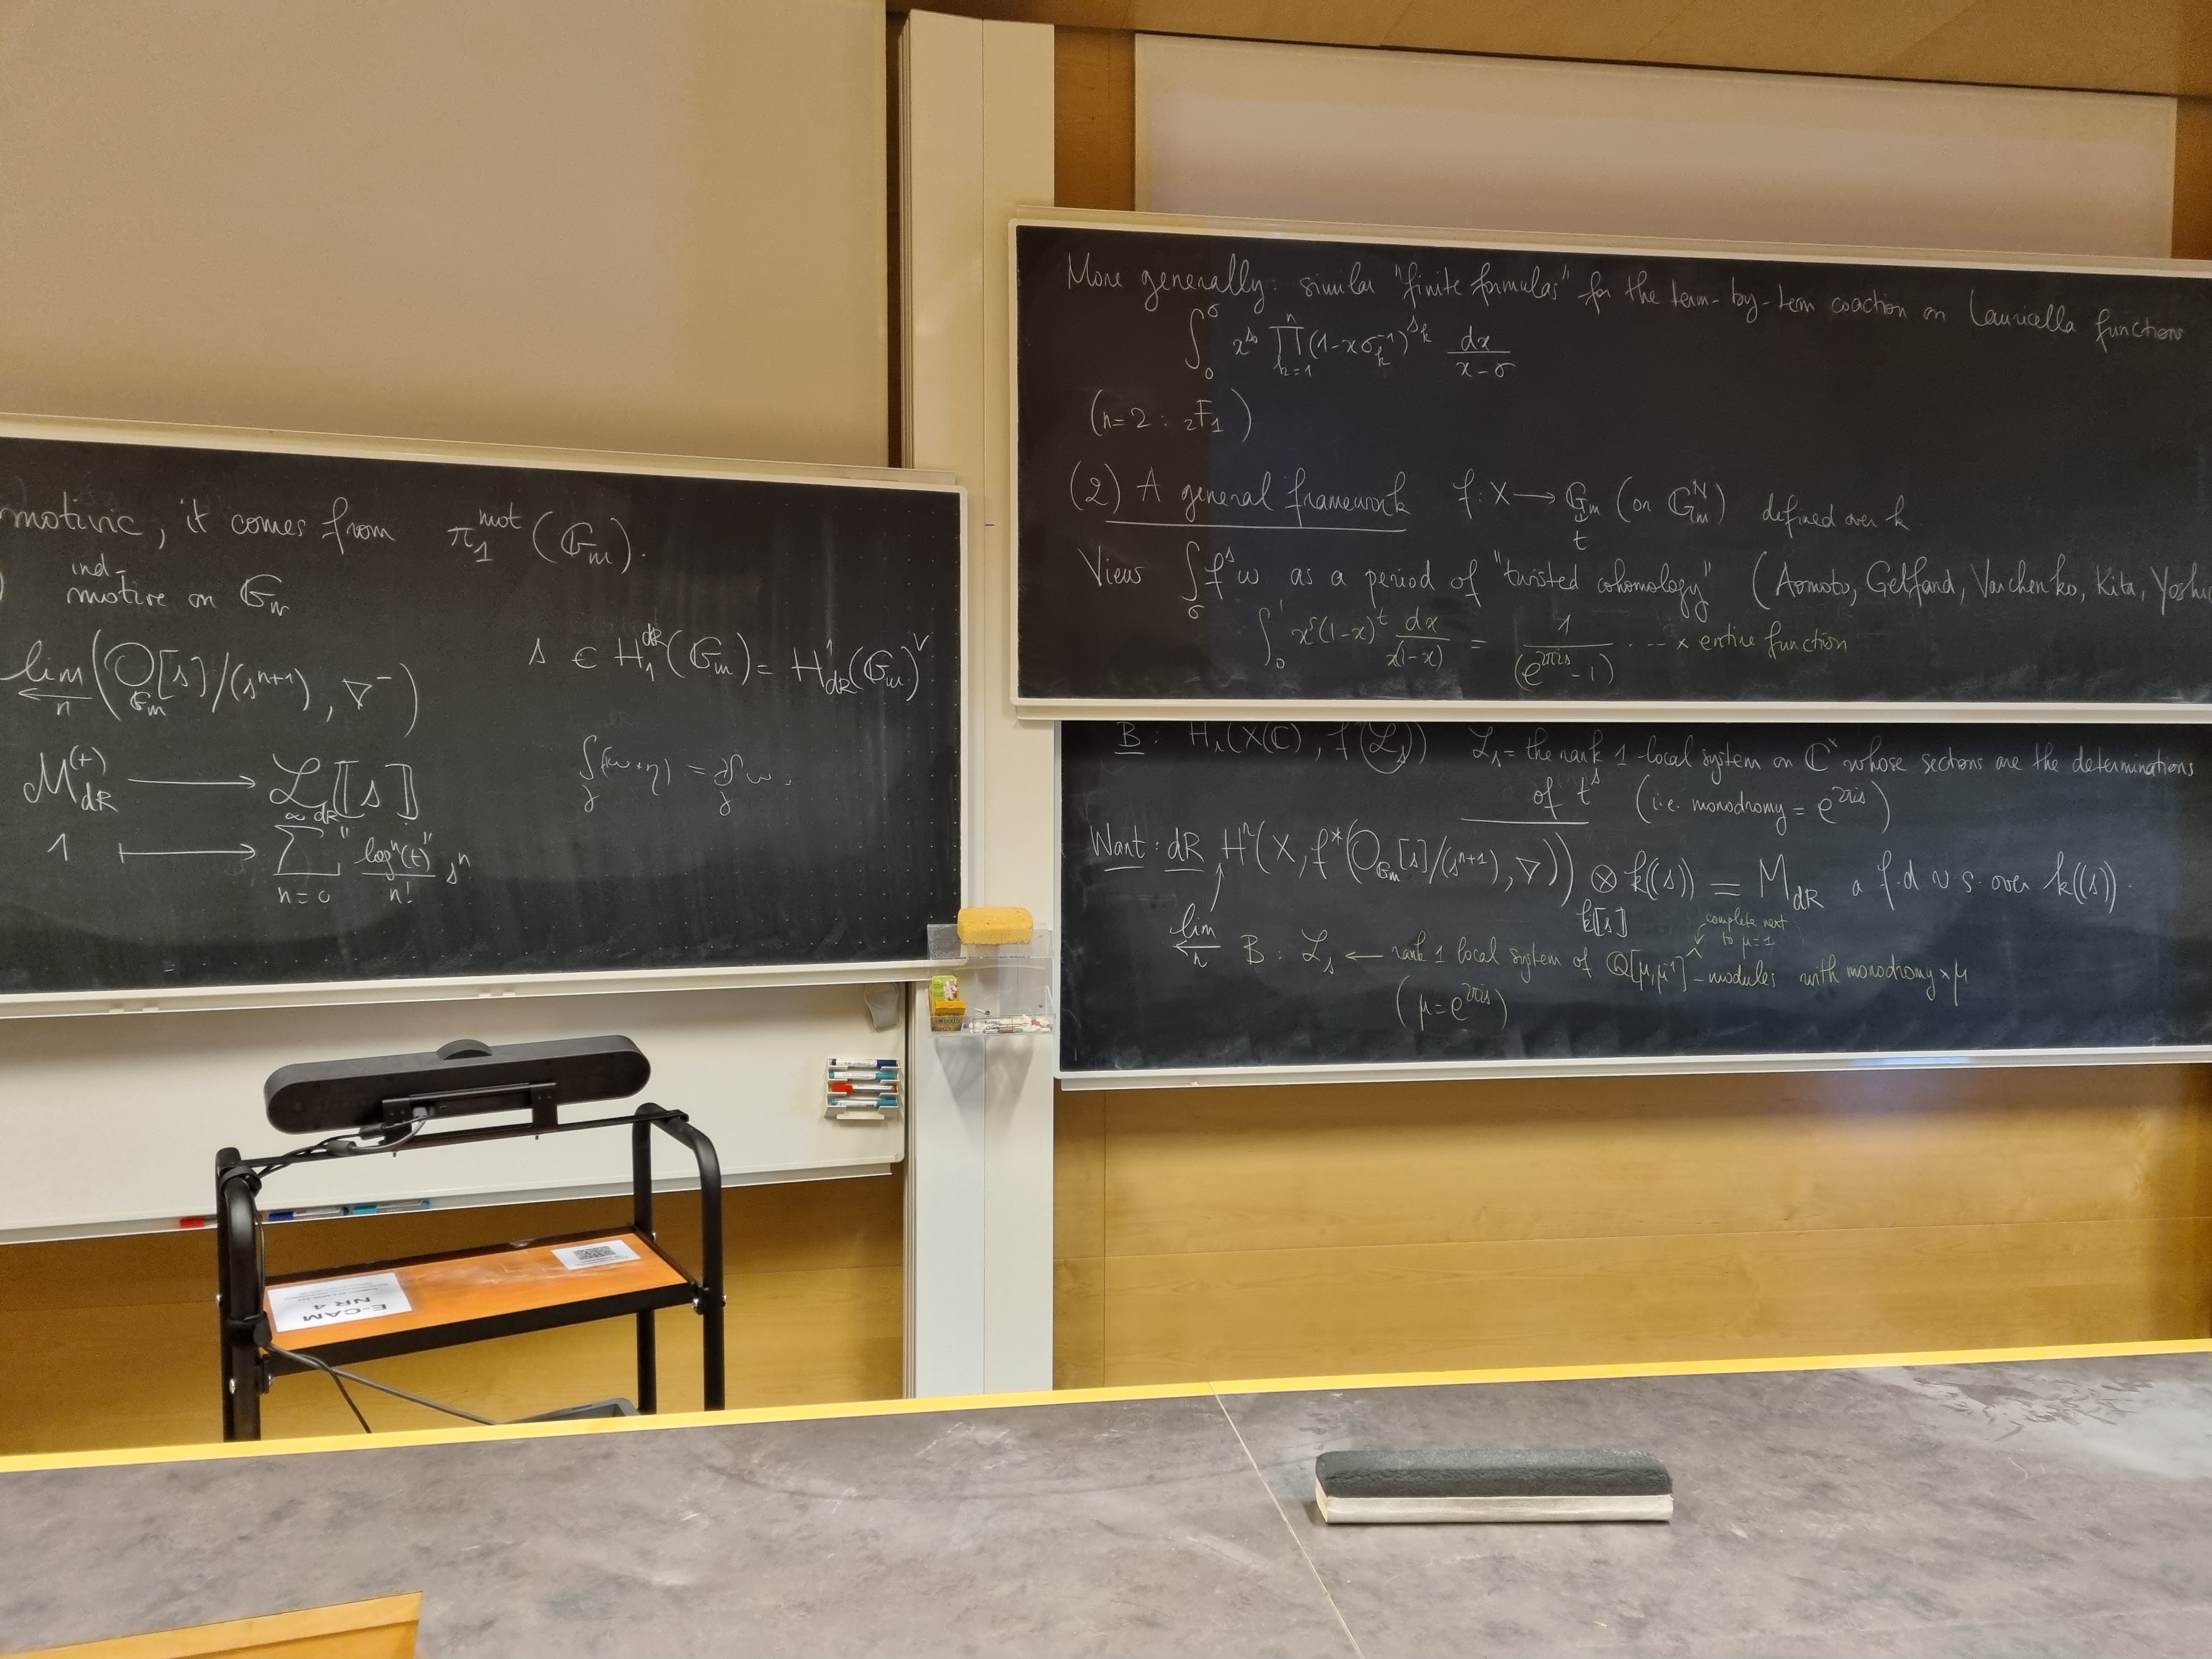
I’m in Uppsala in Sweden this week, at an actual in-person conference.

With actual blackboards!

Elliptics started out as a series of small meetings of physicists trying to understand how to make sense of elliptic integrals in calculations of colliding particles. It grew into a full-fledged yearly conference series. I organized last year, which naturally was an online conference. This year though, the stage was set for Uppsala University to host in person.

I should say mostly in person. It’s a hybrid conference, with some speakers and attendees joining on Zoom. Some couldn’t make it because of travel restrictions, or just wanted to be cautious about COVID. But seemingly just as many had other reasons, like teaching schedules or just long distances, that kept them from coming in person. We’re all wondering if this will become a long-term trend, where the flexibility of hybrid conferences lets people attend no matter their constraints.

The hybrid format worked better than expected, but there were still a few kinks. The audio was particularly tricky, it seemed like each day the organizers needed a new microphone setup to take questions. It’s always a little harder to understand someone on Zoom, especially when you’re sitting in an auditorium rather than focused on your own screen. Still, technological experience should make this work better in future.

Content-wise, the conference began with a “mini-school” of pedagogical talks on particle physics, string theory, and mathematics. I found the mathematical talks by Erik Panzer particularly nice, it’s a topic I still feel quite weak on and he laid everything out in a very clear way. It seemed like a nice touch to include a “school” element in the conference, though I worry it ate too much into the time.

The rest of the content skewed more mathematical, and more string-theoretic, than these conferences have in the past. The mathematical content ranged from intriguing (including an interesting window into what it takes to get high-quality numerics) to intimidatingly obscure (large commutative diagrams, category theory on the first slide). String theory was arguably under-covered in prior years, but it felt over-covered this year. With the particle physics talks focusing on either general properties with perhaps some connections to elliptics, or to N=4 super Yang-Mills, it felt like we were missing the more “practical” talks from past conferences, where someone was computing something concrete in QCD and told us what they needed. Next year is in Mainz, so maybe those talks will reappear.