Category Archives: Amplitudes Methods

Why the Antipode Was Supposed to Be Useless

A few weeks back, Quanta Magazine had an article about a new discovery in my field, called antipodal duality.

Some background: I’m a theoretical physicist, and I work on finding better ways to make predictions in particle physics. Folks in my field make these predictions with formulas called “scattering amplitudes” that encode the probability that particles bounce, or scatter, in particular ways. One trick we’ve found is that these formulas can often be written as “words” in a kind of “alphabet”. If we know the alphabet, we can make our formulas much simpler, or even guess formulas we could never have calculated any other way.

Quanta’s article describes how a few friends of mine (Lance Dixon, Ömer Gürdoğan, Andrew McLeod, and Matthias Wilhelm) noticed a weird pattern in two of these formulas, from two different calculations. If you flip the “words” around, back to front (an operation called the antipode), you go from a formula describing one collision of particles to a formula for totally different particles. Somehow, the two calculations are “dual”: two different-seeming descriptions that secretly mean the same thing.

Quanta quoted me for their article, and I was (pleasantly) baffled. See, the antipode was supposed to be useless. The mathematicians told us it was something the math allows us to do, like you’re allowed to order pineapple on pizza. But just like pineapple on pizza, we couldn’t imagine a situation where we actually wanted to do it.

What Quanta didn’t say was why we thought the antipode was useless. That’s a hard story to tell, one that wouldn’t fit in a piece like that.

It fits here, though. So in the rest of this post, I’d like to explain why flipping around words is such a strange, seemingly useless thing to do. It’s strange because it swaps two things that in physics we thought should be independent: branch cuts and derivatives, or particles and symmetries.

Let’s start with the first things in each pair: branch cuts, and particles.

The first few letters of our “word” tell us something mathematical, and they tell us something physical. Mathematically, they tell us ways that our formula can change suddenly, and discontinuously.

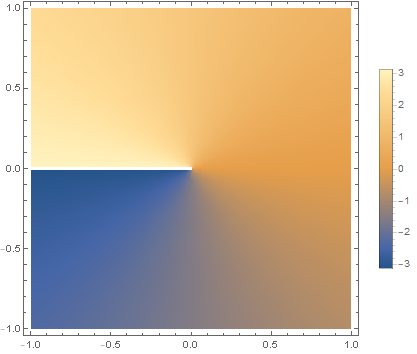
Take a logarithm, the inverse of e^x. You’re probably used to plugging in positive numbers, and getting out something reasonable, that changes in a smooth and regular way: after all, e^x is always positive, right? But in mathematics, you don’t have to just use positive numbers. You can use negative numbers. Even more interestingly, you can use complex numbers. And if you take the logarithm of a complex number, and look at the imaginary part, it looks like this:

Mostly, this complex logarithm still seems to be doing what it’s supposed to, changing in a nice slow way. But there is a weird “cut” in the graph for negative numbers: a sudden jump, from \pi to -\pi. That jump is called a “branch cut”.

As physicists, we usually don’t like our formulas to make sudden changes. A change like this is an infinitely fast jump, and we don’t like infinities much either. But we do have one good use for a formula like this, because sometimes our formulas do change suddenly: when we have enough energy to make a new particle.

Imagine colliding two protons together, like at the LHC. Colliding particles doesn’t just break the protons into pieces: due to Einstein’s famous E=mc^2, it can create new particles as well. But to create a new particle, you need enough energy: mc^2 worth of energy. So as you dial up the energy of your protons, you’ll notice a sudden change: you couldn’t create, say, a Higgs boson, and now you can. Our formulas represent some of those kinds of sudden changes with branch cuts.

So the beginning of our “words” represent branch cuts, and particles. The end represents derivatives and symmetries.

Derivatives come from the land of calculus, a place spooky to those with traumatic math class memories. Derivatives shouldn’t be so spooky though. They’re just ways we measure change. If we have a formula that is smoothly changing as we change some input, we can describe that change with a derivative.

The ending of our “words” tell us what happens when we take a derivative. They tell us which ways our formulas can smoothly change, and what happens when they do.

In doing so, they tell us about something some physicists make sound spooky, called symmetries. Symmetries are changes we can make that don’t really change what’s important. For example, you could imagine lifting up the entire Large Hadron Collider and (carefully!) carrying it across the ocean, from France to the US. We’d expect that, once all the scared scientists return and turn it back on, it would start getting exactly the same results. Physics has “translation symmetry”: you can move, or “translate” an experiment, and the important stuff stays the same.

These symmetries are closely connected to derivatives. If changing something doesn’t change anything important, that should be reflected in our formulas: they shouldn’t change either, so their derivatives should be zero. If instead the symmetry isn’t quite true, if it’s what we call “broken”, then by knowing how it was “broken” we know what the derivative should be.

So branch cuts tell us about particles, derivatives tell us about symmetries. The weird thing about the antipode, the un-physical bizarre thing, is that it swaps them. It makes the particles of one calculation determine the symmetries of another.

(And lest you’ve heard about particles with symmetries, like gluons and SU(3)…this is a different kind of thing. I don’t have enough room to explain why here, but it’s completely unrelated.)

Why the heck does this duality exist?

A commenter on the last post asked me to speculate. I said there that I have no clue, and that’s most of the answer.

If I had to speculate, though, my answer might be disappointing.

Most of the things in physics we call “dualities” have fairly deep physical meanings, linked to twisting spacetime in complicated ways. AdS/CFT isn’t fully explained, but it seems to be related to something called the holographic principle, the idea that gravity ties together the inside of space with the boundary around it. T duality, an older concept in string theory, is explained: a consequence of how strings “see” the world in terms of things to wrap around and things to spin around. In my field, one of our favorite dualities links back to this as well, amplitude-Wilson loop duality linked to fermionic T-duality.

The antipode doesn’t twist spacetime, it twists the mathematics. And it may be it matters only because the mathematics is so constrained that it’s forced to happen.

The trick that Lance Dixon and co. used to discover antipodal duality is the same trick I used with Lance to calculate complicated scattering amplitudes. It relies on taking a general guess of words in the right “alphabet”, and constraining it: using mathematical and physical principles it must obey and throwing out every illegal answer until there’s only one answer left.

Currently, there are some hints that the principles used for the different calculations linked by antipodal duality are “antipodal mirrors” of each other: that different principles have the same implication when the duality “flips” them around. If so, then it could be this duality is in some sense just a coincidence: not a coincidence limited to a few calculations, but a coincidence limited to a few principles. Thought of in this way, it might not tell us a lot about other situations, it might not really be “deep”.

Of course, I could be wrong about this. It could be much more general, could mean much more. But in that context, I really have no clue what to speculate. The antipode is weird: it links things that really should not be physically linked. We’ll have to see what that actually means.
Amplitudes 2022 Retrospective

I’m back from Amplitudes 2022 with more time to write, and (besides the several papers I’m working on) that means writing about the conference! Casual readers be warned, there’s no way around this being a technical post, I don’t have the space to explain everything!

I mostly said all I wanted about the way the conference was set up in last week’s post, but one thing I didn’t say much about was the conference dinner. Most conference dinners are the same aside from the occasional cool location or haggis speech. This one did have a cool location, and a cool performance by a blind pianist, but the thing I really wanted to comment on was the setup. Typically, the conference dinner at Amplitudes is a sit-down affair: people sit at tables in one big room, maybe getting up occasionally to pick up food, and eventually someone gives an after-dinner speech. This time the tables were standing tables, spread across several rooms. This was a bit tiring on a hot day, but it did have the advantage that it naturally mixed people around. Rather than mostly talking to “your table”, you’d wander, ending up at a new table every time you picked up new food or drinks. It was a good way to meet new people, a surprising number of which in my case apparently read this blog. It did make it harder to do an after-dinner speech, so instead Lance gave an after-conference speech, complete with the now-well-established running joke where Greta Thunberg tries to get us to fly less.

(In another semi-running joke, the organizers tried to figure out who had attended the most of the yearly Amplitudes conferences over the years. Weirdly, no-one has attended all twelve.)

In terms of the content, and things that stood out:

Nima is getting close to publishing his newest ‘hedron, the surfacehedron, and correspondingly was able to give a lot more technical detail about it. (For his first and most famous amplituhedron, see here.) He still didn’t have enough time to explain why he has to use category theory to do it, but at least he was concrete enough that it was reasonably clear where the category theory was showing up. (I wasn’t there for his eight-hour lecture at the school the week before, maybe the students who stuck around until 2am learned some category theory there.) Just from listening in on side discussions, I got the impression that some of the ideas here actually may have near-term applications to computing Feynman diagrams: this hasn’t been a feature of previous ‘hedra and it’s an encouraging development.

Alex Edison talked about progress towards this blog’s namesake problem, the question of whether N=8 supergravity diverges at seven loops. Currently they’re working at six loops on the N=4 super Yang-Mills side, not yet in a form it can be “double-copied” to supergravity. The tools they’re using are increasingly sophisticated, including various slick tricks from algebraic geometry. They are looking to the future: if they’re hoping their methods will reach seven loops, the same methods have to make six loops a breeze.

Xi Yin approached a puzzle with methods from String Field Theory, prompting the heretical-for-us title “on-shell bad, off-shell good”. A colleague reminded me of a local tradition for dealing with heretics.

While Nima was talking about a new ‘hedron, other talks focused on the original amplituhedron. Paul Heslop found that the amplituhedron is not literally a positive geometry, despite slogans to the contrary, but what it is is nonetheless an interesting generalization of the concept. Livia Ferro has made more progress on her group’s momentum amplituhedron: previously only valid at tree level, they now have a picture that can accomodate loops. I wasn’t sure this would be possible, there are a lot of things that work at tree level and not for loops, so I’m quite encouraged that this one made the leap successfully.

Sebastian Mizera, Andrew McLeod, and Hofie Hannesdottir all had talks that could be roughly summarized as “deep principles made surprisingly useful”. Each took topics that were explored in the 60’s and translated them into concrete techniques that could be applied to modern problems. There were surprisingly few talks on the completely concrete end, on direct applications to collider physics. I think Simone Zoia’s was the only one to actually feature collider data with error bars, which might explain why I singled him out to ask about those error bars later.

Likewise, Matthias Wilhelm’s talk was the only one on functions beyond polylogarithms, the elliptic functions I’ve also worked on recently. I wonder if the under-representation of some of these topics is due to the existence of independent conferences: in a year when in-person conferences are packed in after being postponed across the pandemic, when there are already dedicated conferences for elliptics and practical collider calculations, maybe people are just a bit too tired to go to Amplitudes as well.

Talks on gravitational waves seem to have stabilized at roughly a day’s worth, which seems reasonable. While the subfield’s capabilities continue to be impressive, it’s also interesting how often new conceptual challenges appear. It seems like every time a challenge to their results or methods is resolved, a new one shows up. I don’t know whether the field will ever get to a stage of “business as usual”, or whether it will be novel qualitative questions “all the way up”.

I haven’t said much about the variety of talks bounding EFTs and investigating their structure, though this continues to be an important topic. And I haven’t mentioned Lance Dixon’s talk on antipodal duality, largely because I’m planning a post on it later: Quanta Magazine had a good article on it, but there are some aspects even Quanta struggled to cover, and I think I might have a good way to do it.

At Amplitudes 2022 in Prague

It’s that time of year again! I’m at the big yearly conference of my subfield, Amplitudes, this year in Prague.

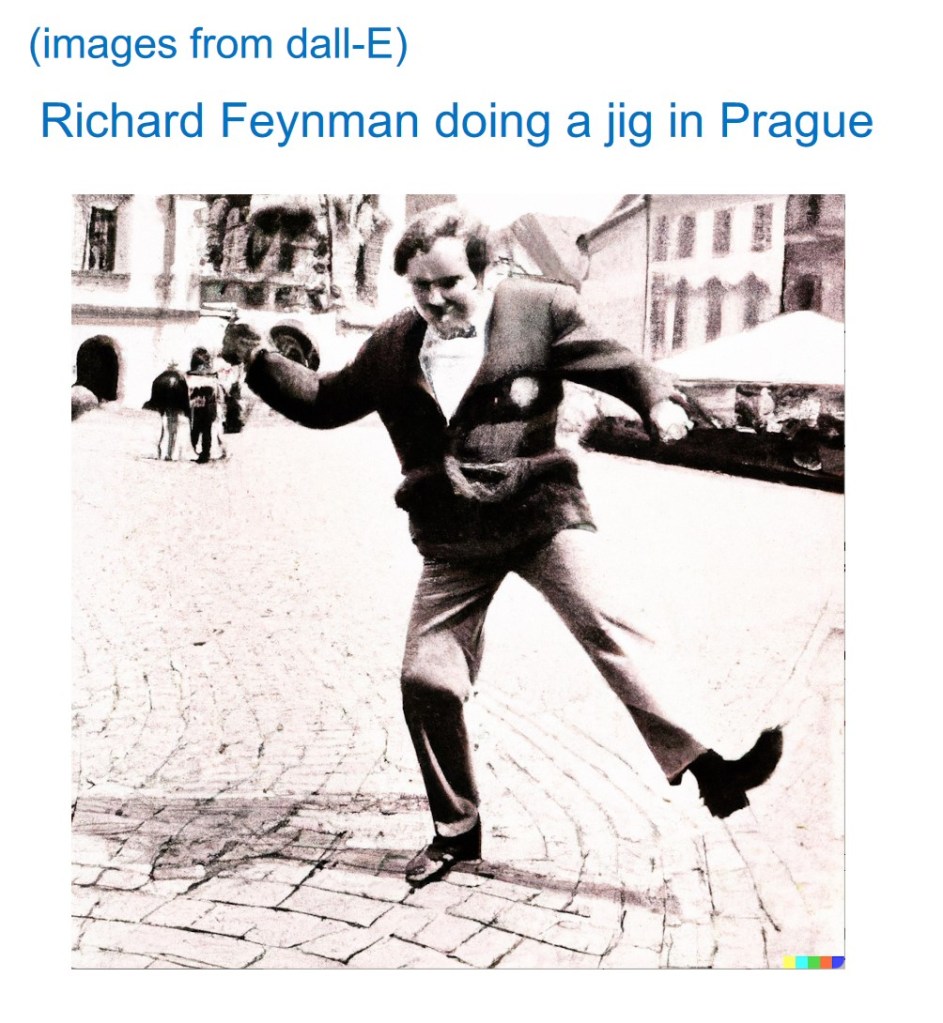
The conference poster included a picture of Prague’s famous clock, which is admittedly cool. But I think this computer-generated anachronism from Matt Schwartz’s machine learning talk is much more fun.

Amplitudes has grown, and keeps growing. The last time we met in person, there were 175 of us. This year, many people are skipping: some avoiding travel due to COVID, others just exhausted from a summer filled with long-postponed conferences. Nonetheless, we have more people here than then: 222 registered participants!

The large number of people means a large number of talks. Almost all were quite short, 25+5 minutes. Some speakers took advantage of the short length to deliver very accessible talks. Others seemed to think of the time limit as an excuse to cut short the introduction and dive right into technical details. We had just a few 40+5 minute talks, each a review from an adjacent field.

It’s been fun seeing people in person again. I think half of my conversations started with “It’s been a long time!” It’s easy for motivation to wane when you don’t have regular contact with the wider field, getting enthusiastic about shared goals and brainstorming big questions.

I’ll probably give a longer retrospective later: the packed schedule means I don’t have much time to write! But I can say that I’ve largely enjoyed this, the organizers were organized and the presenters presented and things felt a bit more like they ought to in the world.

Carving Out the Possible

If you imagine a particle physicist, you probably picture someone spending their whole day dreaming up new particles. They figure out how to test those particles in some big particle collider, and for a lucky few their particle gets discovered and they get a Nobel prize.

Occasionally, a wiseguy asks if we can’t just cut out the middleman. Instead of dreaming up particles to test, why don’t we just write down every possible particle and test for all of them? It would save the Nobel committee a lot of money at least!

It turns out, you can sort of do this, through something called Effective Field Theory. An Effective Field Theory is a type of particle physics theory that isn’t quite true: instead, it’s “effectively” true, meaning true as long as you don’t push it too far. If you test it at low energies and don’t “zoom in” too much then it’s fine. Crank up your collider energy high enough, though, and you expect the theory to “break down”, revealing new particles. An Effective Field Theory lets you “hide” unknown particles inside new interactions between the particles we already know.

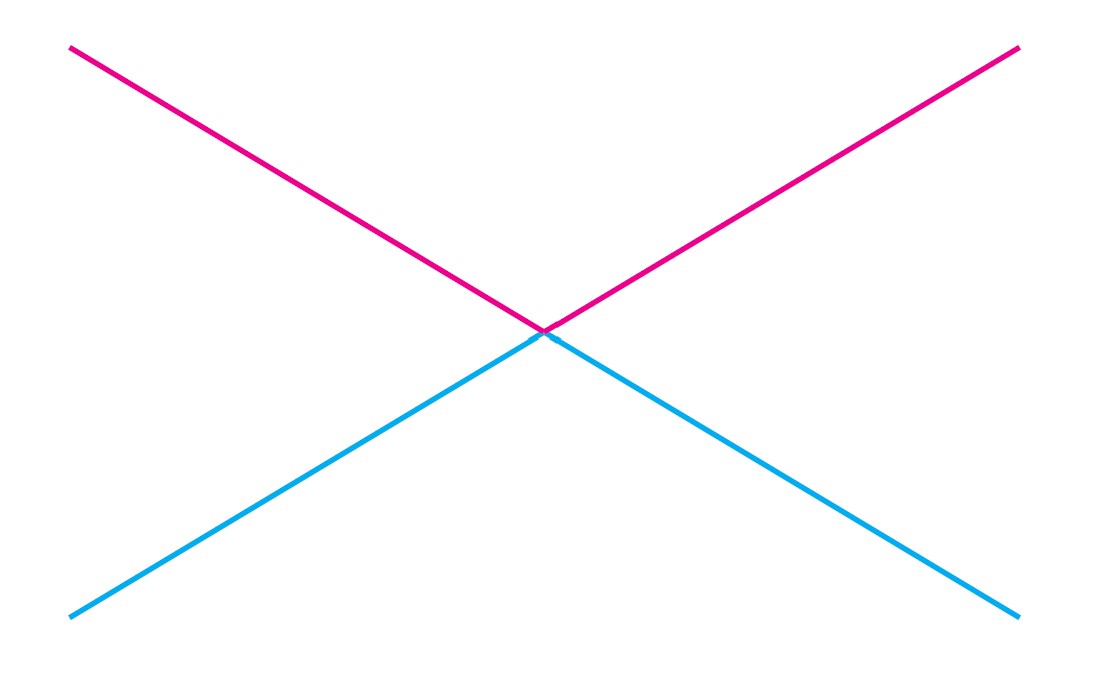
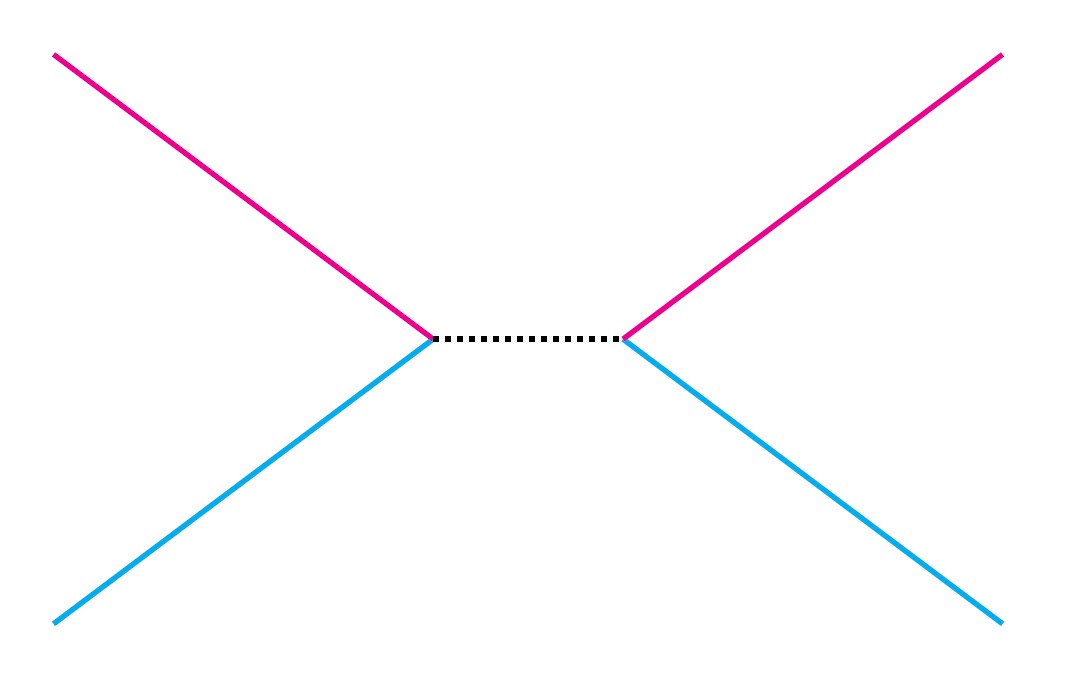
To help you picture how this works, imagine that the pink and blue lines here represent familiar particles like electrons and quarks, while the dotted line is a new particle somebody dreamed up. (The picture is called a Feynman diagram, if you don’t know what that is check out this post.)

In an Effective Field Theory, we “zoom out”, until the diagram looks like this:

Now we’ve “hidden” the new particle. Instead, we have a new type of interaction between the particles we already know.

So instead of writing down every possible new particle we can imagine, we only have to write down every possible interaction between the particles we already know.

That’s not as hard as it sounds. In part, that’s because not every interaction actually makes sense. Some of the things you could write down break some important rules. They might screw up cause and effect, letting something happen before its cause instead of after. They might screw up probability, giving you a formula for the chance something happens that gives a number greater than 100%.

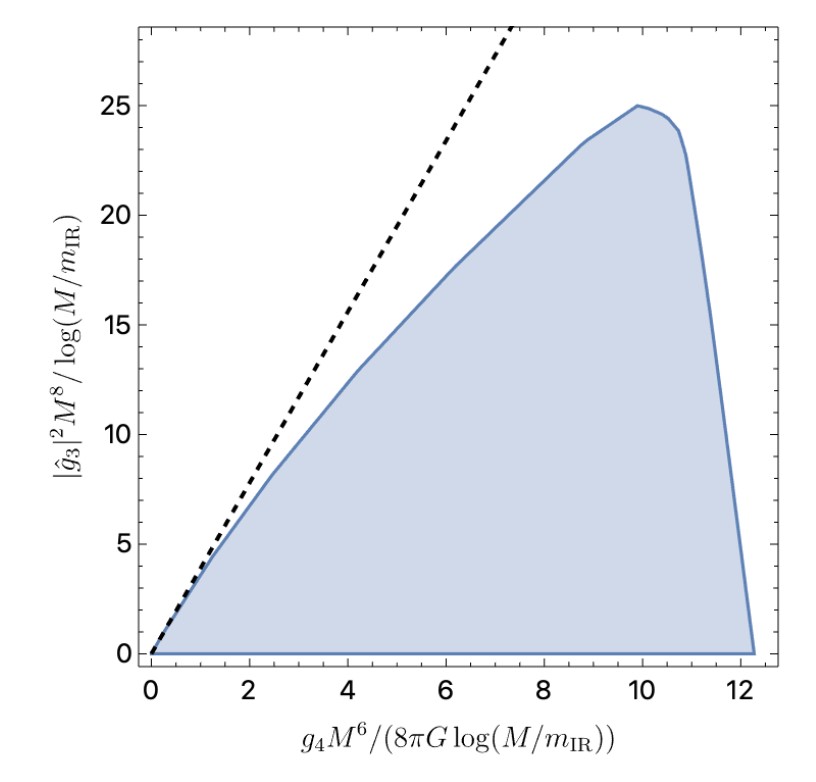
Using these rules you can play a kind of game. You start out with a space representing all of the interactions you can imagine. You begin chipping at it, carving away parts that don’t obey the rules, and you see what shape is left over. You end up with plots that look a bit like carving a ham.

People in my subfield are getting good at this kind of game. It isn’t quite our standard fare: usually, we come up with tricks to make calculations with specific theories easier. Instead, many groups are starting to look at these general, effective theories. We’ve made friends with groups in related fields, building new collaborations. There still isn’t one clear best way to do this carving, so each group manages to find a way to chip a little farther. Out of the block of every theory we could imagine, we’re carving out a space of theories that make sense, theories that could conceivably be right. Theories that are worth testing.

Geometry and Geometry

Last week, I gave the opening lectures for a course on scattering amplitudes, the things we compute to find probabilities in particle physics. After the first class, one of the students asked me if two different descriptions of these amplitudes, one called CHY and the other called the amplituhedron, were related. There does happen to be a connection, but it’s a bit subtle and indirect, not the sort of thing the student would have been thinking of. Why then, did he think they might be related? Well, he explained, both descriptions are geometric.

If you’ve been following this blog for a while, you’ve seen me talk about misunderstandings. There are a lot of subtle ways a smart student can misunderstand something, ways that can be hard for a teacher to recognize. The right question, or the right explanation, can reveal what’s going on. Here, I think the problem was that there are multiple meanings of geometry.

One of the descriptions the student asked about, CHY, is related to string theory. It describes scattering particles in terms of the path of a length of string through space and time. That path draws out a surface called a world-sheet, showing all the places the string touches on its journey. And that picture, of a wiggly surface drawn in space and time, looks like what most people think of as geometry: a “shape” in a pretty normal sense, which here describes the physics of scattering particles.

The other description, the amplituhedron, also uses geometric objects to describe scattering particles. But the “geometric objects” here are much more abstract. A few of them are familiar: straight lines, the area between them forming shapes on a plane. Most of them, though are generalizations of this: instead of lines on a plane, they have higher dimensional planes in higher dimensional spaces. These too get described as geometry, even though they aren’t the “everyday” geometry you might be familiar with. Instead, they’re a “natural generalization”, something that, once you know the math, is close enough to that “everyday” geometry that it deserves the same name.

This week, two papers presented a totally different kind of geometric description of particle physics. In those papers, “geometric” has to do with differential geometry, the mathematics behind Einstein’s theory of general relativity. The descriptions are geometric because they use the same kinds of building-blocks of that theory, a metric that bends space and time. Once again, this kind of geometry is a natural generalization of the everyday notion, but now in once again a different way.

All of these notions of geometry do have some things in common, of course. Maybe you could even write down a definition of “geometry” that includes all of them. But they’re different enough that if I tell you that two descriptions are “geometric”, it doesn’t tell you all that much. It definitely doesn’t tell you the two descriptions are related.

It’s a reasonable misunderstanding, though. It comes from a place where, used to “everyday” geometry, you expect two “geometric descriptions” of something to be similar: shapes moving in everyday space, things you can directly compare. Instead, a geometric description can be many sorts of shape, in many sorts of spaces, emphasizing many sorts of properties. “Geometry” is just a really broad term.

Classicality Has Consequences

Last week, I mentioned some interesting new results in my corner of physics. I’ve now finally read the two papers and watched the recorded talk, so I can satisfy my frustrated commenters.

Quantum mechanics is a very cool topic and I am much less qualified than you would expect to talk about it. I use quantum field theory, which is based on quantum mechanics, so in some sense I use quantum mechanics every day. However, most of the “cool” implications of quantum mechanics don’t come up in my work. All the debates about whether measurement “collapses the wavefunction” are irrelevant when the particles you measure get absorbed in a particle detector, never to be seen again. And while there are deep questions about how a classical world emerges from quantum probabilities, they don’t matter so much when all you do is calculate those probabilities.

They’ve started to matter, though. That’s because quantum field theorists like me have recently started working on a very different kind of problem: trying to predict the output of gravitational wave telescopes like LIGO. It turns out you can do almost the same kind of calculation we’re used to: pretend two black holes or neutron stars are sub-atomic particles, and see what happens when they collide. This trick has grown into a sub-field in its own right, one I’ve dabbled in a bit myself. And it’s gotten my kind of physicists to pay more attention to the boundary between classical and quantum physics.

The thing is, the waves that LIGO sees really are classical. Any quantum gravity effects there are tiny, undetectably tiny. And while this doesn’t have the implications an expert might expect (we still need loop diagrams), it does mean that we need to take our calculations to a classical limit.

Figuring out how to do this has been surprisingly delicate, and full of unexpected insight. A recent example involves two papers, one by Andrea Cristofoli, Riccardo Gonzo, Nathan Moynihan, Donal O’Connell, Alasdair Ross, Matteo Sergola, and Chris White, and one by Ruth Britto, Riccardo Gonzo, and Guy Jehu. At first I thought these were two groups happening on the same idea, but then I noticed Riccardo Gonzo on both lists, and realized the papers were covering different aspects of a shared story. There is another group who happened upon the same story: Paolo Di Vecchia, Carlo Heissenberg, Rodolfo Russo and Gabriele Veneziano. They haven’t published yet, so I’m basing this on the Gonzo et al papers.

The key question each group asked was, what does it take for gravitational waves to be classical? One way to ask the question is to pick something you can observe, like the strength of the field, and calculate its uncertainty. Classical physics is deterministic: if you know the initial conditions exactly, you know the final conditions exactly. Quantum physics is not. What should happen is that if you calculate a quantum uncertainty and then take the classical limit, that uncertainty should vanish: the observation should become certain.

Another way to ask is to think about the wave as made up of gravitons, particles of gravity. Then you can ask how many gravitons are in the wave, and how they are distributed. It turns out that you expect them to be in a coherent state, like a laser, one with a very specific distribution called a Poisson distribution: a distribution in some sense right at the border between classical and quantum physics.

The results of both types of questions were as expected: the gravitational waves are indeed classical. To make this work, though, the quantum field theory calculation needs to have some surprising properties.

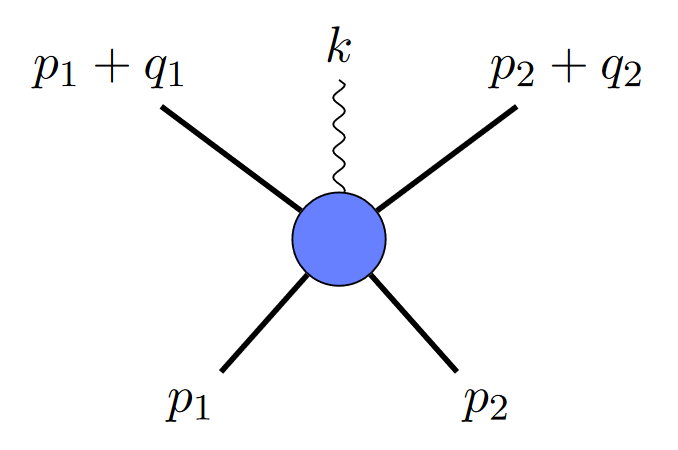
If two black holes collide and emit a gravitational wave, you could depict it like this:

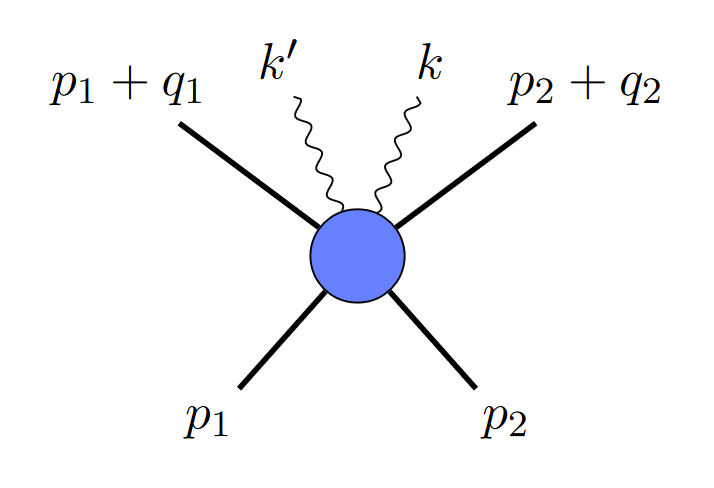
All pictures from arXiv:2112.07556

where the straight lines are black holes, and the squiggly line is a graviton. But since gravitational waves are made up of multiple gravitons, you might ask, why not depict it with two gravitons, like this?

It turns out that diagrams like that are a problem: they mean your two gravitons are correlated, which is not allowed in a Poisson distribution. In the uncertainty picture, they also would give you non-zero uncertainty. Somehow, in the classical limit, diagrams like that need to go away.

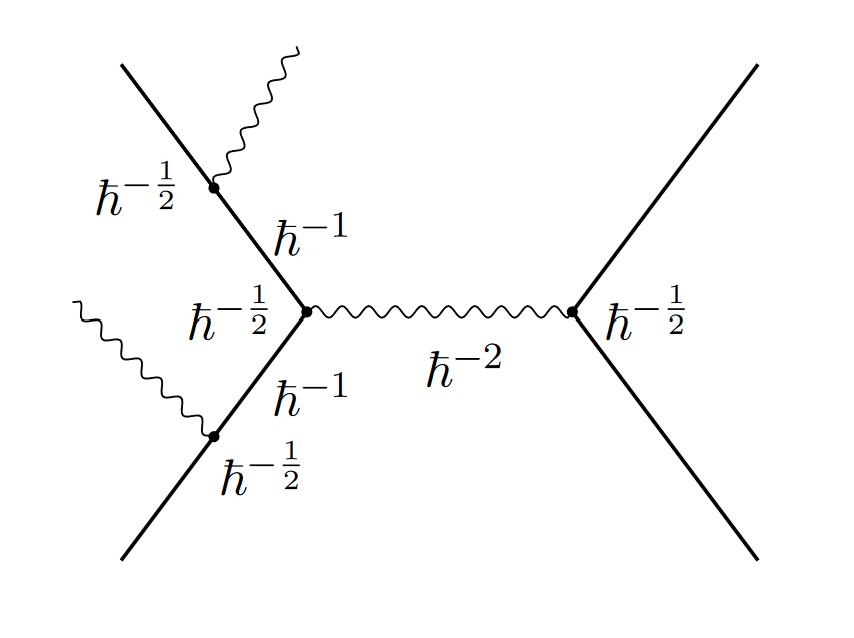
And at first, it didn’t look like they do. You can try to count how many powers of Planck’s constant show up in each diagram. The authors do that, and it certainly doesn’t look like it goes away:

An example from the paper with Planck’s constants sprinkled around

Luckily, these quantum field theory calculations have a knack for surprising us. Calculate each individual diagram, and things look hopeless. But add them all together, and they miraculously cancel. In the classical limit, everything combines to give a classical result.

You can do this same trick for diagrams with more graviton particles, as many as you like, and each time it ought to keep working. You get an infinite set of relationships between different diagrams, relationships that have to hold to get sensible classical physics. From thinking about how the quantum and classical are related, you’ve learned something about calculations in quantum field theory.

That’s why these papers caught my eye. A chunk of my sub-field is needing to learn more and more about the relationship between quantum and classical physics, and it may have implications for the rest of us too. In the future, I might get a bit more qualified to talk about some of the very cool implications of quantum mechanics.

Calculations of the Past

Last week was a birthday conference for one of the pioneers of my sub-field, Ettore Remiddi. I wasn’t there, but someone who was pointed me to some of the slides, including a talk by Stefano Laporta. For those of you who didn’t see my post a few weeks back, Laporta was one of Remiddi’s students, who developed one of the most important methods in our field and then vanished, spending ten years on an amazingly detailed calculation. Laporta’s talk covers more of the story, about what it was like to do precision calculations in that era.

“That era”, the 90’s through 2000’s, witnessed an enormous speedup in computers, and a corresponding speedup in what was possible. Laporta worked with Remiddi on the three-loop electron anomalous magnetic moment, something Remiddi had been working on since 1969. When Laporta joined in 1989, twenty-one of the seventy-two diagrams needed had still not been computed. They would polish them off over the next seven years, before Laporta dove in to four loops. Twenty years later, he had that four-loop result to over a thousand digits.

One fascinating part of the talk is seeing how the computational techniques change over time, as language replaces language and computer clusters get involved. As a student, Laporta learns a lesson we all often need: that to avoid mistakes, we need to do as little by hand as possible, even for something as simple as copying a one-line formula. Looking at his review of others’ calculations, it’s remarkable how many theoretical results had to be dramatically corrected a few years down the line, and how much still might depend on theoretical precision.

Another theme was one of Remiddi suggesting something and Laporta doing something entirely different, and often much more productive. Whether it was using the arithmetic-geometric mean for an elliptic integral instead of Gaussian quadrature, or coming up with his namesake method, Laporta spent a lot of time going his own way, and Remiddi quickly learned to trust him.

There’s a lot more in the slides that’s worth reading, including a mention of one of this year’s Physics Nobelists. The whole thing is an interesting look at what it takes to press precision to the utmost, and dedicate years to getting something right.

Searching for Stefano

On Monday, Quanta magazine released an article on a man who transformed the way we do particle physics: Stefano Laporta. I’d tipped them off that Laporta would make a good story: someone who came up with the bread-and-butter algorithm that fuels all of our computations, then vanished from the field for ten years, returning at the end with an 1,100 digit masterpiece. There’s a resemblance to Searching for Sugar Man, fans and supporters baffled that their hero is living in obscurity.

If anything, I worry I under-sold the story. When Quanta interviewed me, it was clear they were looking for ties to well-known particle physics results: was Laporta’s work necessary for the Higgs boson discovery, or linked to the controversy over the magnetic moment of the muon? I was careful, perhaps too careful, in answering. The Higgs, to my understanding, didn’t require so much precision for its discovery. As for the muon, the controversial part is a kind of calculation that wouldn’t use Laporta’s methods, while the un-controversial part was found numerically by a group that doesn’t use his algorithm either.

With more time now, I can make a stronger case. I can trace Laporta’s impact, show who uses his work and for what.

In particle physics, we have a lovely database called INSPIRE that lists all our papers. Here is Laporta’s page, his work sorted by number of citations. When I look today, I find his most cited paper, the one that first presented his algorithm, at the top, with a delightfully apt 1,001 citations. Let’s listen to a few of those 1,001 tales, and see what they tell us.

Once again, we’ll sort by citations. The top paper, “Higgs boson production at hadron colliders in NNLO QCD“, is from 2002. It computes the chance that a particle collider like the LHC could produce a Higgs boson. It in turn has over a thousand citations, headlined by two from the ATLAS and CMS collaborations: “Observation of a new particle in the search for the Standard Model Higgs boson with the ATLAS detector at the LHC” and “Observation of a New Boson at a Mass of 125 GeV with the CMS Experiment at the LHC“. Those are the papers that announced the discovery of the Higgs, each with more than twelve thousand citations. Later in the list, there are design reports: discussions of why the collider experiments are built a certain way. So while it’s true that the Higgs boson could be seen clearly from the data, Laporta’s work still had a crucial role: with his algorithm, we could reassure experimenters that they really found the Higgs (not something else), and even more importantly, help them design the experiment so that they could detect it.

The next paper tells a similar story. A different calculation, with almost as many citations, feeding again into planning and prediction for collider physics.

The next few touch on my own corner of the field. “New Relations for Gauge-Theory Amplitudes” triggered a major research topic in its own right, one with its own conference series. Meanwhile, “Iteration of planar amplitudes in maximally supersymmetric Yang-Mills theory at three loops and beyond” served as a foundation for my own career, among many others. None of this would have happened without Laporta’s algorithm.

After that, more applications: fundamental quantities for collider physics, pieces of math that are used again and again. In particular, they are referenced again and again by the Particle Data Group, who collect everything we know about particle physics.

Further down still, and we get to specific code: FIRE and Reduze, programs made by others to implement Laporta’s algorithm, each with many uses in its own right.

All that, just from one of Laporta’s papers.

His ten-year magnum opus is more recent, and has fewer citations: checking now, just 139. Still, there are stories to tell there too.

I mentioned earlier 1,100 digits, and this might confuse some of you. The most precise prediction in particle physics has ten digits of precision, the magnetic behavior of the electron. Laporta’s calculation didn’t change that, because what he calculated isn’t the only contribution: he calculated Feynman diagrams with four “loops”, which is its own approximation, one limited in precision by what might be contributed by more loops. The current result has Feynman diagrams with five loops as well (known to much less than 1,100 digits), but the diagrams with six or more are unknown, and can only be estimated. The result also depends on measurements, which themselves can’t reach 1,100 digits of precision.

So why would you want 1,100 digits, then? In a word, mathematics. The calculation involves exotic types of numbers called periods, more complicated cousins of numbers like pi. These numbers are related to each other, often in complicated and surprising ways, ways which are hard to verify without such extreme precision. An older result of Laporta’s inspired the physicist David Broadhurst and mathematician Anton Mellit to conjecture new relations between this type of numbers, relations that were only later proven using cutting-edge mathematics. The new result has inspired mathematicians too: Oliver Schnetz found hints of a kind of “numerical footprint”, special types of numbers tied to the physics of electrons. It’s a topic I’ve investigated myself, something I think could lead to much more efficient particle physics calculations.

In addition to being inspired by Laporta’s work, Broadhurst has advocated for it. He was the one who first brought my attention to Laporta’s story, with a moving description of welcoming him back to the community after his ten-year silence, writing a letter to help him get funding. I don’t have all the details of the situation, but the impression I get is that Laporta had virtually no academic support for those ten years: no salary, no students, having to ask friends elsewhere for access to computer clusters.

When I ask why someone with such an impact didn’t have a professorship, the answer I keep hearing is that he didn’t want to move away from his home town in Bologna. If you aren’t an academic, that won’t sound like much of an explanation: Bologna has a university after all, the oldest in the world. But that isn’t actually a guarantee of anything. Universities hire rarely, according to their own mysterious agenda. I remember another colleague whose wife worked for a big company. They offered her positions in several cities, including New York. They told her that, since New York has many universities, surely her husband could find a job at one of them? We all had a sad chuckle at that.

For almost any profession, a contribution like Laporta’s would let you live anywhere you wanted. That’s not true for academia, and it’s to our loss. By demanding that each scientist be able to pick up and move, we’re cutting talented people out of the field, filtering by traits that have nothing to do with our contributions to knowledge. I don’t know Laporta’s full story. But I do know that doing the work you love in the town you love isn’t some kind of unreasonable request. It’s a request academia should be better at fulfilling.

In Uppsala for Elliptics 2021

I’m in Uppsala in Sweden this week, at an actual in-person conference.

With actual blackboards!

Elliptics started out as a series of small meetings of physicists trying to understand how to make sense of elliptic integrals in calculations of colliding particles. It grew into a full-fledged yearly conference series. I organized last year, which naturally was an online conference. This year though, the stage was set for Uppsala University to host in person.

I should say mostly in person. It’s a hybrid conference, with some speakers and attendees joining on Zoom. Some couldn’t make it because of travel restrictions, or just wanted to be cautious about COVID. But seemingly just as many had other reasons, like teaching schedules or just long distances, that kept them from coming in person. We’re all wondering if this will become a long-term trend, where the flexibility of hybrid conferences lets people attend no matter their constraints.

The hybrid format worked better than expected, but there were still a few kinks. The audio was particularly tricky, it seemed like each day the organizers needed a new microphone setup to take questions. It’s always a little harder to understand someone on Zoom, especially when you’re sitting in an auditorium rather than focused on your own screen. Still, technological experience should make this work better in future.

Content-wise, the conference began with a “mini-school” of pedagogical talks on particle physics, string theory, and mathematics. I found the mathematical talks by Erik Panzer particularly nice, it’s a topic I still feel quite weak on and he laid everything out in a very clear way. It seemed like a nice touch to include a “school” element in the conference, though I worry it ate too much into the time.

The rest of the content skewed more mathematical, and more string-theoretic, than these conferences have in the past. The mathematical content ranged from intriguing (including an interesting window into what it takes to get high-quality numerics) to intimidatingly obscure (large commutative diagrams, category theory on the first slide). String theory was arguably under-covered in prior years, but it felt over-covered this year. With the particle physics talks focusing on either general properties with perhaps some connections to elliptics, or to N=4 super Yang-Mills, it felt like we were missing the more “practical” talks from past conferences, where someone was computing something concrete in QCD and told us what they needed. Next year is in Mainz, so maybe those talks will reappear.

Stop Listing the Amplituhedron as a Competitor of String Theory

The Economist recently had an article (paywalled) that meandered through various developments in high-energy physics. It started out talking about the failure of the LHC to find SUSY, argued this looked bad for string theory (which…not really?) and used it as a jumping-off point to talk about various non-string “theories of everything”. Peter Woit quoted it a few posts back as kind of a bellwether for public opinion on supersymmetry and string theory.

The article was a muddle, but a fairly conventional muddle, explaining or mis-explaining things in roughly the same way as other popular physics pieces. For the most part that didn’t bug me, but one piece of the muddle hit a bit close to home:

The names of many of these [non-string theories of everything] do, it must be conceded, torture the English language. They include “causal dynamical triangulation”, “asymptotically safe gravity”, “loop quantum gravity” and the “amplituhedron formulation of quantum theory”.

I’ve posted about the amplituhedron more than a few times here on this blog. Out of every achievement of my sub-field, it has most captured the public imagination. It’s legitimately impressive, a way to translate calculations of probabilities of collisions of fundamental particles (in a toy model, to be clear) into geometrical objects. What it isn’t, and doesn’t pretend to be, is a theory of everything.

To be fair, the Economist piece admits this:

Most attempts at a theory of everything try to fit gravity, which Einstein describes geometrically, into quantum theory, which does not rely on geometry in this way. The amplituhedron approach does the opposite, by suggesting that quantum theory is actually deeply geometric after all. Better yet, the amplituhedron is not founded on notions of spacetime, or even statistical mechanics. Instead, these ideas emerge naturally from it. So, while the amplituhedron approach does not as yet offer a full theory of quantum gravity, it has opened up an intriguing path that may lead to one.

The reasoning they have leading up to it has a few misunderstandings anyway. The amplituhedron is geometrical, but in a completely different way from how Einstein’s theory of gravity is geometrical: Einstein’s gravity is a theory of space and time, the amplituhedron’s magic is that it hides space and time behind a seemingly more fundamental mathematics.

This is not to say that the amplituhedron won’t lead to insights about gravity. That’s a big part of what it’s for, in the long-term. Because the amplituhedron hides the role of space and time, it might show the way to theories that lack them altogether, theories where space and time are just an approximation for a more fundamental reality. That’s a real possibility, though not at this point a reality.

Even if you take this possibility completely seriously, though, there’s another problem with the Economist’s description: it’s not clear that this new theory would be a non-string theory!

The main people behind the amplituhedron are pretty positively disposed to string theory. If you asked them, I think they’d tell you that, rather than replacing string theory, they expect to learn more about string theory: to see how it could be reformulated in a way that yields insight about trickier problems. That’s not at all like the other “non-string theories of everything” in that list, which frame themselves as alternatives to, or even opponents of, string theory.

It is a lot like several other research programs, though, like ER=EPR and It from Qubit. Researchers in those programs try to use physical principles and toy models to say fundamental things about quantum gravity, trying to think about space and time as being made up of entangled quantum objects. By that logic, they belong in that list in the article alongside the amplituhedron. The reason they aren’t is obvious if you know where they come from: ER=EPR and It from Qubit are worked on by string theorists, including some of the most prominent ones.

The thing is, any reason to put the amplituhedron on that list is also a reason to put them. The amplituhedron is not a theory of everything, it is not at present a theory of quantum gravity. It’s a research direction that might shed new insight about quantum gravity. It doesn’t explicitly involve strings, but neither does It from Qubit most of the time. Unless you’re going to describe It from Qubit as a “non-string theory of everything”, you really shouldn’t describe the amplituhedron as one.

The amplituhedron is a really cool idea, one with great potential. It’s not something like loop quantum gravity, or causal dynamical triangulations, and it doesn’t need to be. Let it be what it is, please!